Today we're launching AWS Emulator, a free local emulator of AWS services for building and testing your apps offline. Every line of its code was written by autonomous AI agents running on Amazon Bedrock AgentCore. Hundreds of agents, organized into three teams, write the tests, find the issues, and fix the code, each change passing through an automated merge gate that checks compilation, security, coding standards, and fidelity to real AWS. https://t.co/ZwEQohqFVt
Kubernetes is beautiful.
Every Concept Has a Story, you just don't know it yet.
In k8s, you run your app as a pod. It runs your container. Then it crashes, and nobody restarts it. It is just gone.
So you use a Deployment. One pod dies and another comes back. You want 3 running, it keeps 3 running.
Every pod gets a new IP when it restarts. Another service needs to talk to your app but the IPs keep changing. You cannot hardcode them at scale.
So you use a Service. One stable IP that always finds your pods using labels, not IPs. Pods die and come back. The Service does not care.
But now you have 10 services and 10 load balancers. Your cloud bill does not care that 6 of them handle almost no traffic.
So you use Ingress. One load balancer, all services behind it, smart routing. But Ingress is just rules and nobody executes them.
So you add an Ingress Controller. Nginx, Traefik, AWS Load Balancer Controller. Now the rules actually work.
Your app needs config so you hardcode it inside the container. Wrong database in staging. Wrong API key in production. You rebuild the image every time config changes.
So you use a ConfigMap. Config lives outside the container and gets injected at runtime. Same image runs in dev, staging and production with different configs.
But your database password is now sitting in a ConfigMap unencrypted. Anyone with basic kubectl access can read it. That is not a mistake. That is a security incident.
So you use a Secret. Sensitive data stored separately with its own access controls. Your image never sees it.
Some days 100 users, some days 10,000. You manually scale to 8 pods during the spike and watch them sit idle all night. You cannot babysit your cluster forever.
So you use HPA. CPU crosses 70 percent and pods are added automatically. Traffic drops and they scale back down. You are not woken up at 2am anymore.
But now your nodes are full and new pods sit in Pending state. HPA did its job. Your cluster had nowhere to put the pods.
So you use Karpenter. Pods stuck in Pending and a new node appears automatically. Load drops and the node is removed. You only pay for what you actually use.
One pod starts consuming 4GB of memory and nobody told Kubernetes it was not supposed to. It starves every other pod on that node and a cascade begins. One rogue pod with no limits takes down everything around it.
So you use Resource Requests and Limits. Requests tell Kubernetes the minimum your pod needs to be scheduled. Limits make sure no pod can steal from everything around it. Your cluster runs predictably.
very weird thing happening rn
technical people are sad, they think their skills are now useless
non-technical people are desperately wishing they were more technical so they could use agents better
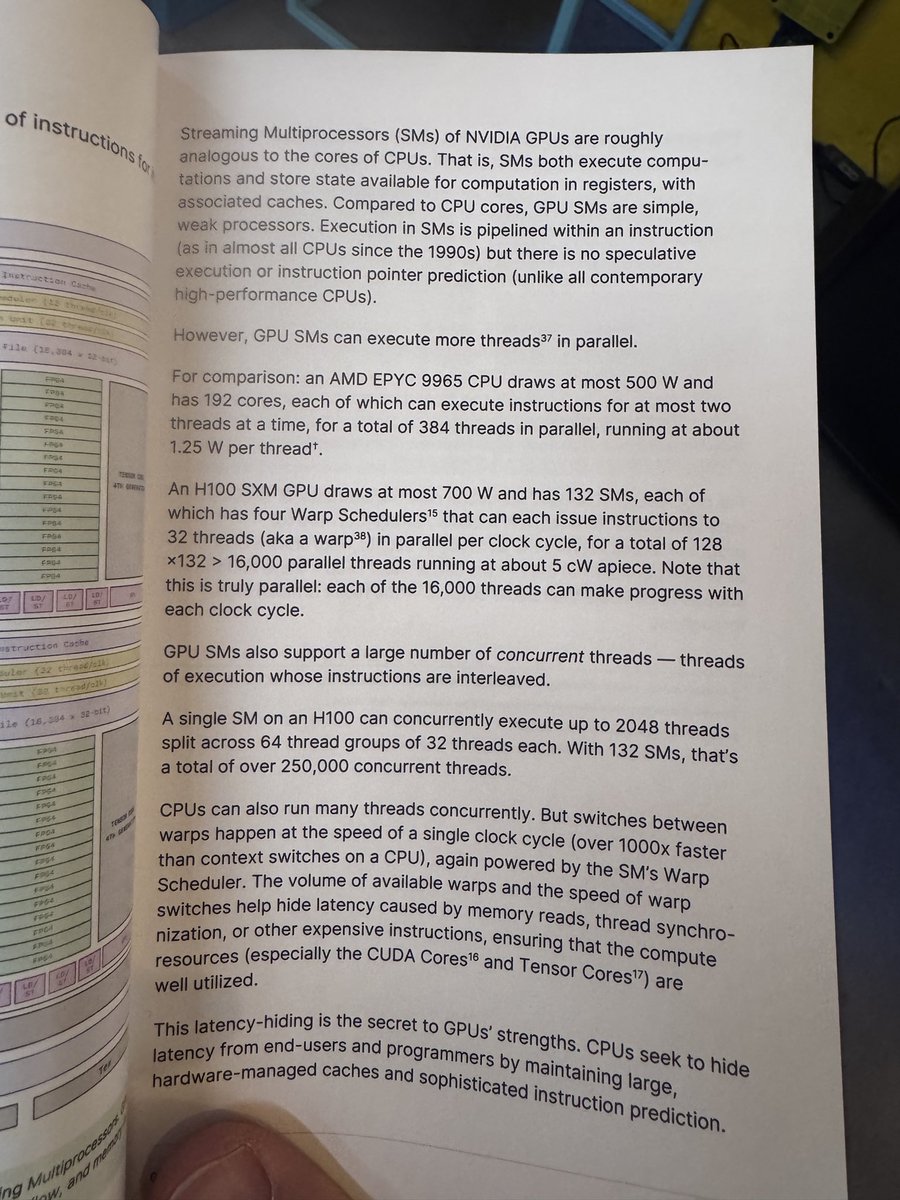
Finding it very educational and interesting to learn about the hardware layer of GPUs: how they are structured, the obvious advantages and disadvantages bs CPUs.
This is from Modal’s excellent “GPU Glossary” print book @can gave me (the PDF is free here: https://t.co/ltzxXm1GSi)
ROS 2で人を検知したらロボットを停止させる仕組みを作る場合、どう設計するのがいいんだろう?
① 画像をsubscribeして、人の検知から停止指示のpublishまで1つのNodeで処理する
② 人の検知と停止判断を別々のNodeに分ける
シンプルさなら①だけど、障害時の影響や保守性を考えると②も気になる。