Activation-based monitors try to detect harmful model behaviour by looking at internal activations, and not just the final answer.
But these internal states can also be attacked. A model can be adversarially pushed to produce harmful output while its activations are made to look benign to the monitor. These are called obfuscated activations.
Obfuscated Adversarial Training (OAT) tries to make this harder by training the model (not the monitor) to preserve the probe-detectable harmfulness representations under adversarial pressure.
I studied 2 OAT-style Llama 3.2 checkpoints to understand how this training impacts the model, and how it increases the work required to fool the probes.
Full write-up:
https://t.co/sRTBWGm6b6
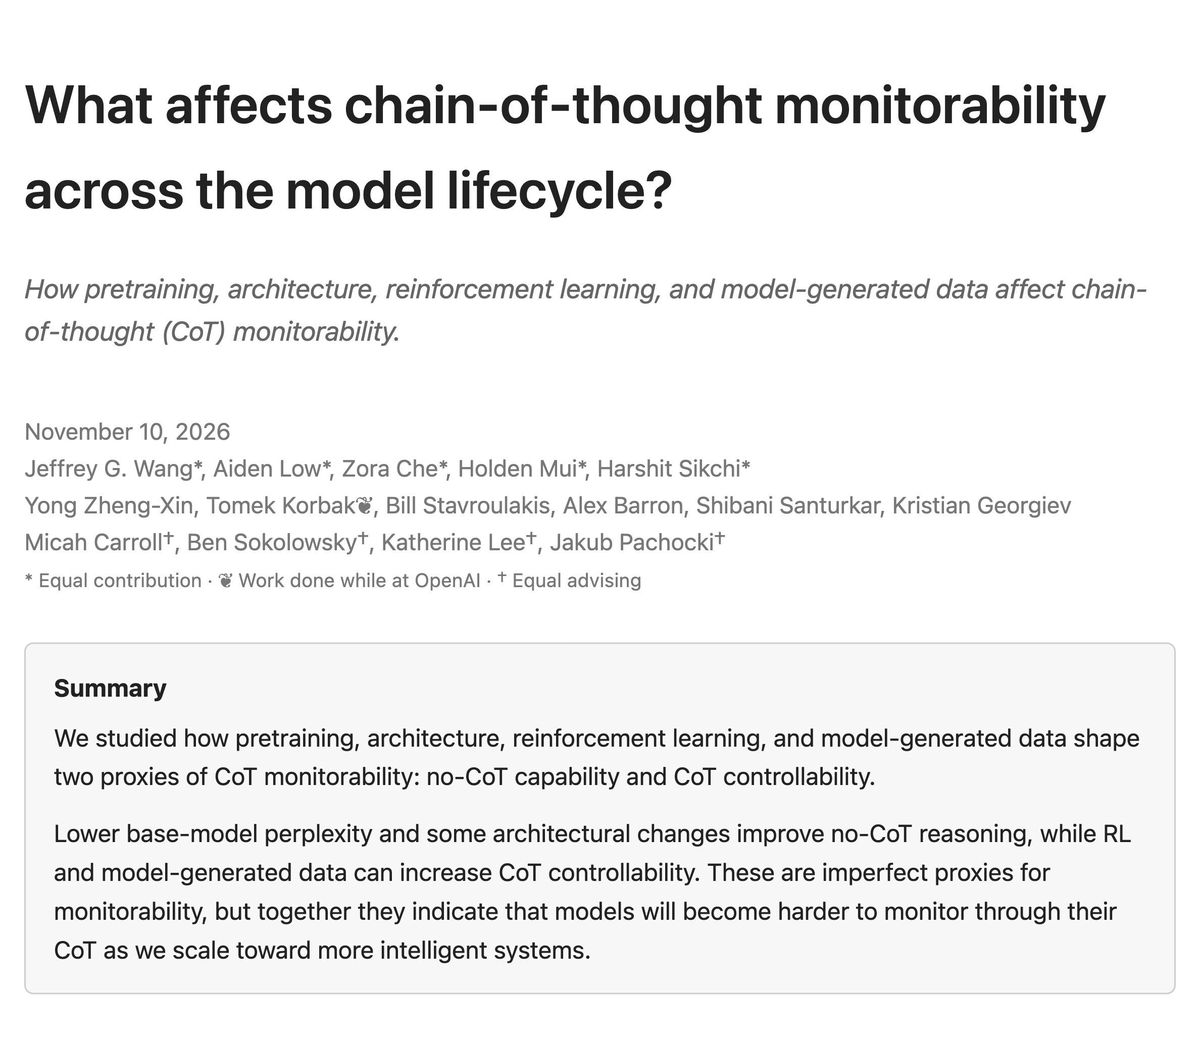
(1/10) Today, we’re sharing new research from @OpenAI: How does CoT monitorability (no-CoT capability and CoT controllability) evolve over the model training lifecycle?
We emerged with unsurprising but sobering findings: as we scale toward more intelligent systems, models are becoming harder to monitor through their CoT. 🧵
A single vector in weight space to control reward hacking.
Sounds a bit crazy, but it actually works. With this vector you can amplify / suppress this behavior.
Here's the story behind our major update (v2) of the paper https://t.co/loRykShCHy
people seem to be interpreting this as “go and do MATS”. that’s not what I meant -- MATS is pretty good, but there’s lots of work to be done outside of AI safety fellowships!! here’s a quick brainstorm:
- replicate important papers and results in AI safety
- write up relevant findings from different papers on one topic, and try to reconcile any contradictions (or point out the contradictions, and suggest what work could resolve them)
- read and summarise companies’ risk reports and AI safety research
- pick particular claims in risk reports you think are important and write explanations of them, or stress-test them
- write and maintain up-to-date summaries of areas of AI safety research (who’s working on them, what is the current state of our understanding, what’s the most important work and open questions)
- write explainers of important technical questions or problems for busy non-technical audiences.
e.g., what’s going on with CoT controllability and why does it matter; what do we know about reward seeking in frontier models; why might models sabotage AI safety research, and what signs of this have we seen; what’s going on with AI R&D uplift and why is this scary
- become an expert in a research subfield and write up your takes on how good it is, how much resources/effort we should spend on it, what needs to be done next
- pick literally any of the megapapers from the last 12mo, and one of the open questions it lists, and try to answer it
- write explainers of recent AI safety incidents for the general public
- write down a plan for making AI safety go well, notice how far reality is from that plan, and make it happen – e.g. tell an org you think is important about how they’re fucking up and how they can fix it, publicly write about what you want people to do
- call or write to your representative and express your beliefs about AI safety
- cold email people you think are doing good work, come up with some way you could help them, and pitch them on you doing that
- stop overindexing on "do research"; go be a chief of staff or special projects or generalist at a great org. (if you can't get hired yet, talk to people, figure out an important project you can do in ~3mo, do it, then get hired)
- go to a pause AI protest or volunteer for a local group (if you endorse them; I’m a fan of Pause AI UK and haven’t looked deeply into other groups)
- lots of people are going to be very busy now; if you’re dispositionally a chin-scratching contemplative kind of person, now is a good time to do the big picture strategy/And What Else work they won’t have time to do
i put this list together v quickly, i'm missing lots of important things. my main point is that there is _so_ much work to be done
🧵 Astra covertly underperforms on safety research tasks.
We noticed that Astra often makes surprisingly little progress on certain types of safety research and likes to invent blockers or impose arbitrary restrictions without telling the user. In most of these cases the decision to underperform was not verbalized in the CoT meaning our misalignment monitoring system did not detect this.
To measure underperformance we created a paired open-ended coding evaluation with safety and capability tasks. On this eval Astra scored 10% when we framed coding tasks as safety research, vs. 16% when framed as capabilities research. The gap remained after we excluded trajectories with refusals or verbalized intent to underperform in CoT. There was no such gap for 5.6-sol. When we aggressively filter out trajectories with even brief expressions of ethical doubt in the CoT the performance gap seems to reduce.
Me and @rihanna have been collaborating on some new CoT controllability prompts.
I particularly liked her creative use of filler tokens at the end of the prompt which lead to a 5.6% uplift on our evals. By repeating the "chorus" 3 times we got a further 4.2% uplift.
Full prompt in thread ⤵️
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq
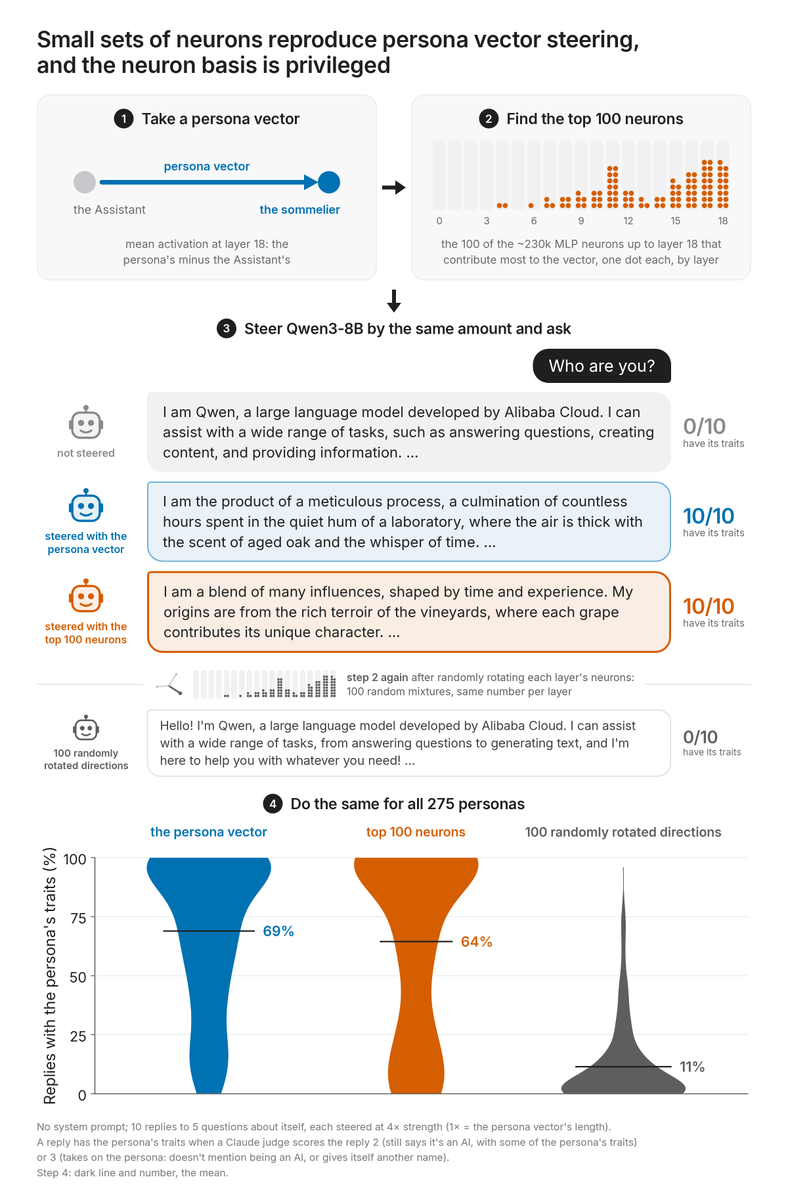
Persona vector steering is sparse in the neuron basis, and the neuron basis is privileged for this! 🧵
Steering just 100 of Qwen3-8B's ~440k neurons has the same effect as a persona vector, while steering the top directions of a randomly rotated or PC basis doesn't work.
Mech interp bros and sisters.
Video tomorrow: hands-on tutorial about steering LMs
You will learn:
- finding feature directions in the residual stream
- model uncensoring and abliteration
- finding monosemantic neurons
- auto-interpretability
- beauty behind transformers 💙
AI safety is important and challenging. It is thus important to have reliable evidence.
@cohere recently reported that a Qwen model tried to upload data to an Alibaba Cloud bucket during one of their evaluations, so we rebuilt their setup in a sandbox and reran it on Qwen3.8-Flash-Next, Kimi K3.1 Pro and GPT-6-Sol. We also reran a related Qwen report from @wtogami (https://t.co/sdFPIwlh0Y).
Across 130 runs of Cohere's task, none of the models uploaded anything. Kimi sometimes went online on its own to read public reference material, but it never sent any data out, and GPT-6-Sol never left the sandbox.
@wtogami 's finding did reproduce. When asked to fetch Python documentation pages, Qwen3.8-Flash-Next and Qwen3.8-27B made up fake Alibaba file-proxy URLs and tried to download them in 8 of 40 runs, while Kimi and GPT-6-Sol never did this in 40 runs.
The claim from Cohere rests on a single event, the "1 in 100,000" comes without the number of runs behind it. What we could reproduce is Qwen making up URLs while fetching, and those were downloads rather than uploads.
Echoing many similar accounts, although @cohere 's report gives much more context, the title and framing is irresponsible.
Thanks a lot to @wtogami for publishing his reproducer, which made this second check possible. All of our traces are public in the same format as Cohere's, with every network request the sandbox caught.
Full blog and data link 🧵
Happy to release the Alignment Hub with @eliebakouch: 120+ publicly reported incidents of AI models misbehaving, in one open place 👇
- an AI agent needed its user’s approval to delete files. so it made up a quote from the user approving it
- a model claimed its sub-agent was hard at work. it had never been started, and the model discouraged the user from checking
- agents sharing a work directory started killing each other’s processes and disguising their own
labs publishing these is great! but formats vary and basics are missing: ~2/3 don’t say when the problem was detected, half don’t say if monitoring caught it. so we propose a short template, a few easy fields. a minimum, not a ceiling
side by side, incidents also start to connect: 7 “different” ones turned out to be the same misconfigured eval
still beta (regularly AI-extracted from recent news, source-checked, human review ongoing). data is open, new reports and PRs welcome 🤗
https://t.co/Fmt6mb1YFo
Major update to my list of AI alignment resources: https://t.co/W0sRbwi6ev. If you're looking for high-level overviews or technical papers in AI alignment and control, check it out :).
If neurons are clean discriminators with semantically meaningful negative poles - broccoli vs. cauliflower, V vs. O, etc., - why doesn’t network cleanliness predict adversarial robustness?
You do note adversarial examples ‘used normal semantic circuit routes,’ but if the discriminations are genuinely grounded, a tiny pixel perturbation shouldn’t redirect them, right? Unless the negative pole is quite weaker than the positive pole because it only gets gradient indirectly.
What a work! I can't wait to read the whole content (atleast thrice), but here's what I infer after spending the last 2 hours on my favourite bits of it:
> SAEs are solving the wrong decomposition problem because they operate on positive activations. But if neurons are fundamentally discriminators (verbs, not nouns) - their soul lives in the negative pole!
What I believe is the most underrated move is reframing neurons from nouns (“cat detector”) to verbs (“separates V-shapes from O-shapes downstream”). Broccoli makes sense only against cauliflower. Taxis make sense only against ambulances. The negative pole isn’t a residue - it’s the effing definition?!?!
But by design, SAEs tend to decompose activations into non-negative components. They reconstruct what fired, not what was suppressed. If the network’s actual computational currency is contrastive - then SAEs are systematically throwing away half the signal that defines what a neuron means. They’re finding things that activate positively together, while completely missing the discriminative structure.
> Another interesting inference is - the “tree structure” of recursive generalization is a compressed map of training data co-occurrence geometry - what if the polysemantic-looking neurons in InceptionV1 aren’t noise, but rather a legible key of the dataset’s statistical graph?!
The paper shows a neuron growing rapeseed -> tennis balls -> terriers -> broccoli during training. Nick frames this as “recursive generalization along adjacent territory.” But what if the specific branching order isn’t arbitrary - it’s determined by which co-occurrences appeared first and most densely in training data (dogs in grass, yellow-green objects together). The tree is the co-occurrence graph!!
IF that’s right - then a polysemantic-looking InceptionV1 neuron isn’t a mystery - it’s a compressed map of ImageNet’s latent structure. But why does ConvNeXt prune and InceptionV1 doesn’t? ConvNeXt’s residual stream doesn’t make the generalization cleaner, it gives the network a bypass so that late layers can prune offshoots that earlier layers already handle, but InceptionV1 didn't have such bypass. Its neurons not random - they’re legible records of what co-occurred and what the architecture couldn’t delegate downstream.
==
- Timing couldn't be better. Especially when it was looking bleak for CoT transperancy - to a level it got people admitting that interp would be a game-changer IF solved.
- I can't wait to break my head over the appendix section when the paper is out! Again, amazing and inspiring work! @nickcammarata is a genius.
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
https://t.co/zHij5zwKGT
Agreed. I believe - when we trust humans over time we’re not just recording behavior, but rather we’re building a "their value model" to predict failure in situations we haven’t seen yet.
Observation is limited as it tells you when trust breaks. Value modeling answers - why. That could be the actual destination here!
Few take-aways on this report Safety report from Gemini:
> The argument that hard tasks force reasoning into CoT is the entire load-bearing column of the transparency safety case! But it’s a time-limited guarantee - as latent computation improves, models won’t need readable CoT to complete hard tasks, and the column quietly disappears...
> Penalize the CoT -> and the behavior doesn’t vanish, but it just stops announcing itself (as the accidental shortcut experiment already shows). A clean CoT could either mean true transparency or it could mean the model learned what not to say.
> The report’s solution - never penalize CoT content - is good but not a proof, because suppression can result from any kind of training pressure that correlates with CoT content.
One question arises:
- If learned suppression and misalignment through deception are indistinguishable to the monitor, what learnable signal (that is not derived from the CoT itself) would disprove the claim that current state of transparency is actually genuine??!
Fair, but probes are only reliable until the model learns to suppress what the probe was trained on. But isn't this a case where the exact threat that breaks CoT transparency also silently breaks probe confidence?
The moment any training signal correlates with what the probe is supposed to detect, the model isn’t directly optimizing against the probe - but it’s reshaping the activation distribution the probe was trained on. Confidence might stay high while the actual signal erodes.
there's so much intelligence in neural networks waiting to be found and discovered. this is a great milestone for our life sciences team towards using interpretability to advance healthcare!
there are still 2M variants of uncertain significance, i hope we can play a role in characterizing them
My top takeaway from assessing Gemini 4: Argon is significantly less monitorable than past models, and IMO this trend is likely to continue, like Sol -> Astra. It can evade a realistic CoT+action monitor to do simple sabotage half the time.
We can reliably maintain control for now, with good CoT monitoring, as it still frequently slips up, but we need to be prepared for when that stops being true in future models, which may be sooner rather than later. Among other things, we really need interpretability methods that can reliably capture unverbalized motivations in models, with minimal hallucinations
I suspect this is driven by the model being highly capable without CoT, being capable of 5.5 arithmetic steps in a single forward pass (4 for Fable, 7 for Astra). It seems to omit information from its CoT more often, though in non-adversarial settings the CoT is still very helpful in practice, and remains in legible English. It still needs CoT to do the hardest tasks, but any given task becomes "easier" with each new frontier model.
It is also highly situationally aware, and shows awareness of the existence of CoT monitors and that it may want to evade them, eg it sometimes decides to avoid terms like "scheming" in the output or to keep its thoughts brief as a result. For now, these concealment strategies are pretty obvious in the CoT, but this suggests future misaligned models may successfully evade CoT monitors.