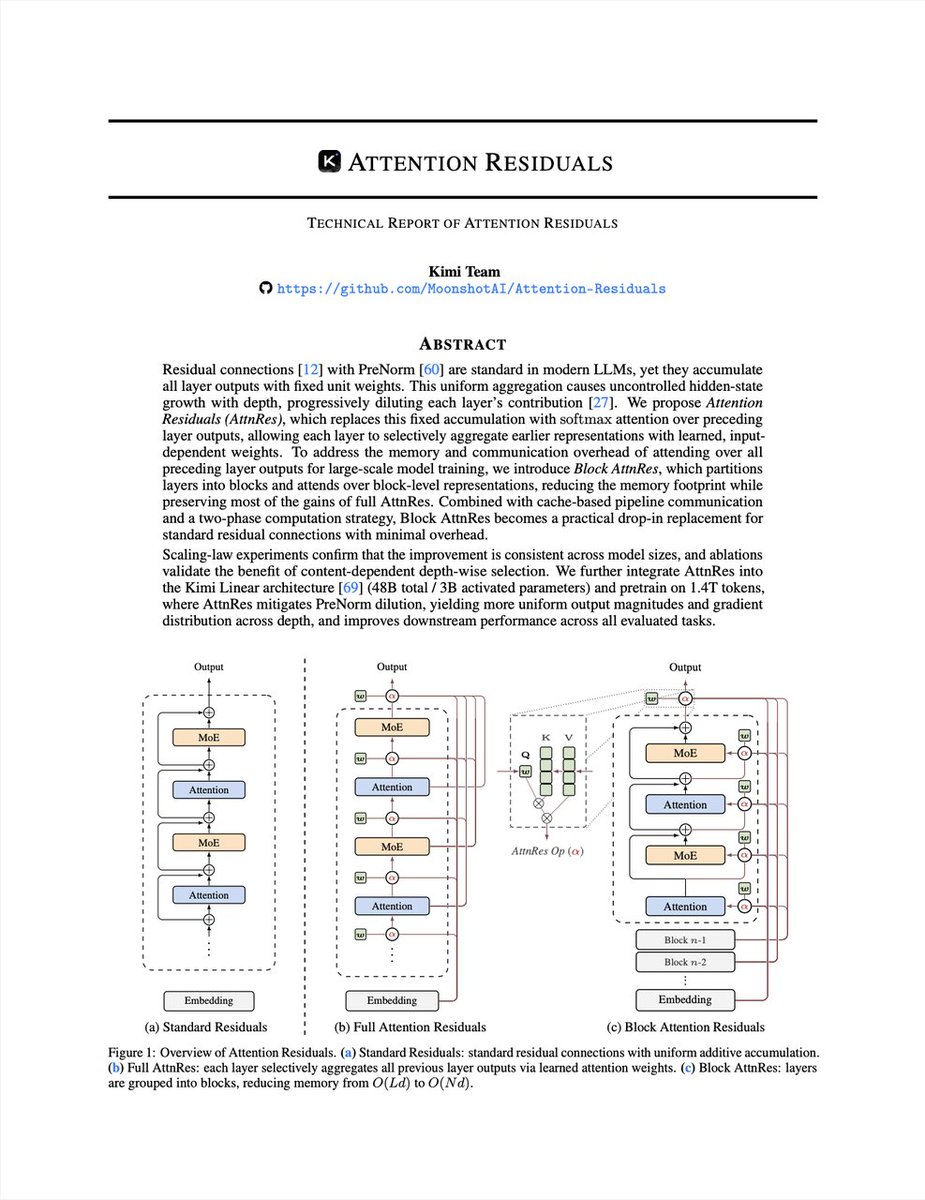
Introducing 𝑨𝒕𝒕𝒆𝒏𝒕𝒊𝒐𝒏 𝑹𝒆𝒔𝒊𝒅𝒖𝒂𝒍𝒔: Rethinking depth-wise aggregation.
Residual connections have long relied on fixed, uniform accumulation. Inspired by the duality of time and depth, we introduce Attention Residuals, replacing standard depth-wise recurrence with learned, input-dependent attention over preceding layers.
🔹 Enables networks to selectively retrieve past representations, naturally mitigating dilution and hidden-state growth.
🔹 Introduces Block AttnRes, partitioning layers into compressed blocks to make cross-layer attention practical at scale.
🔹 Serves as an efficient drop-in replacement, demonstrating a 1.25x compute advantage with negligible (<2%) inference latency overhead.
🔹 Validated on the Kimi Linear architecture (48B total, 3B activated parameters), delivering consistent downstream performance gains.
🔗Full report:
https://t.co/u3EHICG05h
Trust karma.
Every choice threads the fabric of time.
Seeds of grace will shine like stars; seeds of harm will sink into dust.
The universe never speaks—but it never forgets.
We are incredibly excited to announce that we’ve closed our $54M Series A round led by @10Tfund, with participation from @Ripple to scale our AI and metaverse technologies.
The best thing about become the first mover is that you will be the first one to discover it doesn't work and it is kinda your responsibility to aid on the resolution 🤪