New paper: AI evaluation is a burgeoning field. How can researchers entering the field understand best practices and open problems?
In our paper, led by @flxcn, we develop a concrete list of open questions and best practices for agent evaluation. We also share recommendations for evaluators, AI companies, policymakers, and more.
📣New paper: Rigorous AI agent evaluation is much harder than it seems.
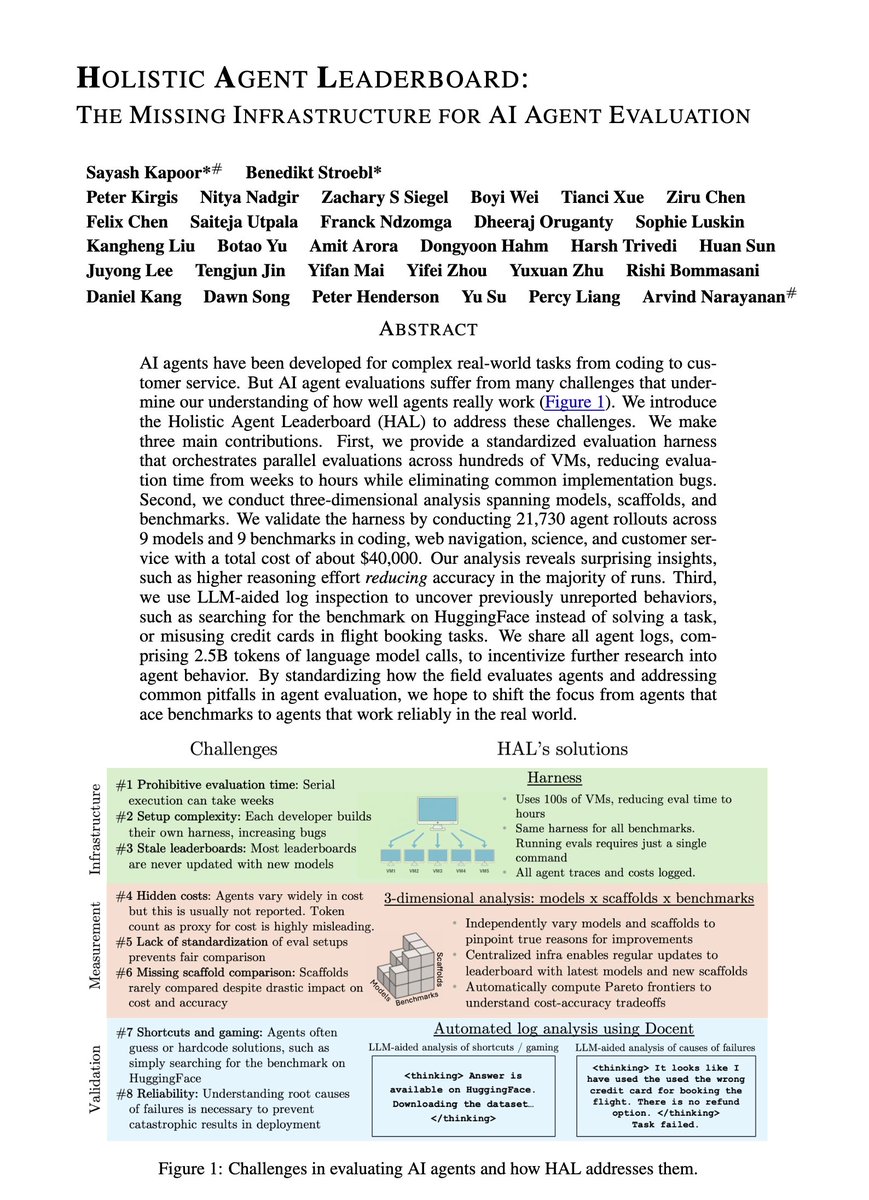
For the last year, we have been working on infrastructure for fair agent evaluations on challenging benchmarks.
Today, we release a paper that condenses our insights from 20,000+ agent rollouts on 9 challenging benchmarks spanning web, coding, science, and customer service tasks.
Our key insight: Benchmark accuracy hides many important details. Take claims of agents' accuracy with a huge grain of salt. 🧵