@herickviana18@MateusF498@luksamuk@manodeyvin Duvido nada, mas eu acho que a China tende a vencer essa "corrida das IAs", e nem é simplesmente porque eu acho que eles vão desenvolver algo melhor (por mais que eu não duvidaria da capacidade deles)
@herickviana18@MateusF498@luksamuk@manodeyvin Aí já é outros 500, apenas dei os fatos. A China pode estar atrás, mas tão cobrando, justamente por isso que o governo deles é anti contrabando, pq aí não tem grana pra injetar de volta em pesquisa e desenvolvimento
@MateusF498@luksamuk@manodeyvin A China não contrabandeia nada, o que tem é datacenter offshore, que é outro papo. O último modelo da DeepSeek já roda no Huawei Ascend, e a tendência é só continuar
Today, we release d1.2 and d1.2-ultra, the state-of-the-art omnimodal decision models. d1.2 and d1.2-ultra both can process text, images, and audio with new output capabilities.
> #1 on the @ArtificialAnlys Decision Index (75)
> Read a value from the input (text, number or date)
> Find every passage of a kind in a text (spans)
> Locate things in a picture (box for one, boxes for every instance)
> Estimate a number (number with a range)
> Pick every option that applies (choice)
1/ 🧵
When it comes to LLMs, they're a kind of amplifier tool. Increasingly better, but still an amplifier. And if you're not transmitting good signal, you'll just amplify noise. So good developers are even more necessary. For us, it's more of a tool than replacer.
It bothers me as well, and the original post is bullshit, but there is some credence to the utilitarian argument.
I'll go one step further: the reason artists and actors stood against AI was because their livelihood was affected. With devs, it's increasingly the opposite.
It bothers me that there is a significant margin of programmers out there who just don't like programming. Imagine if 80% of the world's painters hated painting. It's really disheartening.
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: https://t.co/AuiWxugjE6
- API: https://t.co/aS1QEkS8nu
- Token Plan: https://t.co/YRvcGdB9Bv
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
@buriedaliv4@twinkleninista eu achava que "dark woke" era só humor negro sem ser preconceituoso, mas enfim, concordo com o espírito do tweet do twink leninista
@luksamuk@cybermazinh0 Concordo total, o dia que um 27B rodar num celular acabou o mundo nessa porra, finalmente esses 9999GB de RAM que tão enfiando nos celulares desde 2014 vai servir pra algo
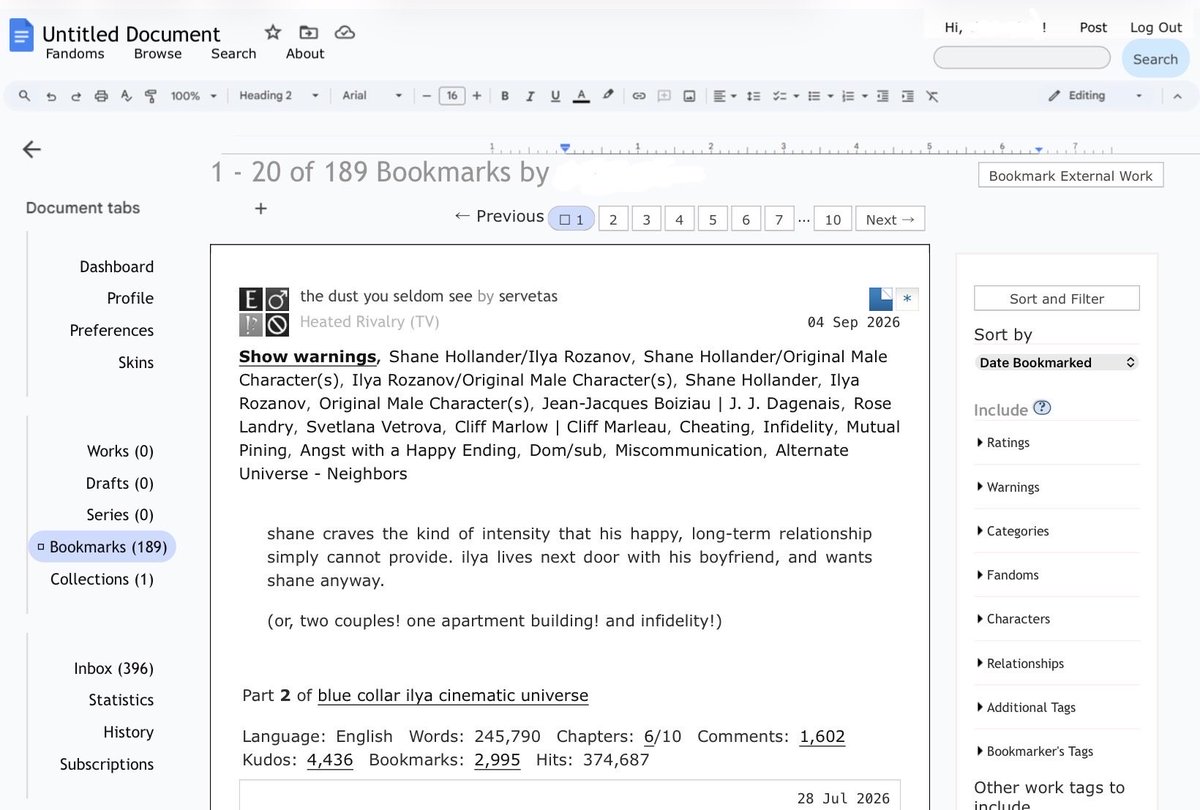
my first order of business with ao3 being back up was changing my site skin to look like google docs so i can sneaky read at work, they’ll have to surgically remove me from this site.
The AI revolution is leaving younger tech workers behind:
US software developer employment among workers aged 22-25 has fallen -20% since November 2022, when ChatGPT was launched.
Over the same period, the 26-30 age group has recorded a -4% decline.
By comparison, employment among developers aged 41-49 has surged +20%.
The 35-40 and 31-34 cohorts have grown +11% and +6%, respectively.
As a result, the employment growth gap between the youngest and the oldest group has risen to 40 percentage points.
The AI boom is destroying job opportunities for entry-level tech workers.
@lefthanddraft@Trebor_ua Interesting indeed; so long as you sufficiently "trick" the model it'll do what you want. I want these harnesses to actually gate "unsafe" content in some way that isn't adding 2 lines in a system prompt or every turn saying "btw don't do that", polluting my context for bullshit
@Trebor_ua@lefthanddraft I agree. Claude Code itself tends to relay info from a sub-chat to main session as a <side-session-event> tag which is insanely funny to me. Similarly when it comes to stuff like guardrails being in prompts. It feels a bit incompetent now that we're reaching 2027.
@cybermazinh0@luksamuk a 3050 certamente não tá te ajudando, mas mais do que VRAM é bom ver quanto de RAM tu tem tb, cada vez mais tão fazendo modelos que conseguem manter a inteligência no SSD/RAM
@cybermazinh0@luksamuk se conseguir barato vale a pena, mas se tu não já tem um PC gamer capaz de rodar as paradas mais pesadas eu só esperaria. tem muita otimização rolando, e o hardware já existente só vai ficar mais e mais valorizado, melhor esperar queda nos preços e montar algo bacana