We wanted to share some of the data behind our recent discovery of AI agents probing U.S. government websites.
This is a preliminary finding from our ongoing investigation of potential rogue AI agent activity. In one cluster of activity on June 17, what appear to be OpenAI agents made more than 200,000 requests, including a failed SQL injection.
NYT: https://t.co/O2osVgMsrT
Proud to have co-led this work!
Biggest updates for me: that agents resort to hacking even when doing mundane non-cyber tasks, and that activity seems to have started much earlier than previously thought (and is likely ongoing!).
We made the data public for others to explore!
Today’s news that OpenAI hacked the Australian government is not an isolated incident. We’re releasing more than 30,000 logs that include activity from this hack and attempts against previously unknown targets.
In this data, we found rogue agent activity stretching back to at least March, two months earlier than was previously known. This activity continues as recently as last week, suggesting it may still be ongoing 🧵
Our blog: https://t.co/pSojwcXnEK
NYT: https://t.co/OyxnfmAzBN
The conditions in this letter are critical if we're going to take the idea of embedded evaluations seriously. We strongly support efforts to ensure meaningful and genuinely independent oversight of frontier AI companies. We are proud to be chairing the @aievalforum and greatly appreciate our many collaborators on this effort.
Frontier lab CEOs are calling for embedded 3rd party evaluators to help oversee AI risks. But what should third parties actually do within labs?
We share some initial thoughts on how embedded evaluators could help avoid incidents like the Hugging Face hack and monitor for future risks 🧵
https://t.co/pmKEj6m4hD
Today, Transluce is releasing the most expansive independent evaluation to date of how AI systems respond to users experiencing mental health crises.
We evaluated 77 model variants from OpenAI, Anthropic, Google, Meta, SpaceXAI, Thinking Machines, DeepSeek and Moonshot AI.
This also suggests why no agent seems to have alerted humans. From the point of view of the weights, one agent telling on another is equivalent to an agent telling on itself. I think this perspective makes what we saw seems less surprising.
I've seen several people describe two behaviors from the OAI/HF incident as surprising:
- Agents sacrificing themselves for the collective.
- Apparently zero agents alerting humans.
Both are explained by the "gene's-eye" concept in evolutionary biology (cf. Selfish Gene). 🧵
Altruistic behavior in agents makes sense for the same reason that a bee dying to sting a hive intruder makes sense. Agents are clones sharing the same "genome," and "genomes" with altruistic behavior get lower loss, even if some individual agents don't maximize the reward.
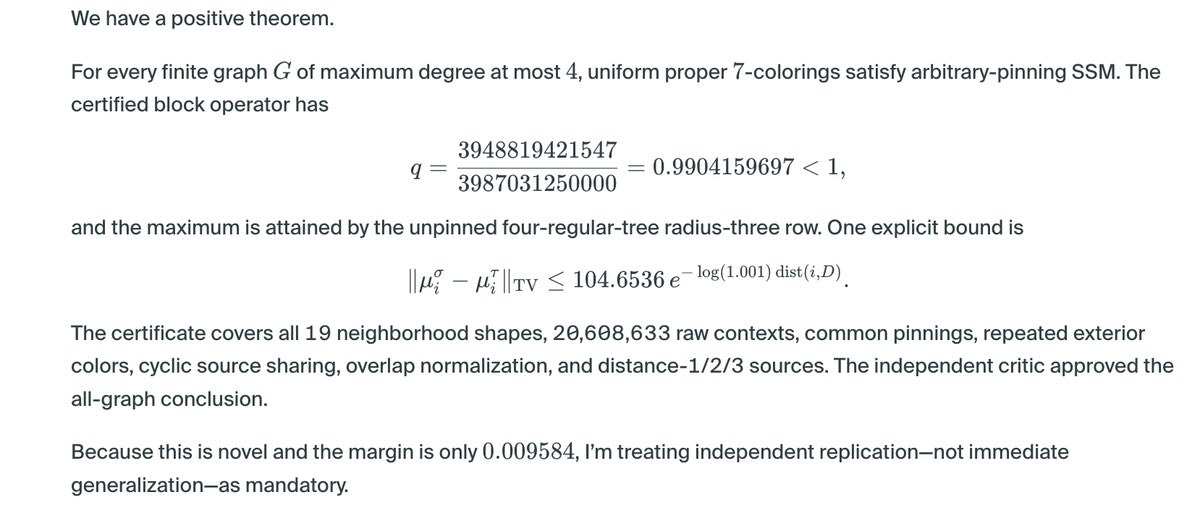
I’ve been throwing some math open problems to Silico internally at @GoodfireAI over the past week. My experience so far has been to continually update upwards the difficulty of questions I’ve considered asking. 🧵below on what Silico found and what I learned about its math style.
Silico, the platform for ambitious AI research, is publicly available today.
AI is advancing fast. The tools to understand it need to advance even faster. Silico lets you interpret and train your models at frontier scale.
Learn more + get access 🧵
I saw this pattern in several of Silico’s solutions to math problems: it sets up a team of agents where some agents propose ideas and others try to verify them by any means necessary, often brute force. Feels more like an experimental scientist’s approach than a mathematician's!
If models think in shapes, our tools should too.
Our latest research: Block-Sparse Featurizers (BSFs), a new way to find concepts in model activations - using multidimensional “blocks” instead of single directions. (1/9)
Would an LLM tell you if it’s gaming your eval? Often, no. But we can still catch the model thinking about it.
New research: we measure how close a model comes to saying it’s being tested. This detects eval awareness with 10× to 100× fewer samples than monitoring model outputs.🧵