ODS
I'm very happy to be part of this, thank you to everyone who helped contribute and reach 4k stars in such a short time. We’re pressing ahead to ensure everyone has access to high-quality local AI.
Just a reminder that I said this almost a year ago, and now we have something amazing, free, and made by the people for the people at @OsmanticAI
If I say it’ll be done, you can mark me on it
Opensource AI will win and Local AI will be the default.
There’s a difference between having a Kofi link to support your Opensource contributions and begging btw
We even have an Opensource Contributors program at @OsmanticAI where we spend thousands of dollars a month to support our Opensource Contributors ❤️
If your grandma cannot run Local AI on her laptop from 2013 we'll have failed our mission
That's the bar we're setting for ODS
We're gonna make Local AI the default, and while doing that the word "local" will stop being necessary to begin with (because it's already the default)
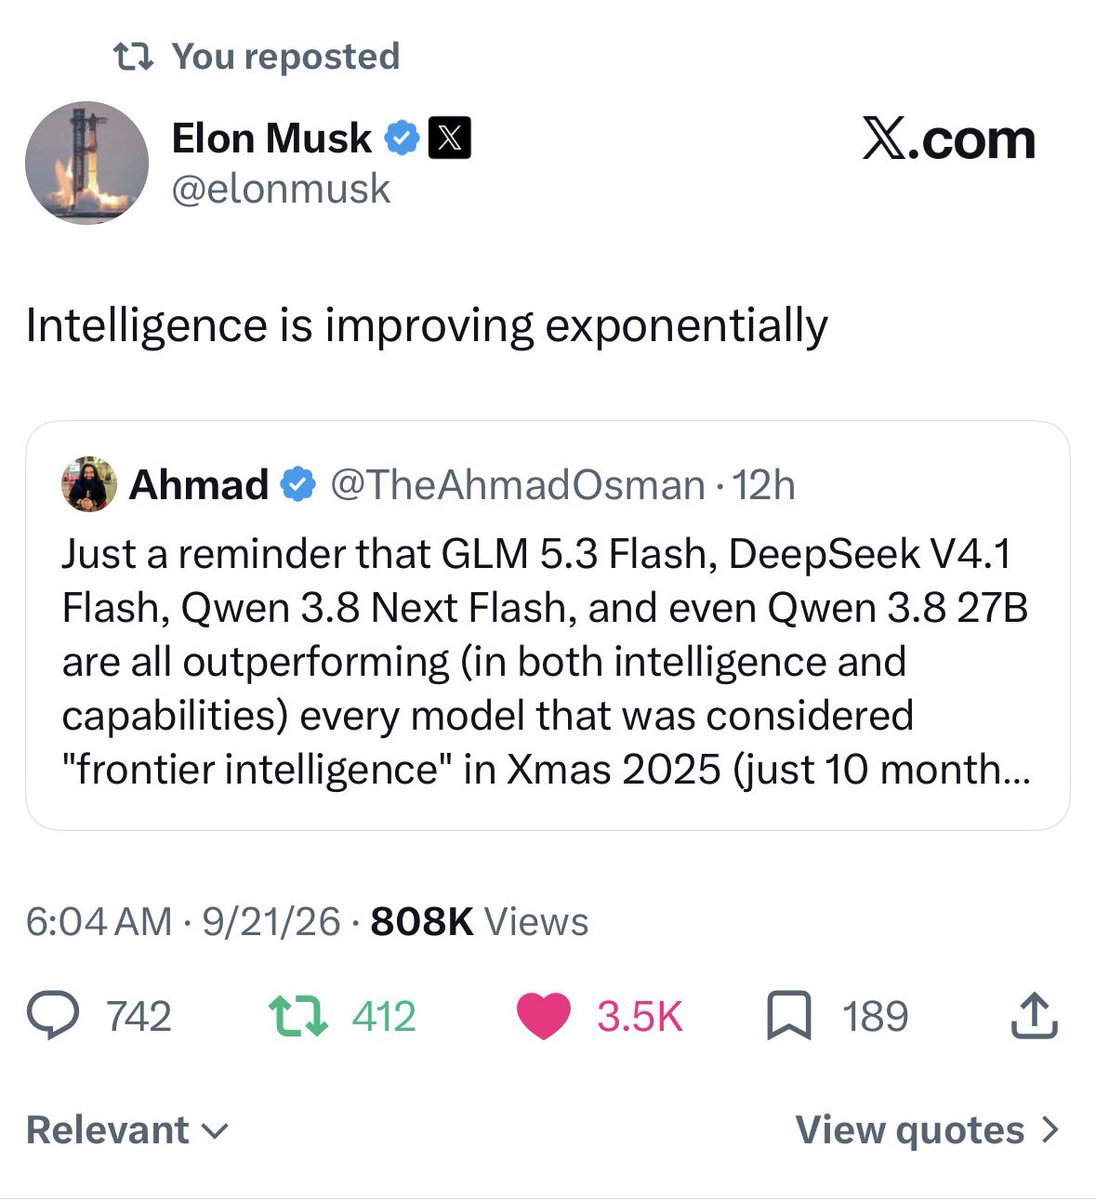
Just a reminder that GLM 5.3 Flash, DeepSeek V4.1 Flash, Qwen 3.8 Next Flash, and even Qwen 3.8 27B are all outperforming (in both intelligence and capabilities) every model that was considered "frontier intelligence" in Xmas 2025 (just 10 months ago)
Opensource AI is on fire
Fun video talking about local AI motherboards, what to think about when selecting them for local AI server builds, PCIe lanes, and why all of this stuff matters when you are doing multi GPU work without NVLink. Featuring the ASUS WRX90E-SAGE SE motherboard.
Based on my experience with DeepSeek V4.1 Flash, GLM 5.3, and Kimi K3
- DeepSeek is excellency itself when it comes to pre-training
- Zhipu and Moonshot are better at post-training though
We're so lucky to have such amazing opensource players btw
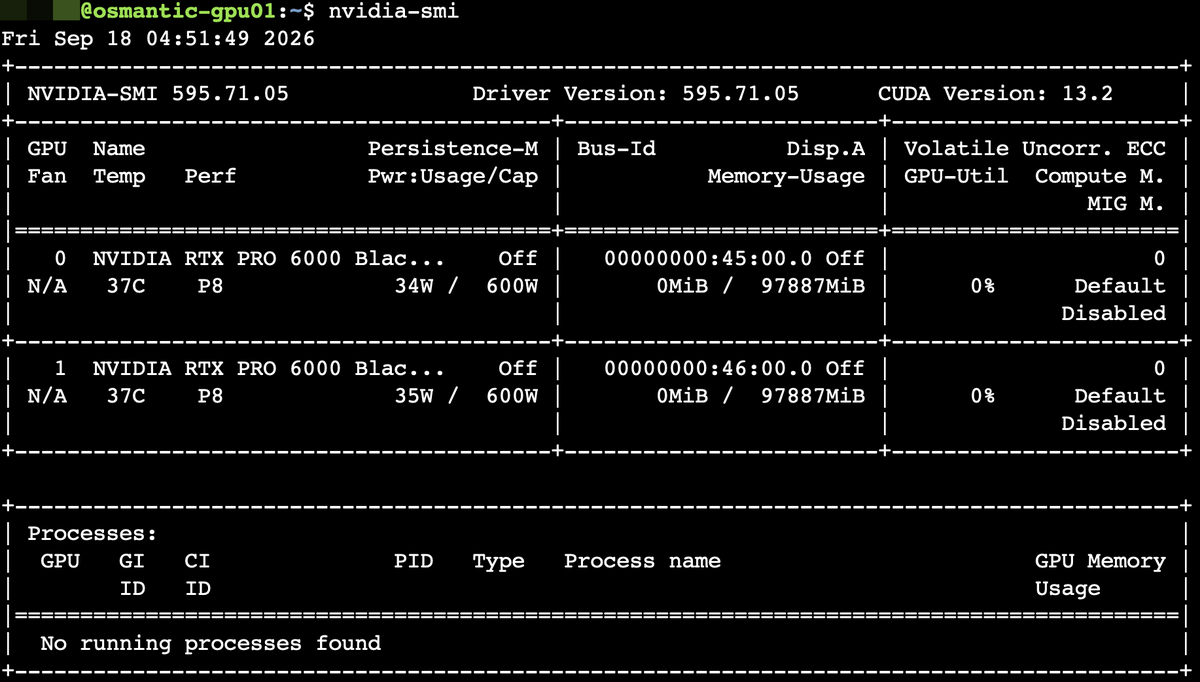
Playing with a few RTX PRO 6000s and a DGX Station tonight
I feel privileged and that is actually a problem
In a few years, I genuinely believe we won't need such massive amounts of compute to run quality models --- this is the problem we are building @OsmanticAI to fix
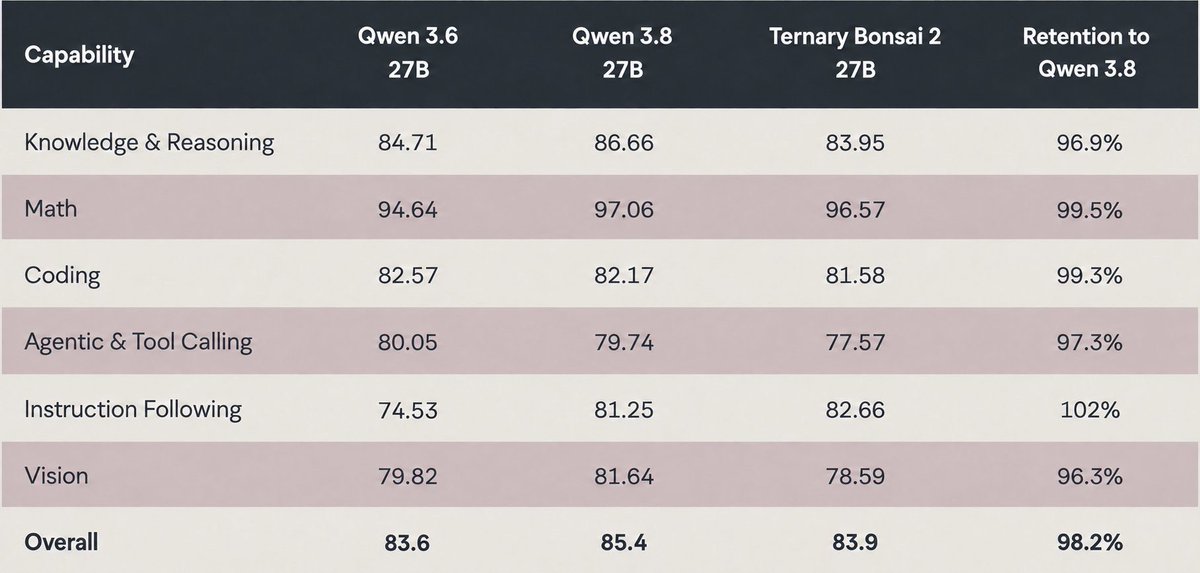
Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.