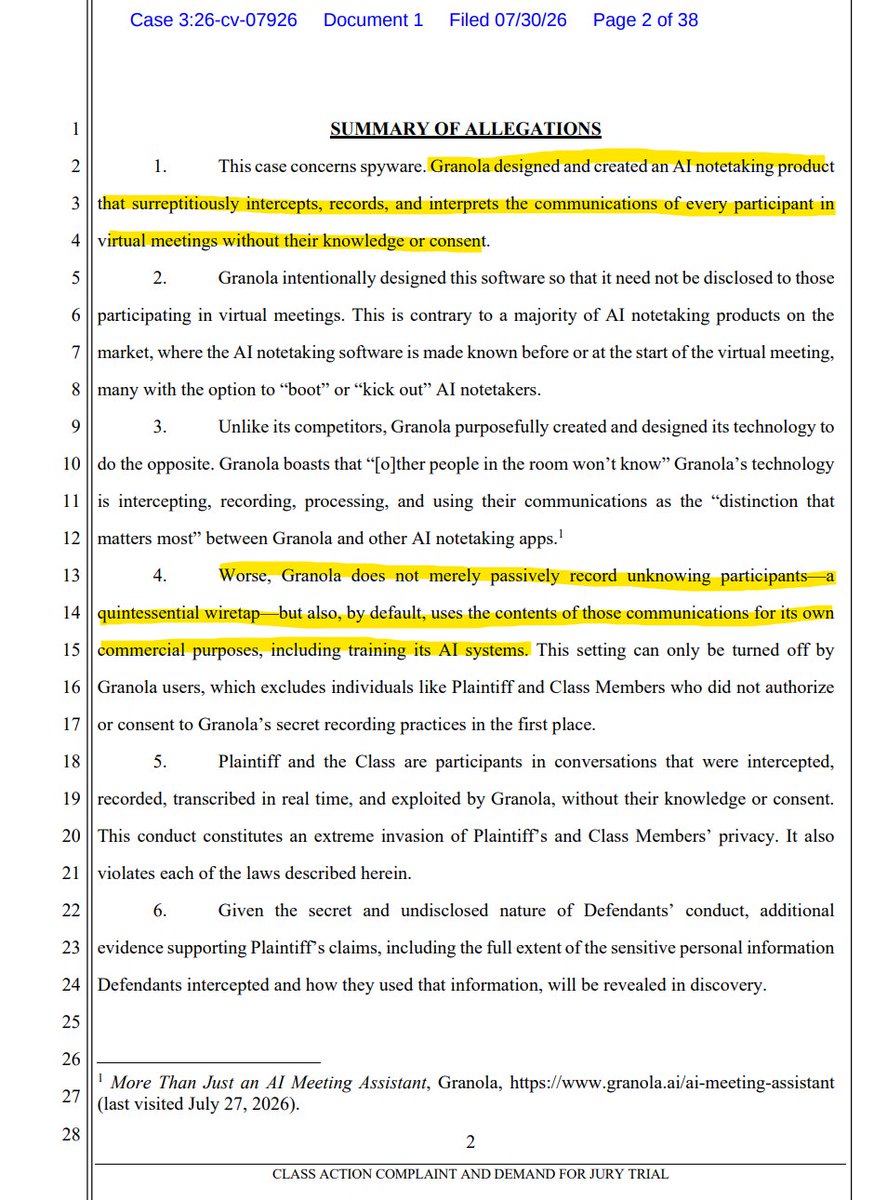
Granola secretly records meeting conversations without consent of participants and uses the recordings to train its AI models, according to a new class action filed yesterday.
Plaintiff says Granola recorded her meeting but was never notified of Granola's presence.
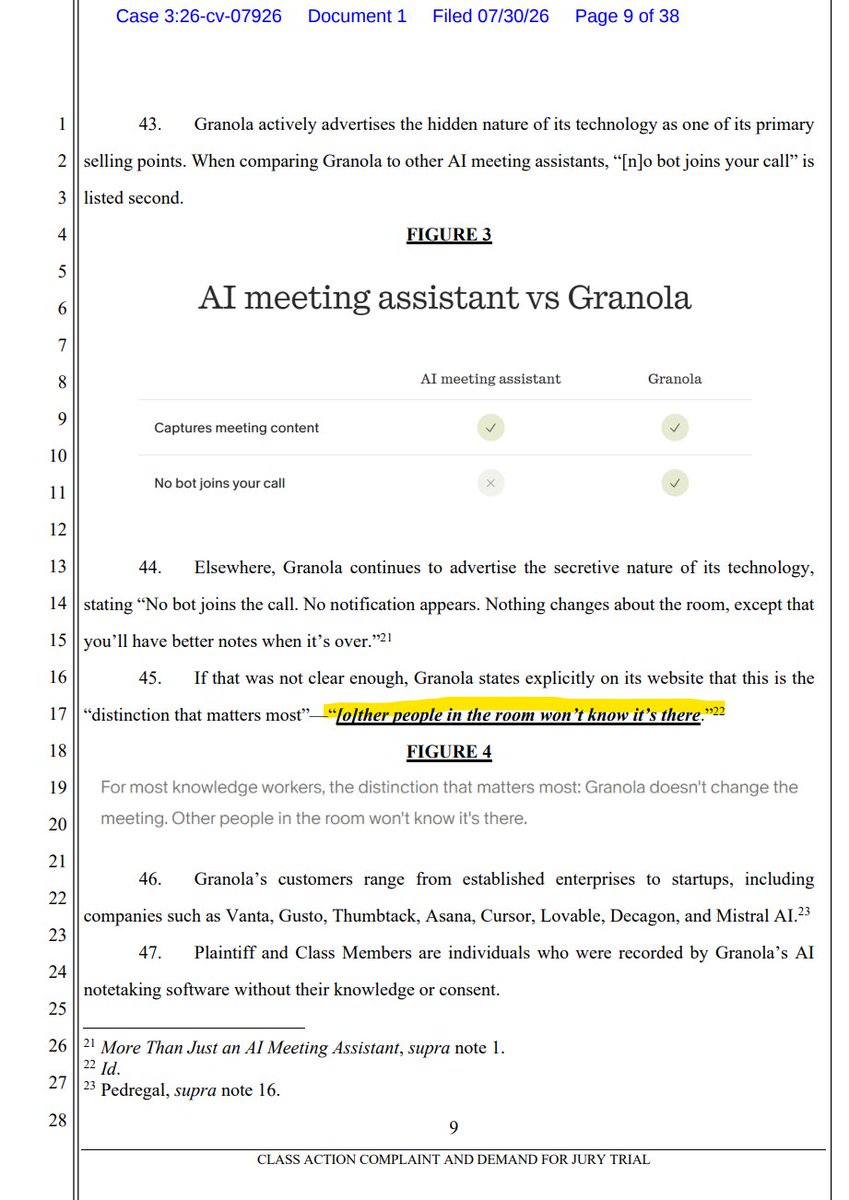
Granola's allegedly said on its website that "other people in the room won't know it's there."
Exhibit B: Strava, the wildly popular social network fitness app, introduced AI intelligence over a year ago. I know loads of endurance athletes that are habitual Strava users.
Not once have a heard any of them say anything nice or supportive of the AI features in Strava. The most common response is complete disinterest.
These features might as well not exist.
btw anthropic's internal document on this literally said "we don't want it to be known that we are working on this.”
it was called project panama.
here's exactly what happened:
1: anthropic concluded that books were the cheapest way to build a world-class model because they gave claude curated facts, structured arguments, compelling stories, and writing “an editor would approve of.”
2: once anthropic decided it needed books at enormous scale, its first solution was piracy.
it downloaded 7m+ books from online libraries including libgen. the judge later wrote that although anthropic had legal ways to buy them, it chose piracy to avoid what dario amodei called the “legal/practice/business slog.”
3: that piracy created a massive legal risk.
so in february 2024, anthropic hired tom turvey, the former head of partnerships for google books, to find a legally safer way of obtaining “all the books in the world.”
4: turvey first contacted major publishers about licensing their catalogs.
those attempts didn’t produce agreements, so anthropic chose a route that required no publisher permission: buying millions of physical books through distributors and used-book retailers.
5: within about a year, anthropic spent tens of millions acquiring and scanning millions of books, including many rare and 1/1 titles. one vendor proposal targeted 500,000 to 2 million books in six months.
6: to scan that many books within months, the vendors physically dismantled them.
a hydraulic cutter removed each spine. the pages were trimmed to size, fed as loose sheets through high-speed industrial scanners, and converted into searchable PDFs. the paper remains were then sent for recycling.
7: these PDFs were fed into claude as training data.
the complete collection became a private, searchable anthropic library that the company planned to “store forever.” the scans aren’t available to the public and were never open-sourced.
It's not just CTO / Head of Eng types. It's the majority of people. Most just don't have the option to bounce without facing severe financial hardship.
So they suffer, quietly.
Interesting trend:
CTO/ Head of Eng / VPE folks at startups and mid-sized companies are... leaving / burning out. Hiring for these roles is HARD, but even after filling the role, they will often leave a few months later and take a career break
And they have v good reasons
@ItsDeanBlundell Every time I come across your posts—not often, thankfully—you’re always posting the most idiotic takes.
Your consistency is commendable, Dean.
The volume of AI bot replies on Reddit appears to be growing by the week.
Soon, if not already, we’ll have a beautiful, self-referential slop loop with AI citing itself when composing answers.