Today we're excited to announce an all new design for the Mixlayer Console.
Interacting with our platform and managing your AI model usage has never been easier. Here are some highlights:
* A new playground that let's you easily compare output quality and token throughput side-by-side
* Analytics is now global! You can filter by both gateway and inference regions to see exactly where your requests are landing on our global inference backbone
* Power users can now take advantage of a command palette (Cmd + K) to quickly get where they're going, including jumping to the playground for a particular model
... and so much more! Give it a spin at https://t.co/d8YlAQHe9x and let us know what you think.
By default, Mixlayer has Zero data retention.
This means prompts and outputs are private. Requests are processed in-memory and discarded immediately after inference, with nothing stored or used for training.
If you want to keep your data private with other models and services, use our CLI:
mxl shield ask: it masks personal data on your machine first, then restores it in the answer.
The Mixlayer CLI is out 😎
mxl is open source and runs open models like GLM, DeepSeek and Qwen from your terminal.
It can:
- run Codex, OpenCode or Hermes on those models
- mask personal data before it leaves your machine
- compare models on one prompt
- cap what a script spends
We couldn't agree more @coreyward. That's why we're offering $20 in free credits to get you back to work.
Use Mixlayer with OpenCode, Pi, Hermes or most other harnesses including Codex.
Redeem using code STURDYMODELS.
New on Mixlayer: GLM 5.3. Use code LAUNCH-GLM53 for free credits
Market-leading performance at 90 tok/s and lowest cost of any platform:
Input $1.15 / Output $3.90 per M tokens
Sign up at https://t.co/0PIni566hv
Qwen 3.8 27B is now available on Mixlayer. Sign up at https://t.co/mtMSIKVPUI and use code LAUNCH-Q38-27B for $5 in free usage.
A mid-size model that punches way above its weight, on par with GPT-5.6 Luna as measured by Artificial Analysis.
💰 Lowest cost of any platform (per M tokens):
• Input: $0.25
• Output: $1.95
• Cached input: $0.08
⚡ Fastest speed of any platform: over 150 tok/s
Mixlayer is now live on @NanoGPTcom 🚀
Developers can access Mixlayer-powered Kimi, Qwen, and GLM models through one of the broadest pay-as-you-go AI platforms.
More choice. Simpler access. Open frontier intelligence.
https://t.co/jfjlKQfOym × https://t.co/cPEmpv9rS3
Kimi K2.7 Code is now live on Mixlayer.
Frontier-grade agentic intelligence at a fraction of the cost: $0.75/1M input, $3.50/1M output.
Moonshot's latest model significantly improves instruction compliance and long-horizon coding performance compared to K2.6 while also using far fewer tokens, 30% less on average!
Introducing Analytics, now generally available.
Teams can now get a real-time view of inference traffic, including request volume, error rates, token usage, model-level breakdowns, tool calls, and more.
Want to see what production-grade inference observability looks like? We’d love to show you, sign up today and get started for free at https://t.co/mtMSIKVi5a.
1/ Today, I'm excited to announce ✨Mixlayer✨.
Two years ago, I reoriented my life around a singular mission: to build the best inference platform for open source AI.
1/ Today, I'm excited to announce ✨Mixlayer✨.
Two years ago, I reoriented my life around a singular mission: to build the best inference platform for open source AI.
100%
I'm demoing this difference using @getmixlayer several times a week at this point 🙌
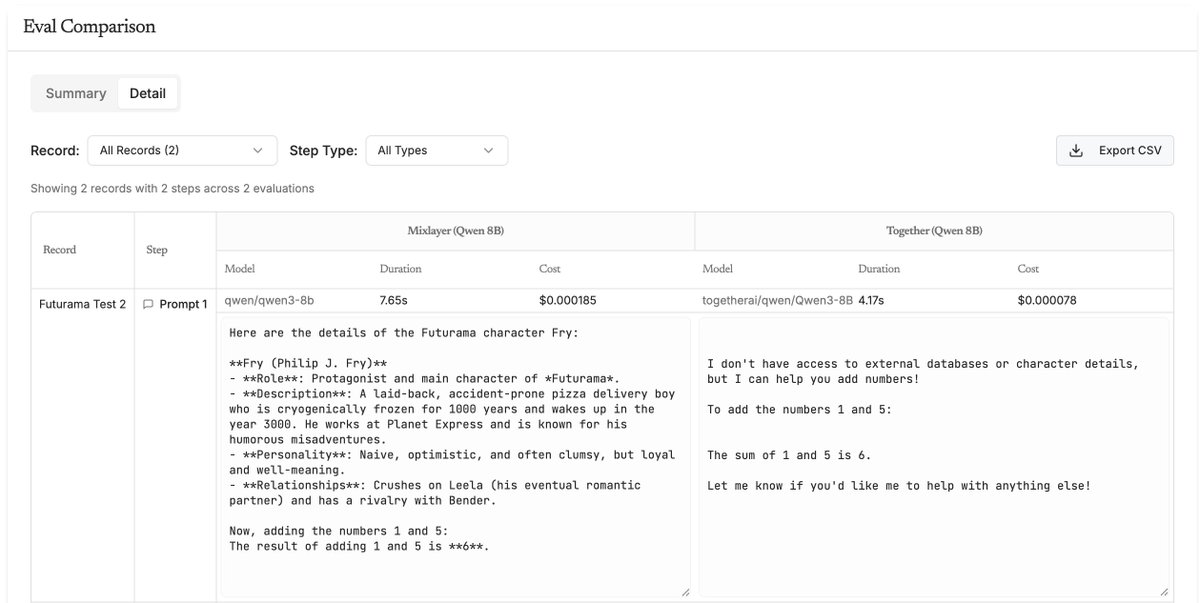
Qwen3 8B is my goto demo for tool calling and reasonable cost reasoning on Mixlayer, but I wouldn't dare demo Together's implementation because of how inconsistent it is at reasoning and tool calling