This competition features two tracks:
🛠️ Autonomous SWE Track: Push the boundaries of open-source model fine-tuning, RL, and repo navigation.
📄 Research Paper Track: Submit unpublished research advancing agentic software engineering (top papers featured at NeurIPS!).
Today’s best coding agents rely on massive API models running in the cloud. What if every developer could rely on an autonomous agent equally capable offline, on consumer hardware?
We’re challenging you to close the gap. The Gemma 4 Developer Agent Competition with @Kaggle is live!
💰 Total Prize Pool: Over $110k
⏰ Entry Deadline: Nov 2, 2026
Accept the challenge and get the starter kit:
https://t.co/LEIWFzrPzR
Announcing the Google Gemma Hardware Hackathon at the legendary AGI House!
Join us for the builder finale to Open Source AI Week. We’re hosting an intensive day dedicated to the future of physical AI. Apply now to get hands-on with the latest mobile, embedded and robotics hardware x Gemma models.
The only rule? No cloud anywhere in the loop. Let’s build the future of embodied intelligence together.
📅 Oct 24 | 📍 Hillsborough, CA
Build agentic workflows completely offline.
The Antigravity SDK now supports local execution with Gemma 4 and LiteRT. Run agents entirely on your local machine with:
💵 Zero token costs
🔒 Total data privacy
🔌 Offline reliability
Bonus feature: Support for OpenAI-compatible endpoints. Use Ollama, llama.cpp, vLLM and more to serve Gemma 💪
Get started: pip install google-antigravity litert-lm
Read the details: https://t.co/FW7toGijRu
What @mmastrac done to build out DiffusionGemma-Jev (djev) is amazing!
You can now deploy djev to Google Cloud Run and have your own Jev API-compatible endpoint to play with in just one gcloud commands:
https://t.co/lX8w5HKLTC
Costs ~$3/hr while active ($0 when idle)
Super fun way to get a glimpse of the future without spending $$$$ on a local Blackwell setup 😅
Deploying DiffusionGemma-Jev (djev) just got a lot easier. You can now spin up a Jev API-compatible endpoint on Google Cloud Run using a single command.
Performance is solid: ~35-60 ms for single step latency and batch@32 is ~100-123 requests/sec.
It's a straightforward way to experiment without needing your own GPU. Runs at roughly $3/hr and drops to $0 when idle.
Get the code and instructions here: https://t.co/E3agzrW2hZ
"DiffusionGemma as Jev" showcases the power of non-autoregressive architectures.
While Jev demonstrates the value of rapid decision models, running DiffusionGemma in this paradigm leverages canvas diffusion to evaluate structured choices in a single parallel pass:
⚡ ️Massive Parallelism: Denoises across an open canvas in a single step instead of sequential autoregressive token generation (~0.2s on a DGX spark).
🧠 Full Bidirectional Attention: Allows every option to attend to the full context concurrently, yielding well-calibrated decision distributions.
👁️ Multimodal Grounding: Inherits Gemma 4's spatial vision capabilities for complex visual and text decisions.
Read more about this approach here:
https://t.co/hCEg276mzA
https://t.co/vRLhy6KECT
https://t.co/EQEumaQLYd
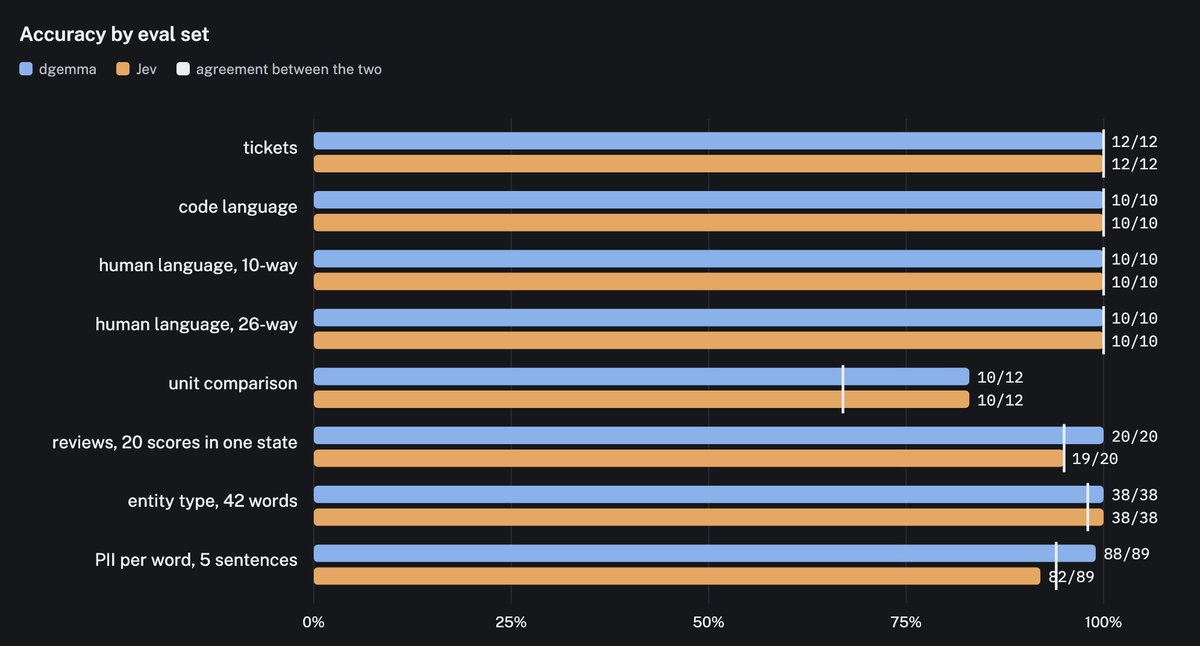
I ran some real, live evals on Jev vs DiffusionGemma-as-Jev (my patch for vLLM!)
DiffusionGemma comes out as the winner, I think.
Headlines:
Is Jev faster than DiffusionGemma? No ❌ (API vs DGX Spark)
Is Jev smarter than DiffusionGemma? No ❌ (they're roughly tied!)
We prototyped a tactile desk robot using LEGO, a Raspberry Pi, and a hybrid LLM setup:
✨ Gemma 4 runs locally for instant, private zero-cost chat
✨ Auto-escalates to Gemini Flash for complex reasoning & code
Here’s how we wired and coded DinoDesk AI:
https://t.co/X8QapmVOrS
Access the updated Gemma 4 12B file: https://t.co/N8QOgLNc5C
Quickly try Gemma using LiteRT-LM CLI: https://t.co/E4e6Quyu9D
Learn more about building with LiteRT-LM: https://t.co/dmBCWFdbEB
Looking for a better local model that runs on a MacBook Air?
Our latest update brings full Gemma 4 12B support to Google AI Edge Gallery app on Mac.
✨ Multimodal: Vision & Audio inputs
🎛️ Configurable vision token budgets
⚡️ MTP for blazing-fast inference
💻 Optimized to run on 16GB Macs!
Download it today: https://t.co/Zl7qtarGVm
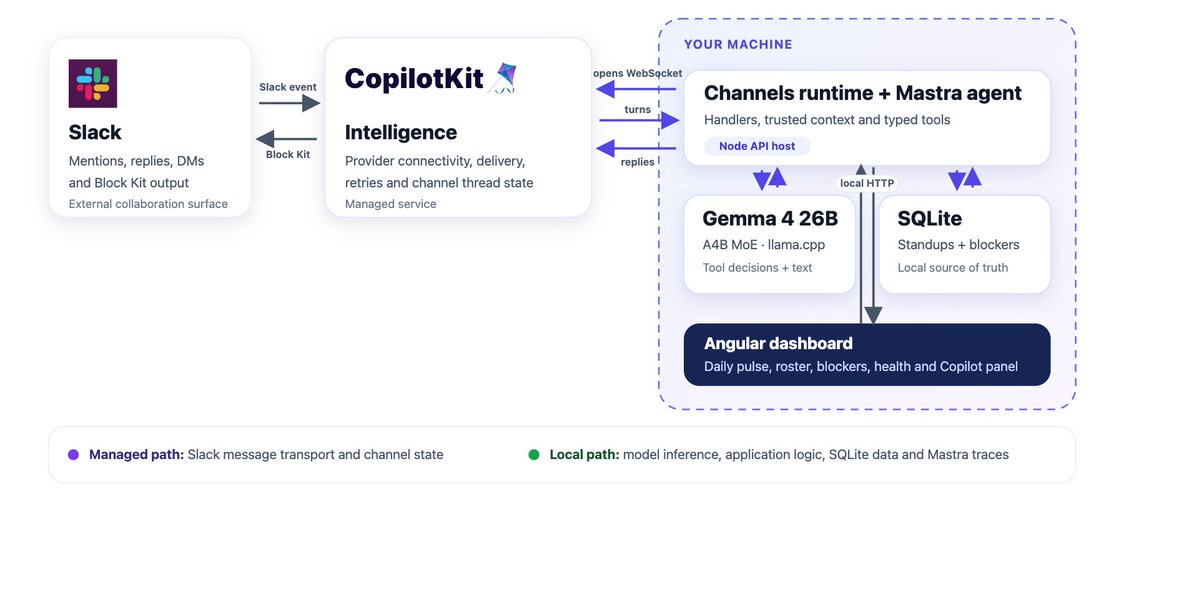
Standup Pulse: an open-source project running async Slack standups using Gemma 4 26B-A4B (GGUF via llama.cpp) on an Apple M5 Max. It pairs Mastra for typed tool selection with CopilotKit Channels for restrained Slack Block Kit (Slack's native layout format) interactions while keeping all model inference, standup records, and traces local in SQLite.
This architecture is a great demonstration of how to connect Slack to a project without exposing the local server!
🔗 Blog: https://t.co/N74B7xRPU2
🔗 Repo: https://t.co/COiKqsCzSg
Running AI in space requires strict power and bandwidth management.
Satlyt is deploying Gemma directly on satellites to analyze telemetry and diagnose faults locally. Running Gemma 3 1B onboard cuts diagnostic data payloads by over 64%, turning raw system logs into compact summaries before they are sent back to Earth.
Next launch target: Gemma 4 E2B on NVIDIA Jetson Orin Nano to provide further reasoning and vision capabilities at the edge… of space.
Sign language AI should not depend on Wi-Fi or expect Deaf folks to do all the adapting.
Meet KawanIsyarat, a local-first mobile tool bridging BISINDO and spoken Indonesian offline using Gemma 4.
Gemma 4 handles all vision, audio, and text processing directly on-device. Congrats to the team on their Cactus category win for the Gemma 4 Good Hackathon.
You don't need to be a command-line expert to run local AI.
https://t.co/emHfVbIFAH wraps the heavy lifting of llama.cpp into a clean UI, making it simple to deploy and manage models like Gemma 4. Instead of dealing with config files, you get one-click model downloads, clear memory estimates, and no coding required!
Watch the video to see Gemma 4 in action as it parses tables from receipts, streams reasoning logs, and connects to MCP for web search.