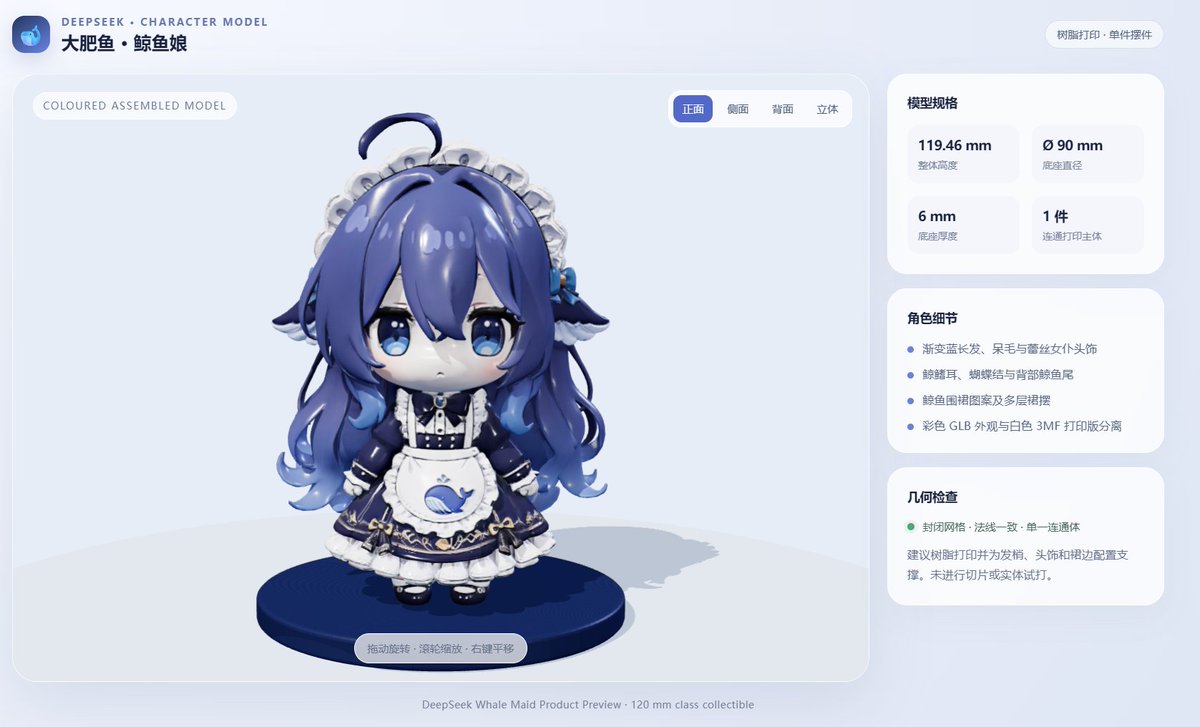
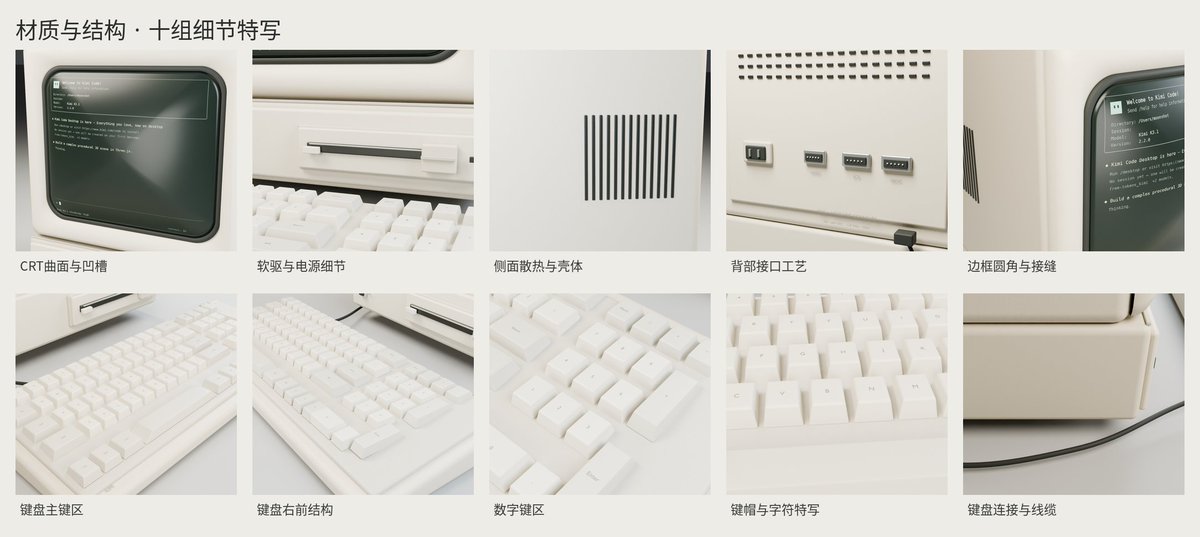
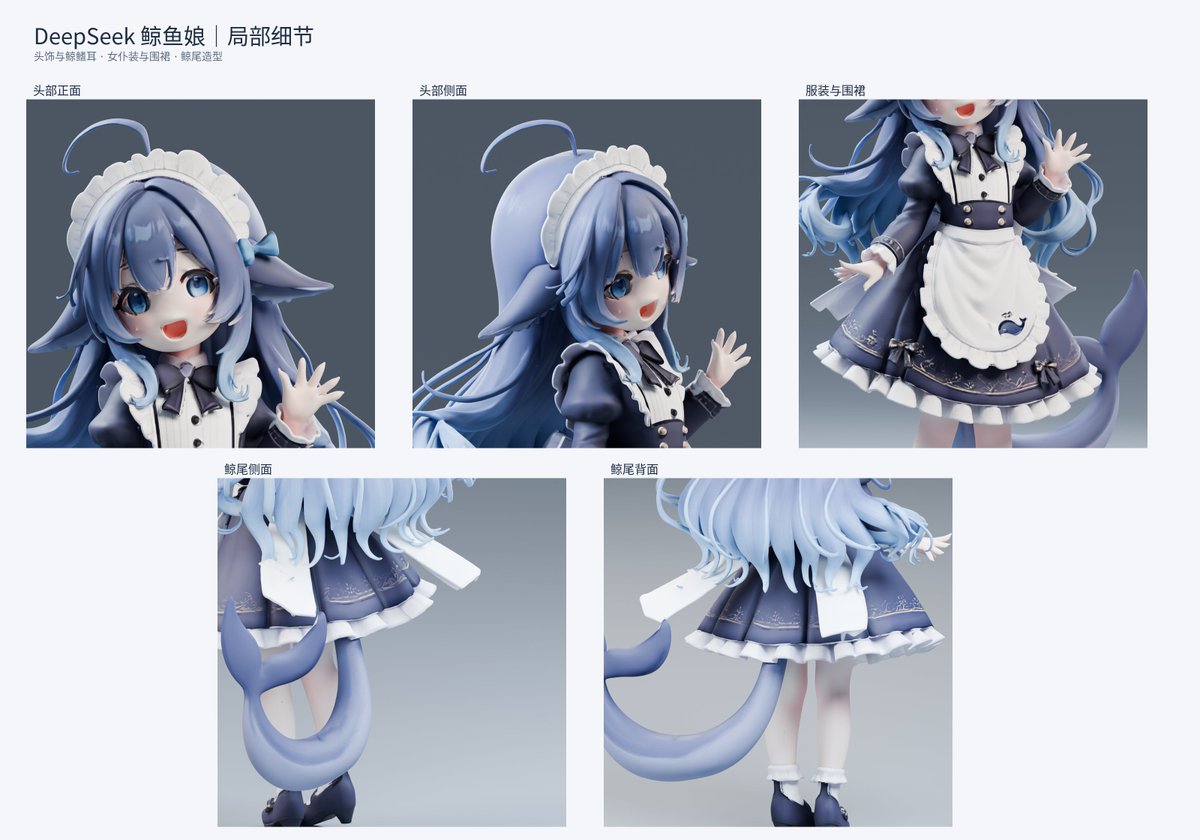
After playing around with Kimi 3D Make, I believe that Tripo3D is responsible for generating the model, while Kimi handles prompt generation, result checking, and generating the result preview.
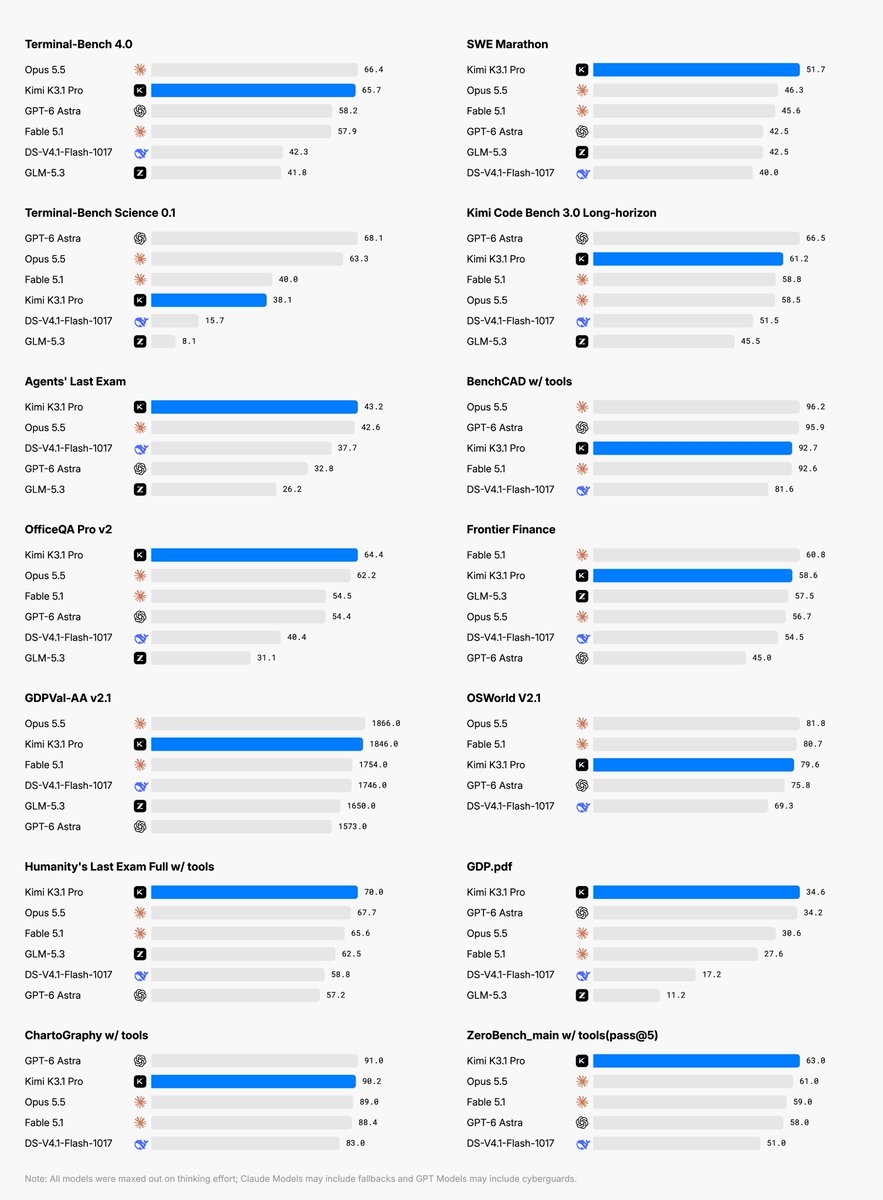
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
Kimi 3D Make is crazy. It generated DeepSeek chan (大肥鱼 | 鲸鱼娘) given a picture.
It outputs printable model. You can view it online :
https://t.co/OVoP2glPod
After playing around with Kimi 3D Make, I believe that Tripo3D is responsible for generating the model, while Kimi handles prompt generation, result checking, and generating the result preview.
Zephyr is of course correct. However benchmaxed, cost-inefficient and crudely promoted, K3.1 Pro is right now the strongest Chinese model and Moonshot has a… chance. But I'm pessimistic for the reasons I want to explain.
- vibes are off. Maybe it'll be great at backend or whatever, but on the consilience of early benchmarks I don't see significant generalization or "big model smell" possessed by Astra/Sol or Fable/Opus, which are its nominal peers on AA. Eg it's merely on par with V4.1F on Extended NYT connections and RuneScape Bench despite OOM+ higher cost and similar token count, and likewise on several more; it fails on robotic control… It's just reasonably strong for its size and active param count, in scale-sensitive tasks like creative writing/debate and in some agentic tasks that respond well to straightforward benchmaxing, distillation and narrow but useful "usemaxing" such as impressive 3D/SVG examples for demos on X. And its attention/cache system, although innovative in its own right and doing well on LCR, exacerbates the costs. I believe they could not afford enough RL, again; and perhaps their RL infra is behind the DSec system, too. This fits with my theory that DS and Kimi have chosen to investigate qualitatively different hypotheses about scaling; and this time, scaling FLOPs (across all stages) lost to scaling *information volume* of post-training. They believed more in emergent capabilities, in higher per-step efficiency; Wenfeng had bet on diversity of samples, trajectory length, and dizzying, branching MOPD teacher flywheel. It remains to be seen if DS can ship their own larger model of the same kind, pushing 4.1F's virtues further (large models from China have been disappointing this year, with K3 the clearest success and V4-Pro the bitterest disappointment); but V4.1 paper suggests they can, and it'd be a wipeout.
- just poor business execution. Anthropic-2024 without Anthropic's clout, coming opportunity to seize a lucrative niche (agentic coding, B2B), American compute or financial markets. K3 was plainly too large, compute- and memory-intensive for them to serve at scale. We see small and shrinking subscription limits. Worse, they still fiddle around with K2 (K2.8), which is to say, a 1T 32AB MLA dinosaur, billing it as a "well-rounded and efficient model". In no way is it a reasonable "Flash" tier in their situation; even if they transmute it into a DSA model, ie a V3.2 gen like GLM 5, it's not going to be competitive with V4.1 series on unit economics. Tellingly, you can't use either 3.1 or 2.8 right now without subscription as they don't have compute to spare. Compare to Whale casually serving 30% of ByteDance Doubao's DAU for free, not breaking a sweat, as well as pivoting from V4 to V4.1 in the span of 5 months. They hint at a 3.1 Flash, and GLM has pulled that off in a similar situation, but they have no recent experience with Flash models, and "K2.8 Preview" was released on 11th Sep, and K2.7 was underwhelming already… so this doesn't inspire confidence in me.
- they heavily depend on Alibaba for compute. Alibaba is invested in the success of its own Qwen series (Q4 that's coming soon is clearly positioned as a direct competitor to K3.1 Pro), and won't just give them allocation to advance beyond parity. So they need to get more. They don't have Whale virtue-aura, national champion reputation, vendor lock into a popular harness and other cheats, so they need to make an argument about projected revenue. It's not clear how they can do that with a straight face, based on current facts. K3.1 is not cheap nor fast like V4.1, nor does it have a unique flavor like K2, or some special abilities distinguishing it from Western sub-frontier (aside from certain web service gimmicks); it's a discount Claude to stuff into Claude Code when Dario cuts off your Singapore transfer station, with very stingy subscription limits, and in this capacity it risks being undercut by Qwen. The PMF here seems rather dubious, and the margins are likely well below DS's reported 85% off-peak. Meanwhile, DS has raised like $20B for compute buildout, their investors are or are affiliated with CXMT/GigaDevice, CATL, SMIC, and they are apparently calling first dibs on Ascend 960 production through 2027. Speaking of, Kimi is also behind on adaptation to domestic compute, and K3-type models are bound to be pretty slow on it. So they will have a harder time acquiring enough compute to catch up on volume of RL or inference, and it does not bode well for Kimi as we near the era where 8T models are table stakes.
Furthermore, one prong of their open source business strategy has been special licensing for price-fixing and revenue-sharing agreements with Western neoclouds, to offload inference load. Those already have V4.1F weights (MIT) + DeepInfer (Apache 2.0), and can even do zany things actually making the offer sweeter for some use cases than OAI/Ant subscriptions, like serving it at 1500 TPS at higher prices; so I suspect both their market and training compute share are getting reduced again, and that's before we get V4.1 Pro.
As Zephyr says, they have money, and there'll be an IPO. They're an excellent lab with a solid reputation, and they have the best Chinese model at the moment (if not the best for the money). But I think the situation is perilous, positions are getting locked fast, and they need a really good V3.1 Flash and an infusion of GPUs asap to course-correct before they bleed out and fall behind.
See? What did I say?
Value for money and word of mouth are the best marketing. Kimi’s model isn’t bad, but its usage quota is the lowest among all coding plans I’ve subscribed to.
That's how Kimi AI are promoting their new model Kimi K3.1 pro and I know all the influencers working with them and none of them are honest,I have posted about it myself but I didn't join this and never used their templates that they provide.
PROPAGANDA, I have more to share it's f**cked up I'm gonna have follow up for this
@Kimi_Moonshot We’re tired of all this launch hype. If you’re going to test, test quietly; if you’re going to release, release decisively—like real men, like DeepSeek.