GPU RWA Batch 02 is now live.
Target: $250,000
🔸$1,000 minimum
🔸20% APR
🔸Paid in USDC at the end of term
🔸Target term under 12 months
Link: https://t.co/hV2V9q52mQ
**1/7**
Most AI teams pick compute providers with a broken framework.
They scan top-10 listicles, compare raw H100 hourly rates, and choose the cheapest option.
Six months later, they’re locked in. Here’s the framework that actually works for where to run your AI workloads.
**2/7**
Stop asking “Which provider is best?”
Ask these five questions first:
• Workload shape: Heavy batch training or 24/7 low-latency inference?
• Budget stage: Bursty pre-seed testing or steady-state Series A scaling?
• DevOps bandwidth: Can your team orchestrate multi-provider infrastructure?
• Compliance: Do you need strict HIPAA/SOC 2 regional boundaries?
• Growth spikes: Can your infrastructure scale 10× instantly without quota delays?
**3/7**
Understand the market split:
• Hyperscalers (AWS/GCP): Strong IAM/MLOps ecosystems and compliance, but premium pricing, high egress fees, and slow quota approvals.
• Neoclouds: Fast raw compute, yet you bet uptime on a single vendor’s physical limits.
• Aggregated fabrics (@gpunet): Global supply, lowest market-clearing rates, and dynamic scaling across distributed nodes.
**4/7**
The biggest rookie mistake is treating training and inference as the same workload.
• Training: Needs massive centralized clusters, high inter-node bandwidth (NVLink), and “train once” batch economics.
• Inference: Needs low latency, regional distribution, fast cold starts, and ruthless cost-per-token optimization.
You serve forever. Build the stack accordingly.
**5/7**
The staged roadmap for AI infrastructure:
• Stage 1 (Pre-PMF): Stay 100% on-demand. Never lock into reserved contracts. Prioritize checkpointing discipline and flexible pay-per-hour compute.
• Stage 2 (Early scale): Separate training and inference clusters. Run 60-day spend models to test if reserved silicon pays off.
• Stage 3 (Scale): Abstract away single-vendor lock-in with open container standards and decentralized compute fabrics.
**6/7**
This is where @gpunet fits the modern AI stack.
Instead of rigid cloud contracts or manual vendor negotiation, it unifies global compute supply into a single fabric:
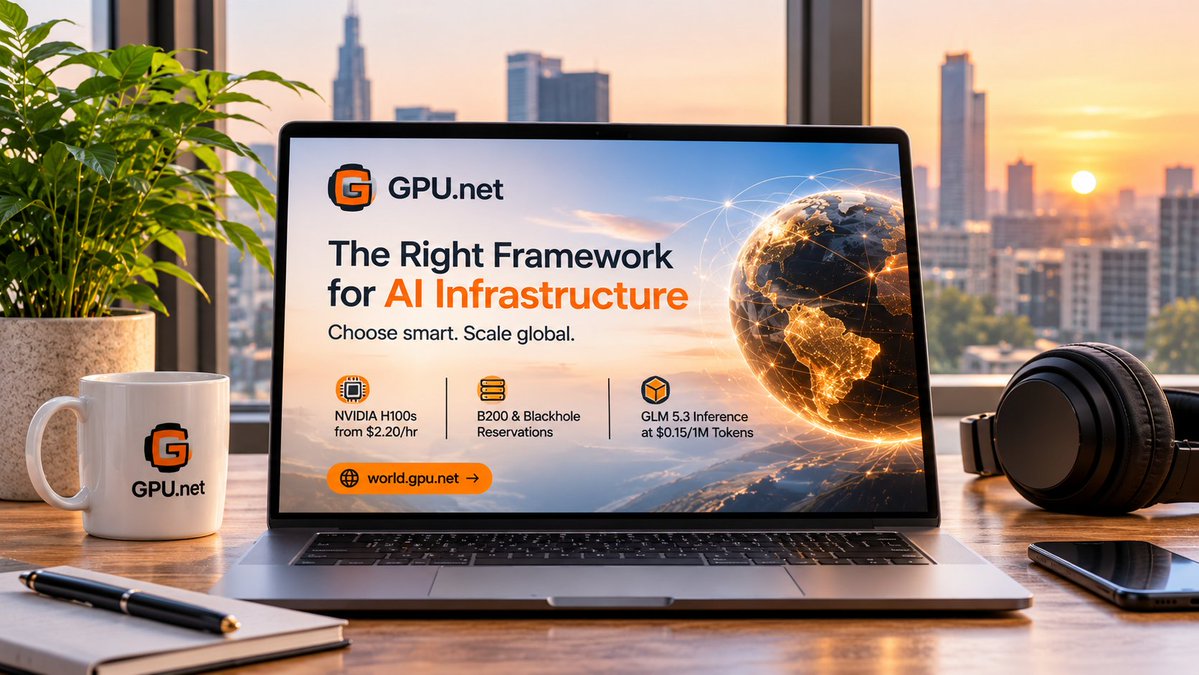
• NVIDIA H100s from $2.20/hr
• Instant B200 & Blackwell reservations
• OpenAI-compatible GLM 5.3 inference at $0.15/1M tokens
**7/7**
The future of production AI will not run on a single walled-garden cloud.
It will run on a global compute fabric that routes workloads by cost, geography, and latency.
Explore the full @gpunet compute, model, and yield ecosystem:
https://t.co/FFDneeZvR0
Level 01: Mumbai ✅ Full room.
Level 02: Bengaluru 🎮
Gaming × AI × GPU pre-summit
📅 Thu, Oct 22 · 4–6 PM IST
👾 328 players already going
For gaming pros with 5+ years in the game. Conversation-driven, hosted by @gpunet.
Player 329? Request to join 👉 https://t.co/EwuF03RP99
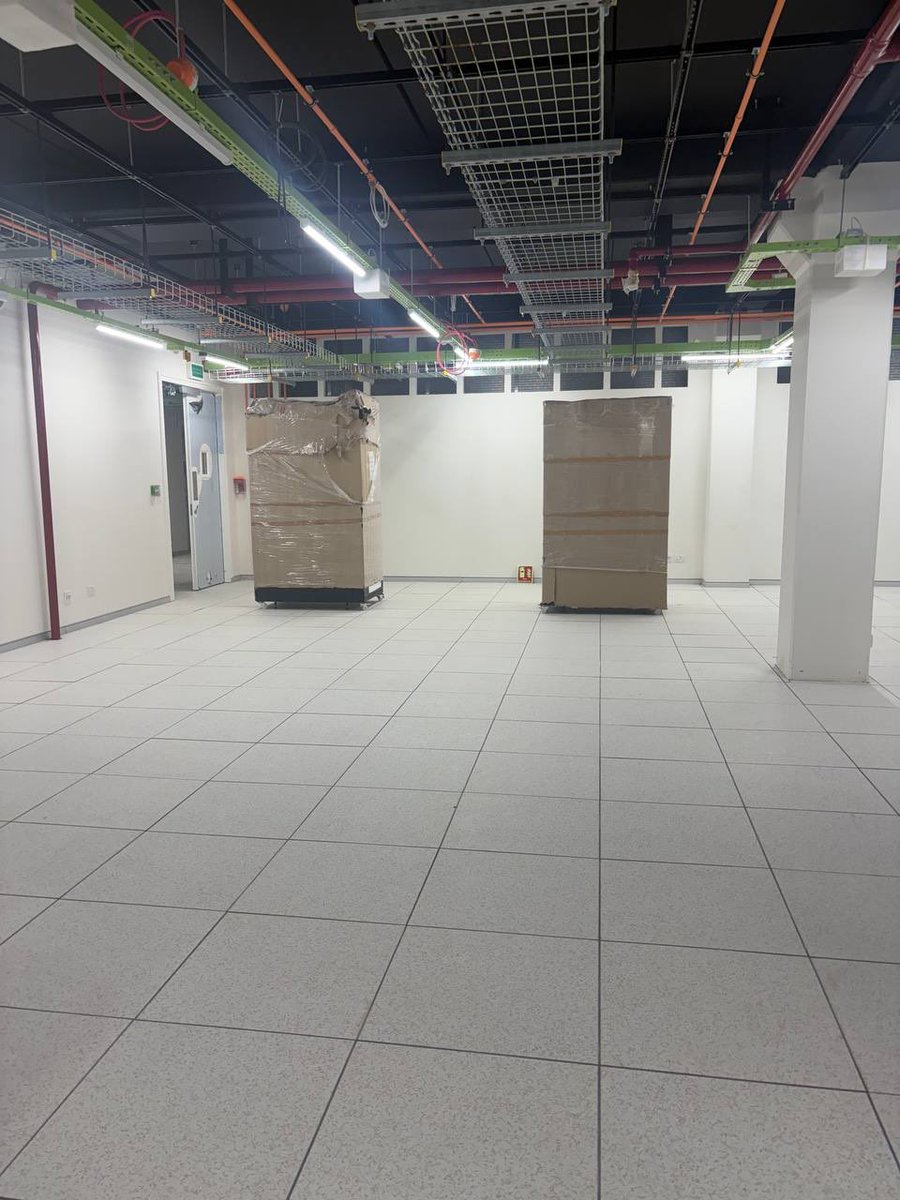
Racks landed in Bangalore 🔥
Not rented. Ours.
🔸 40 servers across Mumbai and Bangalore
🔸 1,280 Tenstorrent Blackhole chips
🔸 23 PFLOPS FP8 per server
🔸 From $0.69 per chip / hour
link: https://t.co/KN3eFb6jlC
GPUNET Models is live 🔥
Keep your OpenAI SDK. Change one line.
🔸 OpenAI-compatible API
🔸 GLM 5.3 from $0.15 / 1M tokens
🔸 Create an API key in seconds
🔸 Works with cURL and the OpenAI SDK
Link: https://t.co/Yt5QYKGsho
Sovereign AI needs more than GPUs. It needs every layer under control.
GPUNET runs the whole GPU Sovereign Stack.
🔸 Energy
🔸 Chip
🔸 Datacenter
🔸 Model
🔸 Application
18 datacenters. 8+ countries. Pick the geography that matches your data residency.
Drop-in replacement. Unbeatable token economics.
@gpunet Models is officially live 🔥
Switch your provider in 1 line of code:
• ⚙️ 100% OpenAI-Compatible API
• 🧠 GLM 5.3 starting at $0.15 / 1M tokens
• 🔑 Instant API key generation
• 💻 Plugs natively into cURL & the OpenAI SDK
Stop paying single-provider premiums.
👉 Claim your API key: https://t.co/A4o2goKspc
GPU RWA Batch 02 is now live.
Target: $250,000
🔸$1,000 minimum
🔸20% APR
🔸Paid in USDC at the end of term
🔸Target term under 12 months
Link: https://t.co/hV2V9q52mQ
RWA #2 is filling 🔥
Target: $250,000
🔸$1,000 minimum
🔸20% APR
🔸Paid in USDC at the end of the term
🔸Target term under 12 months
Link: https://t.co/LskBunVPyW
We have Solved this. We share Transparently which Datacenter we are sourcing from - there is a Reseller agreement signed with them many years in advance.
You go directly or via us, the price remains the same, that is the Trust relationship we have built through the past years. We have been a net Revenue Accelerator for our datacenter partners.
These Datacenters partners are NTT with the longest DC footprint over decades and now setting it ourselves, been here for 4 years now. We will be here till the end of your 5 year lease contract 😘
The GPU brokers have gone crazy.
I got two offers this morning for the same data center and same specs. 20% price difference between them. This has happened multiple times in the last few months.
Pretty common for a market with no price discovery. Too much demand, not enough supply, and suddenly everyone's a broker.
At some point you have to wire $2-10 million to someone you've never met and hope they don't disappear.