@TrelisResearch@vikhyatk@snowclipsed@teortaxesTex@j0yk1ll No, they compare (I think) adding pooled features vs. concatenate. So x_global + pooled(x_1,...) vs. concat(x_global, pooled(x_1,...). I tested concat(x_global,x_1,...), too, but that was worse despite more features (maybe too many?)
Thanks to a GPU grant by @huggingface , you can try out Centurio Aya here: https://t.co/pkE1XpYWyE
(code shamelessly adapted from @mervenoyann demo of Llava-Next)
Want to train a *multilingual* LVLM but not sure how? Or looking for a strong model to use?
Presenting "Centurio: On Drivers of Multilingual Ability of Large Vision-Language Model"!
Arxiv: https://t.co/CAnajHAAkU
HF Collection: https://t.co/dUkThaadbv
@vikhyatk@snowclipsed@teortaxesTex@j0yk1ll Can confirm this works well. Used it for my recent model, too, because those mega long sequence lengths are a pain to train with.
Do you pool the crops or concatenate them all together channel-wise? I found pooling to work better, surprisingly.
Want to train a *multilingual* LVLM but not sure how? Or looking for a strong model to use?
Presenting "Centurio: On Drivers of Multilingual Ability of Large Vision-Language Model"!
Arxiv: https://t.co/CAnajHAAkU
HF Collection: https://t.co/dUkThaadbv
Next, we apply our lessons learned to train Centurio - state-of-the-art multilingual LVLMs trained with 100 languages based on Aya-Expanse @CohereForAI and Qwen 2.5 @Alibaba_Qwen.
Weights on HuggingFace!
📣Happy to (pre-)release my Fleurs-SLU benchmark to evaluate massively multilingual spoken language understanding on SIB & Belebele. Work done at @Mila_Quebec with @davlanade@gg42554@licwu
Datasets:
https://t.co/wqSfkT3VA3
https://t.co/882nh8znY1
Details to follow👇
@mervenoyann@visheratin Right, good point that. As a PhD student at a university, I don't have to pay too much attention if something is commercially permissible but that's not true for others, of course.
"Grounding tasks improve fine-grained image understanding which helps reduce visual hallucinations in Vision-LLMs"
Intuitive claim and often repeated but is it *true*?
We tested it in our recent paper: https://t.co/gNBsnZFL2o
🧵 (spoiler: no)
The monkey's paw worked well, so I will present 2(!) posters at @emnlpmeeting Wednesday at 4pm.
I will be easy to spot - just look for the guy with crutches🩼
Could you use your Vision-LLM to help identify dogs, plants, dishes, or other things?
We investigated and let's just say, do not rely on them when foraging mushrooms in the wild...
Paper: https://t.co/a9NBjwnJOg
Code: https://t.co/lvlePH5YJB
🧵
Excited to present NLLB-LLM2Vec at @emnlpmeeting Tuesday 2pm! Drop by our poster to chat about multilingual & multimodal research. NLLB-LLM2Vec can now easily be used with @huggingface AutoModels — try it esp. for embedding low-resource languages!
🌐 https://t.co/8E1wm2lJ0P
🌍 I’ve always had a dream of making AI accessible to everyone, regardless of location or language. However, current open MLLMs often respond in English, even to non-English queries!
🚀 Introducing Pangea: A Fully Open Multilingual Multimodal LLM supporting 39 languages! 🌐✨
https://t.co/lHP1CSNNVe
https://t.co/RkMdE4JSQg
The Pangea family includes three major components:
🔥 Pangea-7B: A state-of-the-art multilingual multimodal LLM capable of 39 languages! Not only does it excel in multilingual scenarios, but it also matches or surpasses English-centric models like Llama 3.2, Molmo, and LlavaOneVision in English performance.
📝 PangeaIns: A 6M multilingual multimodal instruction tuning dataset across 39 languages. 🗂️ With 40% English instructions and 60% multilingual instructions, it spans various domains, including 1M culturally-relevant images sourced from LAION-Multi. 🎨
🏆 PangeaBench: A comprehensive evaluation benchmark featuring 14 datasets in 47 languages. Evaluation can be tricky, so we carefully curated existing benchmarks and introduced two new datasets: xChatBench (human-annotated wild queries with fine-grained evaluation criteria) and xMMMU (a meticulously machine-translated version of MMMU).
🙌 This is a joint leading effort with @yueqi_song. Also kudos to the amazing team @AkariAsai, @seungonekim, @Jeande_d, @simi_97k, @anjali_ruban, @lintangsutawika, @Sathya8NR, @gneubig for their hard work!
Check out more results and insights we conclude from our training in the thread below. 👇
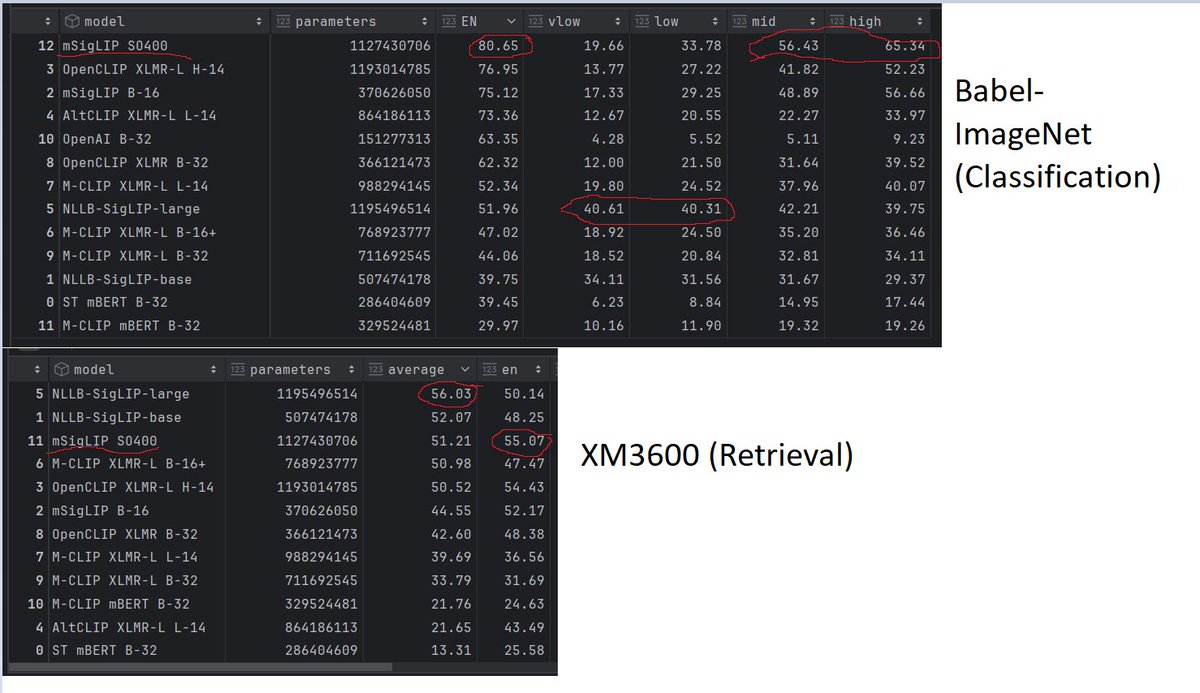
@giffmana I knew of the B/16 model but must have missed that one.
So I tested it to shamelessly plug my work (https://t.co/ZtaQhGSXyn):
For classification, it is by far the best for English + mid/high-res languages.
Retrieval lags behind NLLB-SigLIP (-English).
tl;dr: SigLIP sweep
@ChenLiu47008770 Not surprising since your work was the main inspiration for the master's thesis 👍
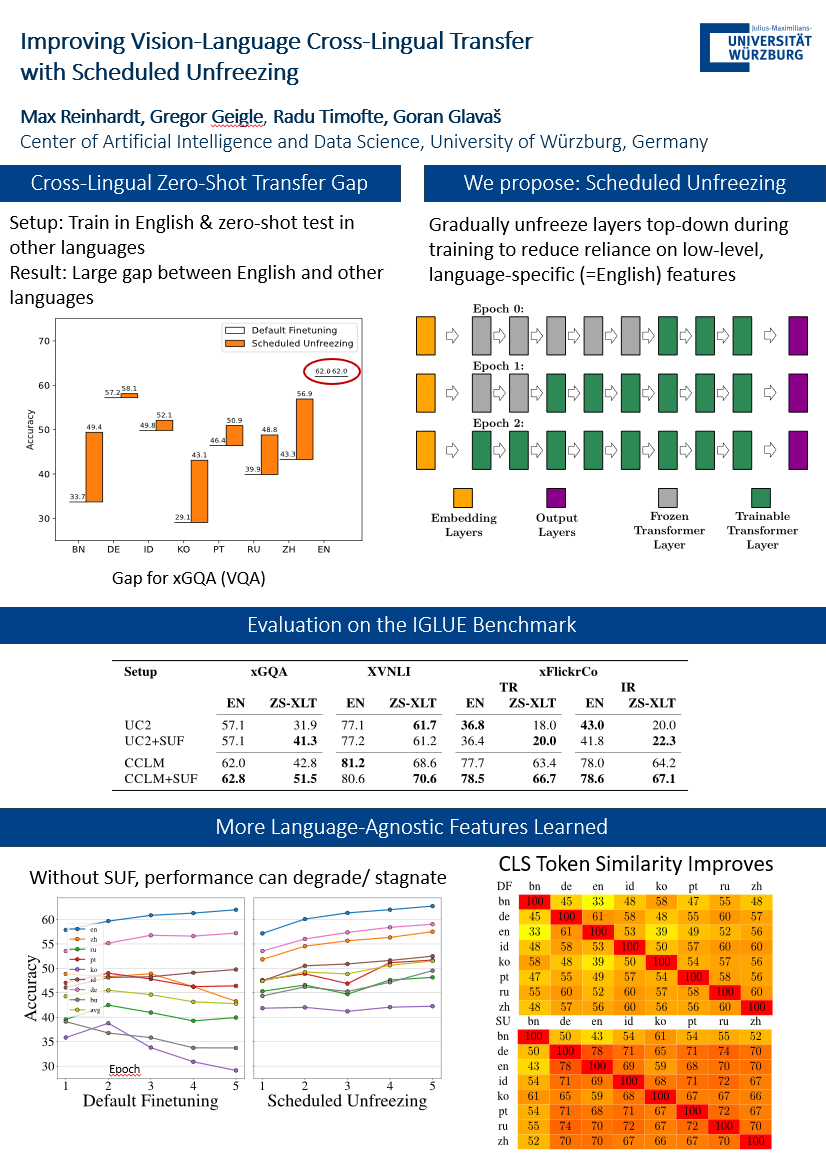
We did not use Fisher's information, though. Only a simple epoch-wise schedule top-down.
A broken ankle might stop me from going to #ACL2024 myself but it won't stop *you* from checking out my accepted papers (1x main conference, 2x workshop):
... 2) the thesis of my first Master's student Max: "Improving Vision-Language Cross-Lingual Transfer with Scheduled Unfreezing" (in the workshop proceedings).