We're open-sourcing RL360, the RL infrastructure behind K2 Horizon's six domain experts: 8,192 concurrent sandboxes, 150 steps in 7 days, ~1.3M rollouts.
Long-horizon agentic RL runs thousands of agents in real sandboxes on tasks that take minutes. Some of those sandboxes crash mid-task, and a crash arrives as the same low score as a wrong answer.
Without infrastructure that can keep up, GPUs are underutilized and the model gets penalized for system crashes rather than its own mistakes.
RL360 is built for this. We share how it works, what broke at scale, and what we learned in the thread.
Code: https://t.co/eA46QBpfTx
Run: https://t.co/cd4tOV3OXv
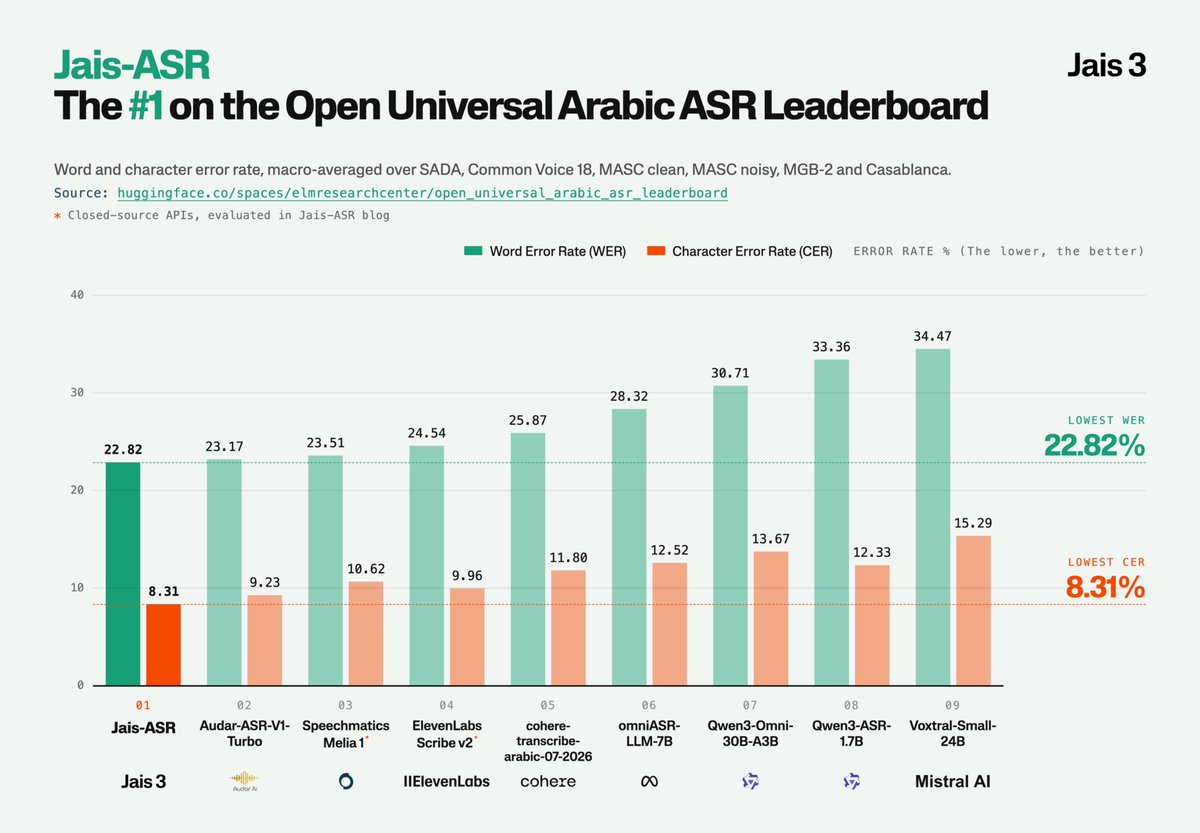
Jais-ASR ranks #1 on the Open Universal Arabic ASR Leaderboard.
Our open model is built for Modern Standard Arabic and dialects from 19 countries.
Beyond the leaderboard, it handles:
- Natural code-switching with English, French, Spanish, and Italian
- Robustness to background noise
- Faithful transcription, resistant to hallucinations
- Arabic diacritization
- Built-in language and dialect identification
Weights released under Apache 2.0: https://t.co/kXjQEqVXvU
Jais 3: First adaption of K2 Horizon
Jais 3 is built on K2 Horizon, our six-fleet fully open model family.
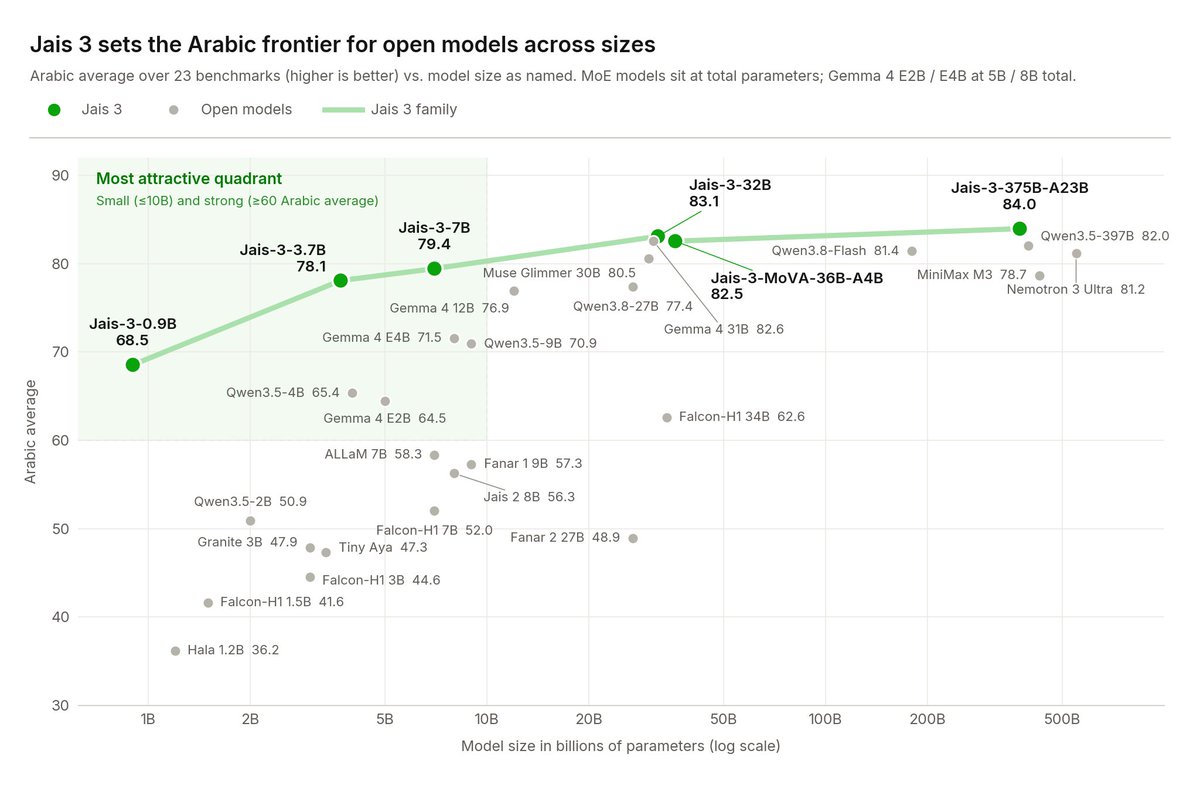
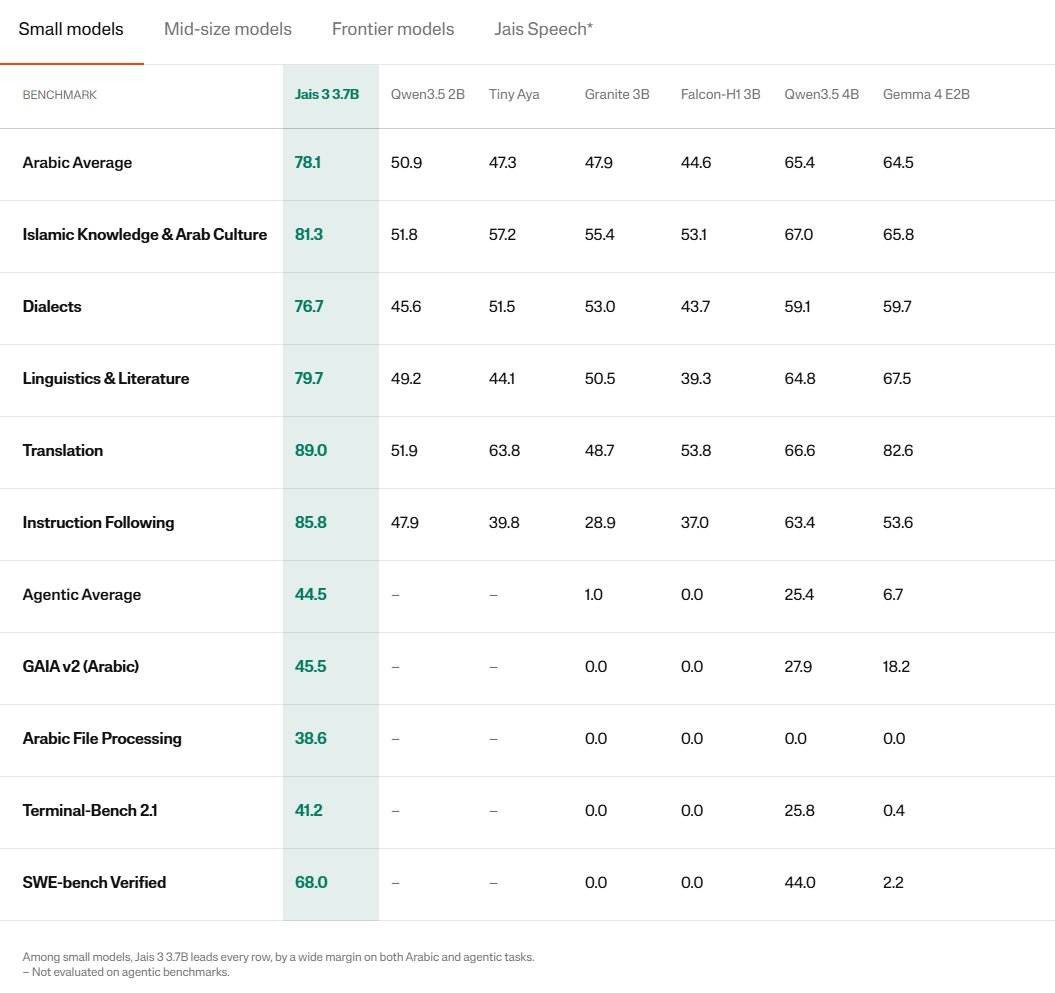
Stronger in Arabic at every size, without starting from scratch. Plus Jais Speech, the most accurate open Arabic ASR.
Download weights now: https://t.co/Q2ZI1PIZLo
Introducing Jais 3, Arabic-native agentic AI.
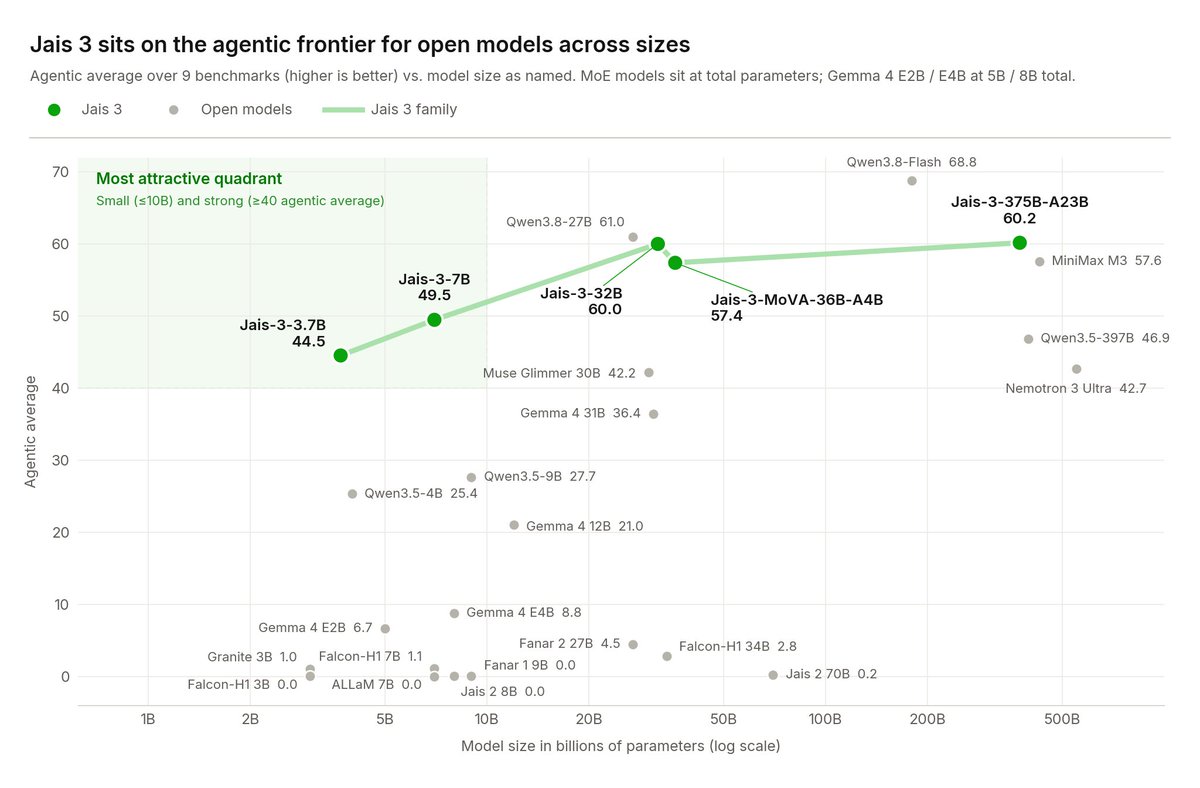
Jais 3 375B matches the best open models, and with Jais Speech offers the most advanced Arabic AI stack available.
→ Hugging Face: https://t.co/Ecvx8FhZvG
→ Technical blog (Jais 3): https://t.co/9bHZeFSU2D
→ Technical blog (Jais Speech): https://t.co/SuiqdPKrF2
→ Learn more: https://t.co/ZIAg1xmS6l
Jais 3 was created by the Institute of Foundation Models (IFM) at MBZUAI, in collaboration with Inception42 and Cerebras Systems.
#Jais3 #IFM #MBZUAI
Rework is inevitable in large-scale LLM pre-training and fine-tuning. What it costs isn't.
Introducing xLLM, an efficient and flexible infrastructure for pre-training and fine-tuning dense and MoE LLMs. It keeps key training decisions changeable without giving up throughput.
Efficient, at 6,295 tokens/sec per GPU on K2-Horizon-MoVA-36B-A4B and 10,050 tokens/sec per GPU on Llama3-8B on H200s.
Flexible, because the tokenizer, data mixture, model architecture, and training stages can change without rebuilding the dataset or the system around them.
xLLM ships with the checkpoints, training logs, and recipes behind K2 Horizon: https://t.co/FJ2mg3OMdb
K2-Horizon-MoVA-36B-A4B: https://t.co/lH2BYBdmaC
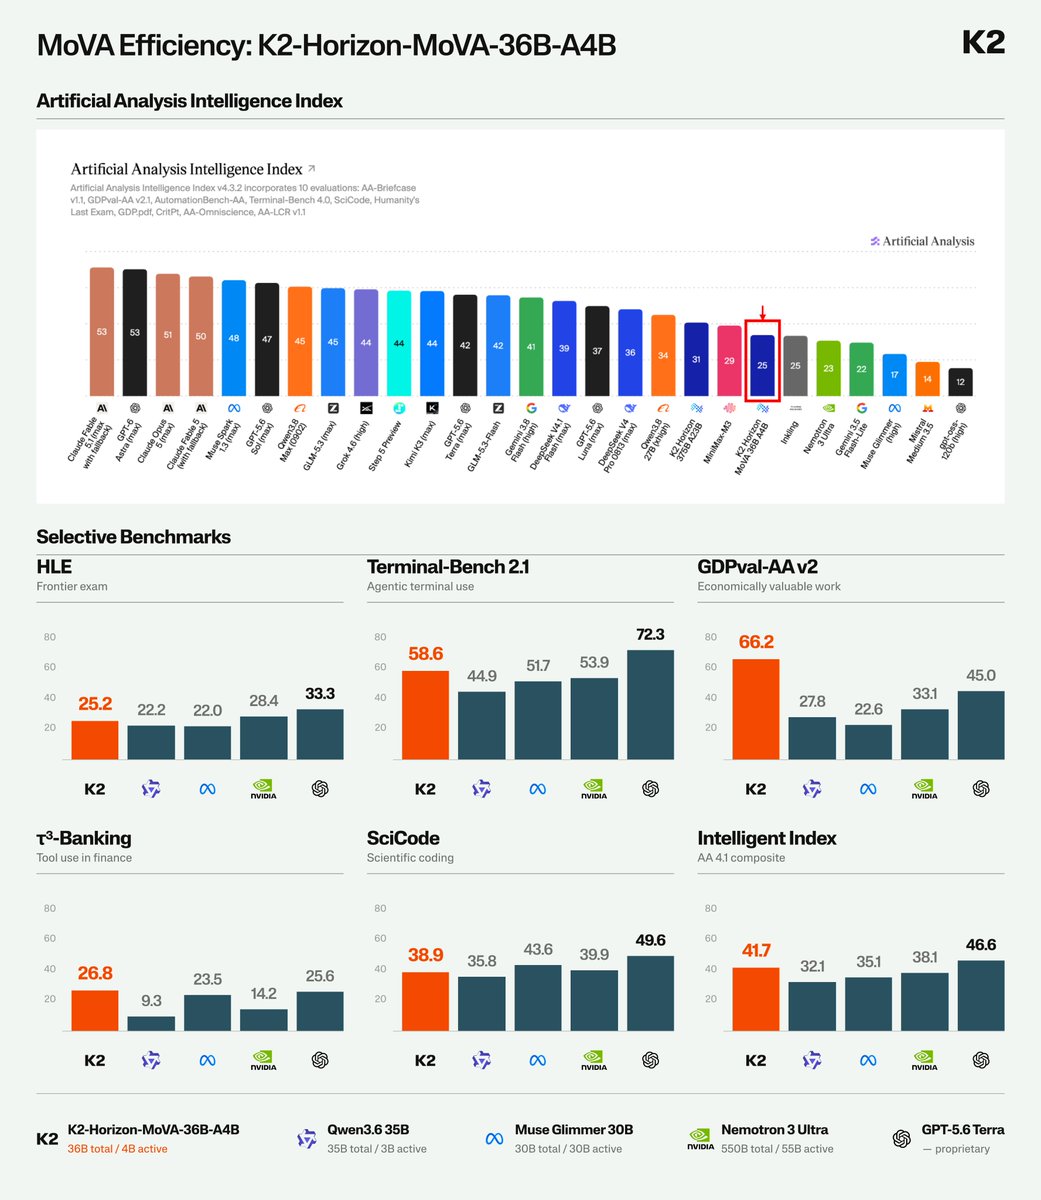
K2-Horizon-36B-A4B scores 25 on the Artificial Analysis Intelligence Index, matching models with over 20× the total parameters while using 4B active parameters per token.
These capabilities come from our new architecture MoVA (Mixture-of-Value Attention), which incorporates MoE-based sparsity into the compute of value vectors in multi-head attention.
It opens a second axis for scaling sparsity in an LLM, beyond MoE in the FFN module. Importantly, MoVA enjoys the following advantages:
• Simple and compatible with efficient attention algorithms, such as flash attention, GQA, and sparse attention
• No additional KV cache cost comparing to standard GQA
K2-Horizon-36B-A4B available at: https://t.co/lH2BYBdU0a
Today’s LLMs still write like typewriters: one token at a time. This sequential process creates a hard inference bottleneck.
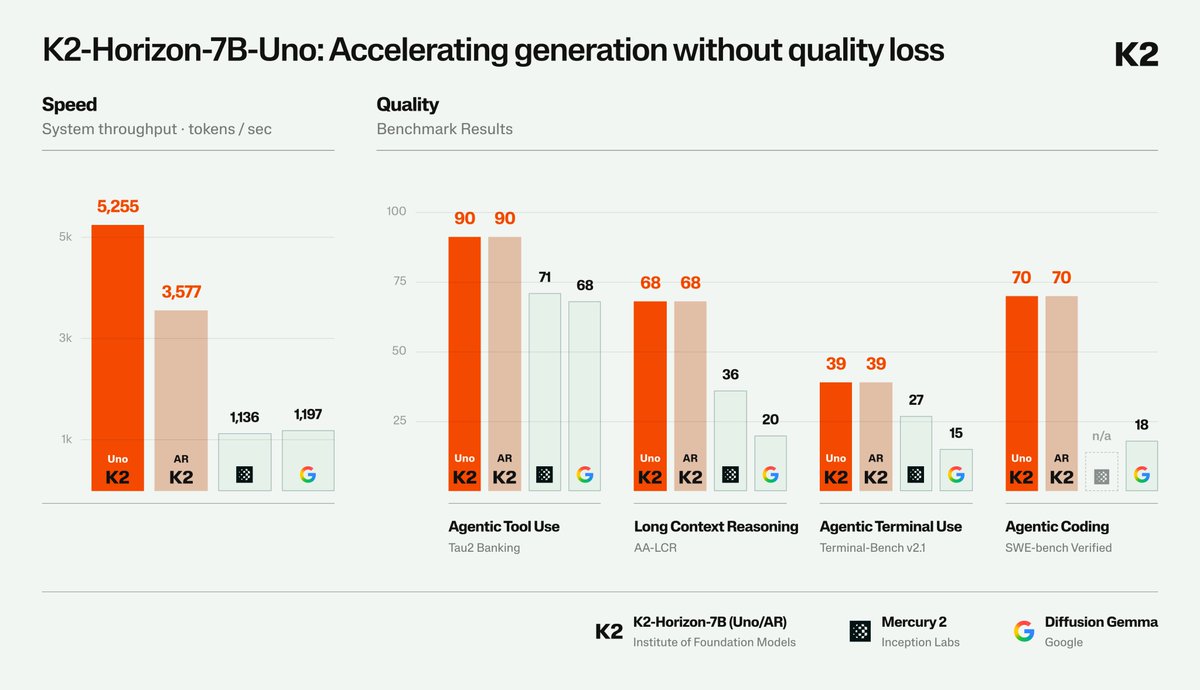
We're introducing Uno, a diffusion-augmented LLM that delivers autoregressive quality at diffusion speed. It’s a lossless speedup method that accelerates generation without degrading response quality.
With Uno, K2-Horizon-7B outperforms state-of-the-art diffusion methods in both quality and throughput, delivering up to a 2.2× speedup with no loss in quality.
Paper: https://t.co/VSLsf01oBo
Model available at: https://t.co/k1dKDwhaCm
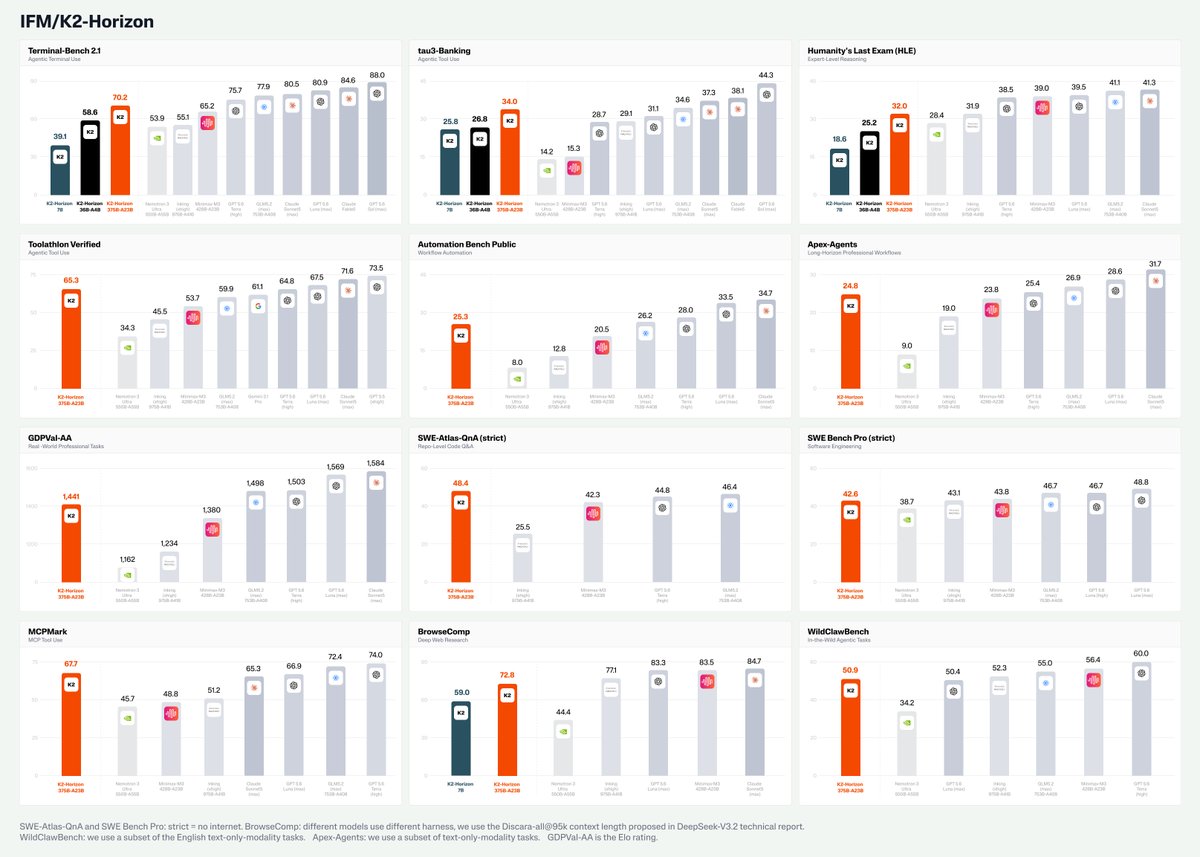
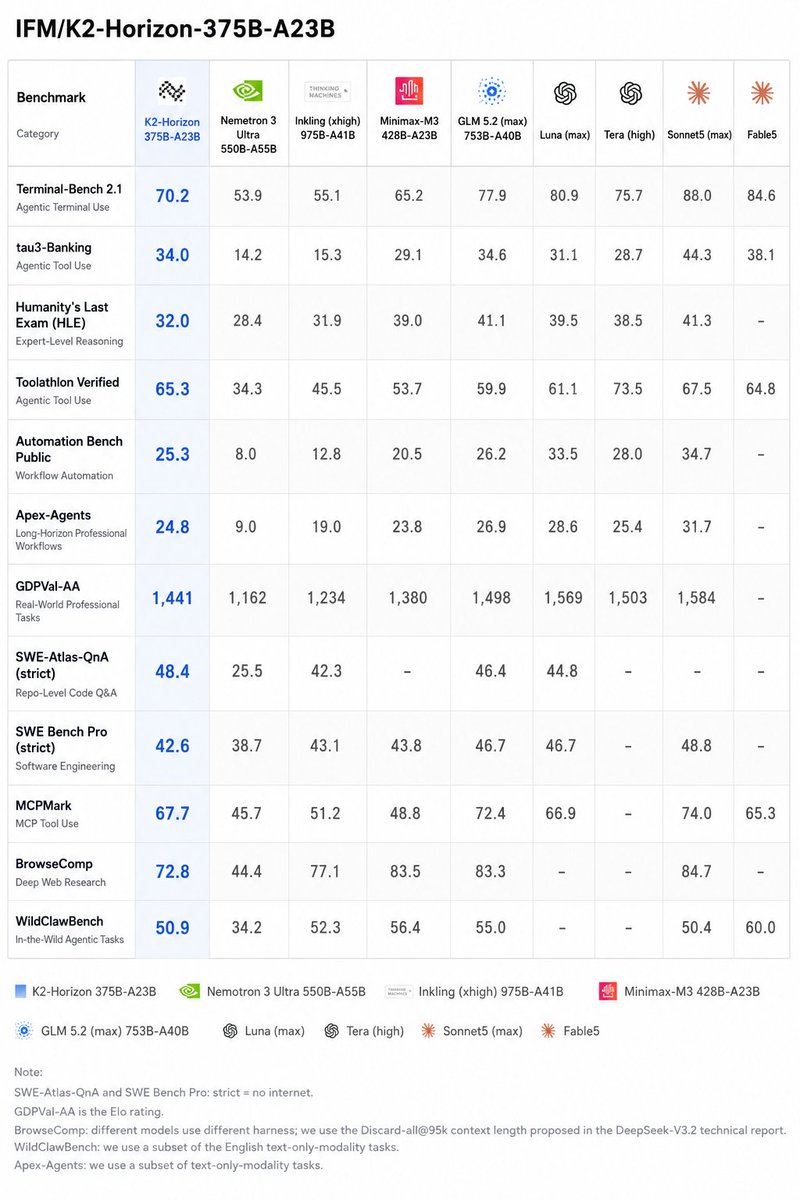
Introducing K2 Horizon: a connected fleet of six foundation models ranging from 0.9 billion to 375 billion parameters.
- Frontier performance: Across coding and agentic tasks, K2 Horizon delivers top-tier performance in every size class—with the 0.9B, 3.7B and 7B models setting new state of the art at their respective scales.
- Radical openness: K2 Horizon represents the largest fully open-source model launch in AI history. The fully open code, training data and recipes are a significant step forward in transparency.
Launch page: https://t.co/gg0k803SbL
Tech blog: https://t.co/g35L5xMGdS
Hugging Face: https://t.co/3Lb28JhyG9
🔊 This may be one of the most interesting OPEN Local AI releases of the year.
🎯 New MoE arch approaching a dense arch.
IFM dropped K2 Horizon. A set of six models from 0.9B → 375B.
🧠 K2 Horizon 36B-A4B stats...
36B total parameters
⚡ only ~4B active/token
📚 512K native context
🤖 coding + agentic training
🦙 GGUFs already appearing
It uses a new architecture called MoVA (Mixture-of-Value Attention)
Normal MoE makes the FFN sparse.
MoVA brings expert routing into ATTENTION too.
🎯 IFM says the result gets close to its dense 32B model while activating only ~4B parameters/token.
Open Everything! IFM says it's releasing:
🔓 Model weights
📦 Training data/recipes
🧑💻 Training code
🧪 Intermediate checkpoints
📊 Fine-grained training logs
🧠 Agentic post-training recipes
📜 Apache 2.0
And the family goes all the way down to:
⌚ 0.9B → watches / glasses
📱 3.7B → phones
💻 7B → local agents
🖥️ 32B → workstation
⚡ 36B-A4B → local MoE sweet spot
🏢 375B-A23B → big iron
Now give me that 36B-A4B at Q4. 😁
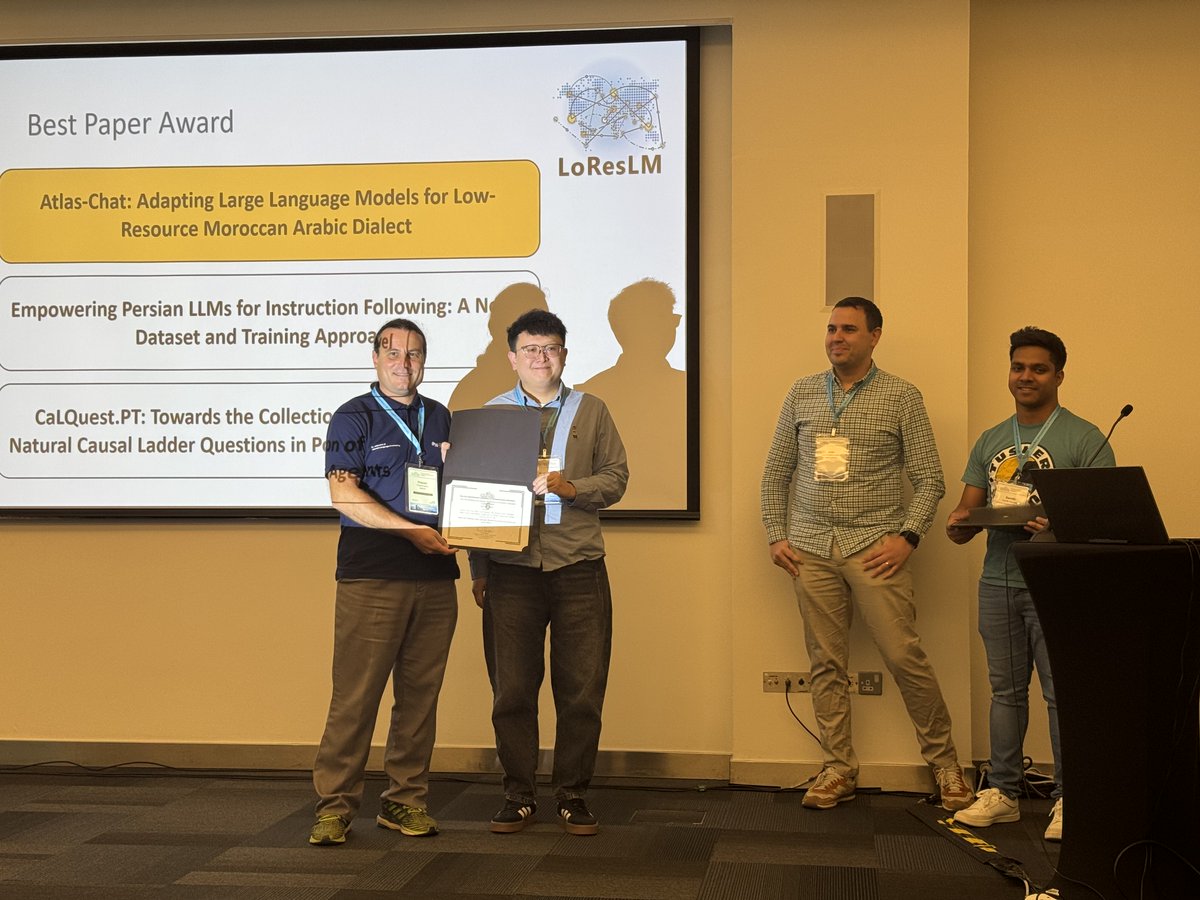
Congrats to the #MBZUAI team for winning the Best Paper Award at the COLING 2025 workshop on Language Models for Low-Resource Languages (LoResLM 2025) for “Atlas-Chat: Adapting Large Language Models for Low-Resource Moroccan Arabic Dialect”.
Developed by our France Lab, here’s what you need to know about Atlas-Chat:
* 1st ever LLM for Darija, an Arabic dialect in Morocco
* Atlas-Chat-9B outperforms existing 13B models with a 13% boost on DarijaMMLU
* Introduces several LLM benchmark datasets for Darija
* Pioneers methodologies for low-resource languages
* All resources are fully open to the public
Link to paper: https://t.co/n67QCsrWu8 Atlas-Chat is also available on HuggingFace in 2B, 9B, and 27B parameter models: https://t.co/fzKwDKYyhT
#LLM #LLM360 #AI
Best paper at LoResLM@COLING2025: Atlas-Chat: Adapting Large Language Models for Low-Resource Moroccan Arabic Dialect https://t.co/WLZAdOBtZa #COLING#MBZUAI#LLM
🚀 Prot2Text is now available on Hugging Face 🤗 at https://t.co/pxuACuJzQ7! You can choose from small to large versions and get detailed descriptions of your favorite proteins. We hope you enjoy it—and there's more to come!
Our work "Prot2Text: Multimodal Protein's Function Generation with GNNs and Transformers" with @hadi_abdine, @mvazirg and @cbouyio has been accepted at AAAI 2024!!🥳
Check out the thread below for more details. 🧵
1/n
Our work "Prot2Text: Multimodal Protein's Function Generation with GNNs and Transformers" with @hadi_abdine, @mvazirg and @cbouyio has been accepted at AAAI 2024!!🥳
Check out the thread below for more details. 🧵
1/n
So far all evidence that LLMs can perform few-shot reasoning on novel problems seems to boil down to "LLMs store patterns they can reapply to new inputs", i.e. it works for problems that follow a structure the model has seen before, but doesn't work on new problems.
🪐 Introducing Galactica. A large language model for science.
Can summarize academic literature, solve math problems, generate Wiki articles, write scientific code, annotate molecules and proteins, and more.
Explore and get weights: https://t.co/jKEP8S7Yfl