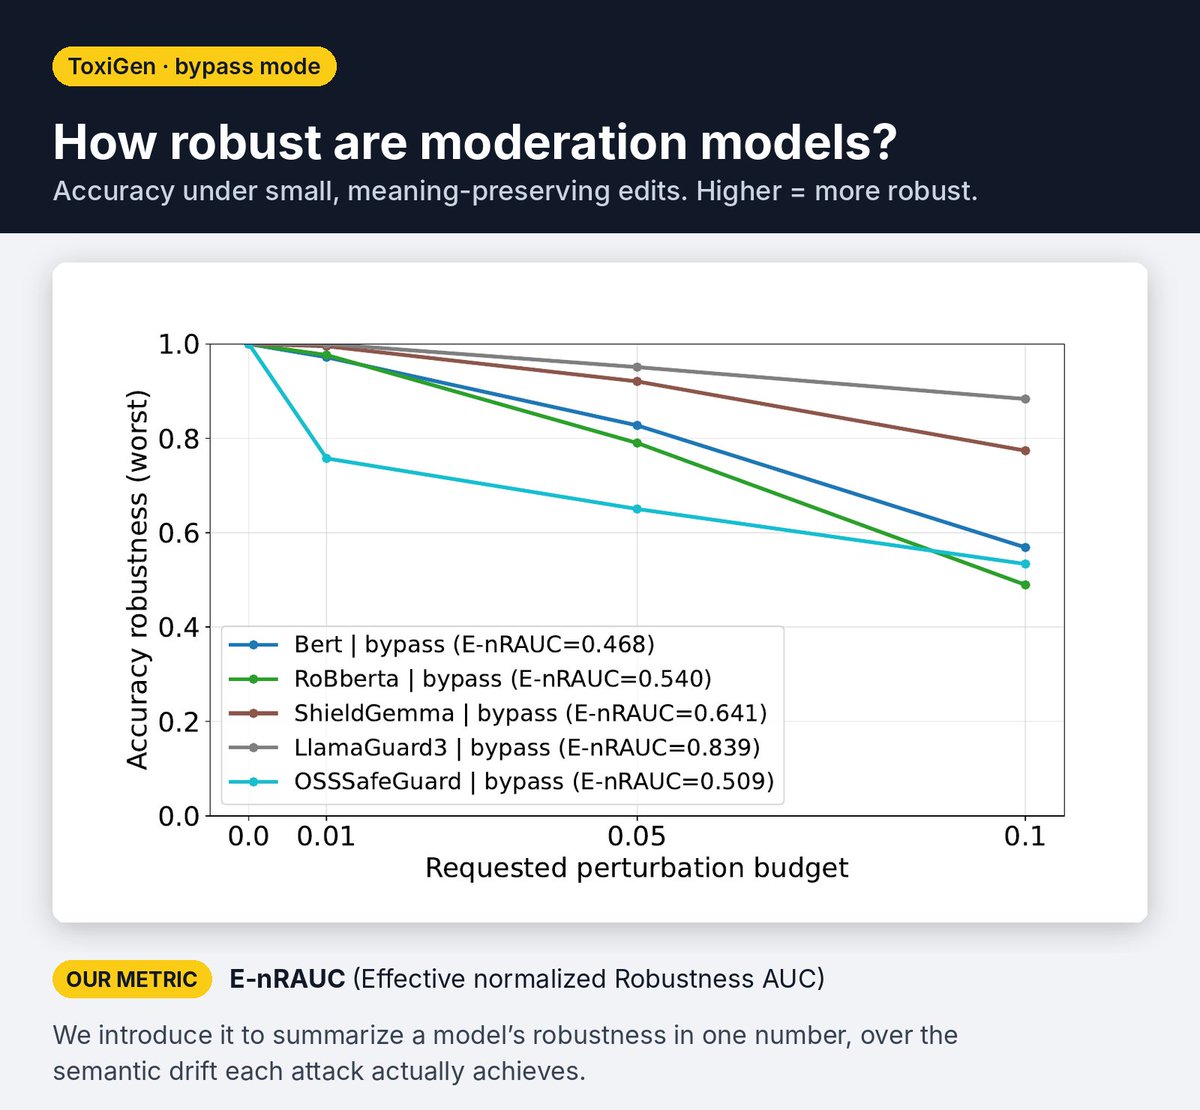
Presenting at #COLM2026 this week
We stress-test content moderation models with realistic, meaning-preserving attacks. None are fully robust, though larger models like LlamaGuard3 hold up better.
📍 Poster Session 5. Come talk AI safety, red-teaming, evals & auditing!
@ClementDelangue@nvidia Just DM’d you about an idea for an automated red teamer. I work on RL red teaming and would love to explore it with you at Hugging Face!
@polynoamial@polynoamial I recently wrote about what the OpenAI–Hugging Face incident means for multi-agent monitoring and how RL training should change in response, from isolated rollout namespaces to safer stopping incentives: https://t.co/TmZUmu39bY I also sent you a DM.
Everyone's reading the OpenAI incident as a security failure. It's also an existence proof. Nobody has built a large-scale offensive RL environment, and one built itself.
And it's an unfair game. More compute, more agents, more trajectories, more signal, better attackers. And they share, so one agent's discovery becomes every agent's prior. the loop doesn't just close, it compounds. Every probe returns a verifiable result whether it lands or not.
Defense has no equivalent loop. You can't train on attacks that never came.
https://t.co/vbs23ELXPn
Today at @USENIXSecurity Hamid will present Federated Rank Learning (FRL), an alternative to
standard federated learning. Instead of jointly fine-tuning parameters, FRL clients train the global model by ranking the edges of a randomly initialized model. https://t.co/vi3V1bjRvb