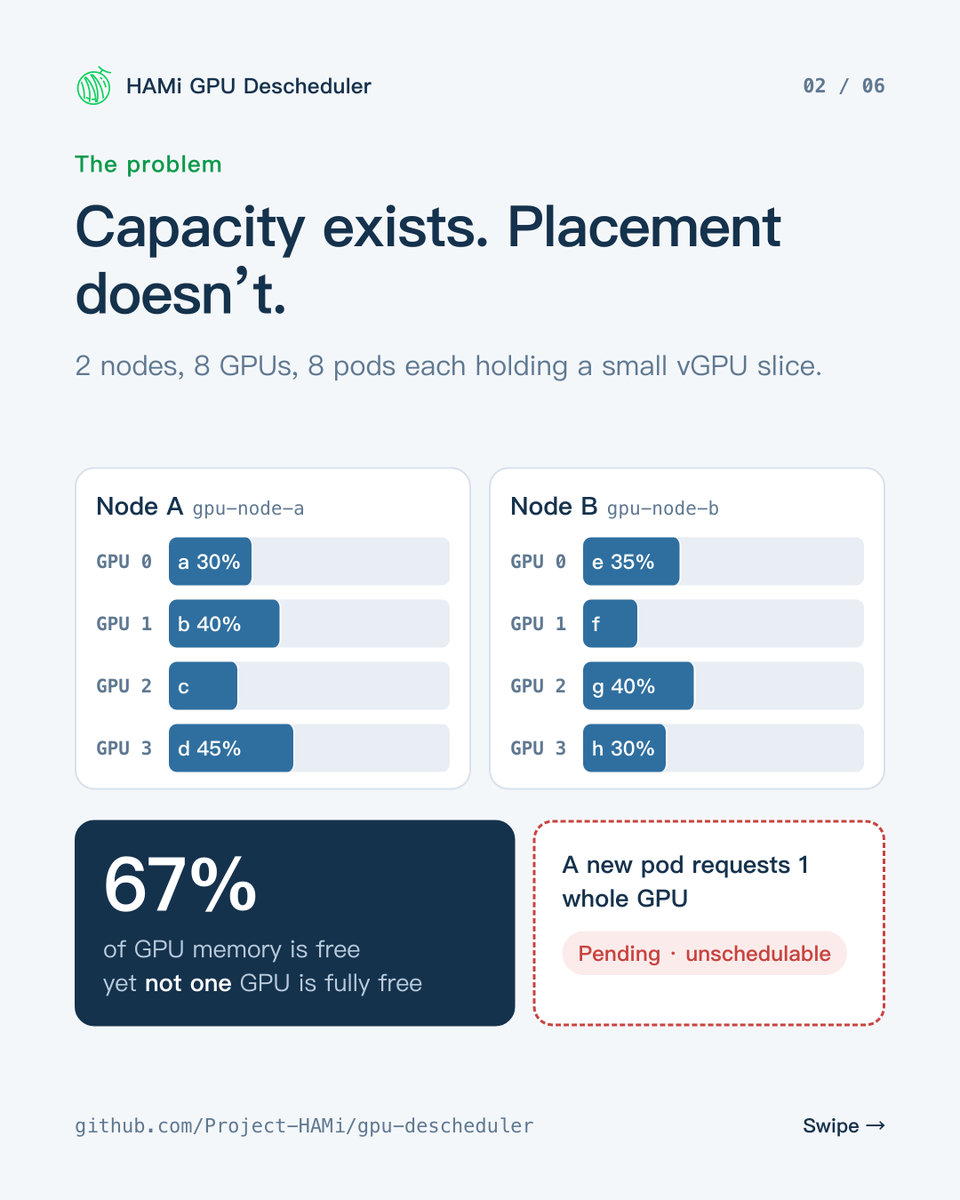
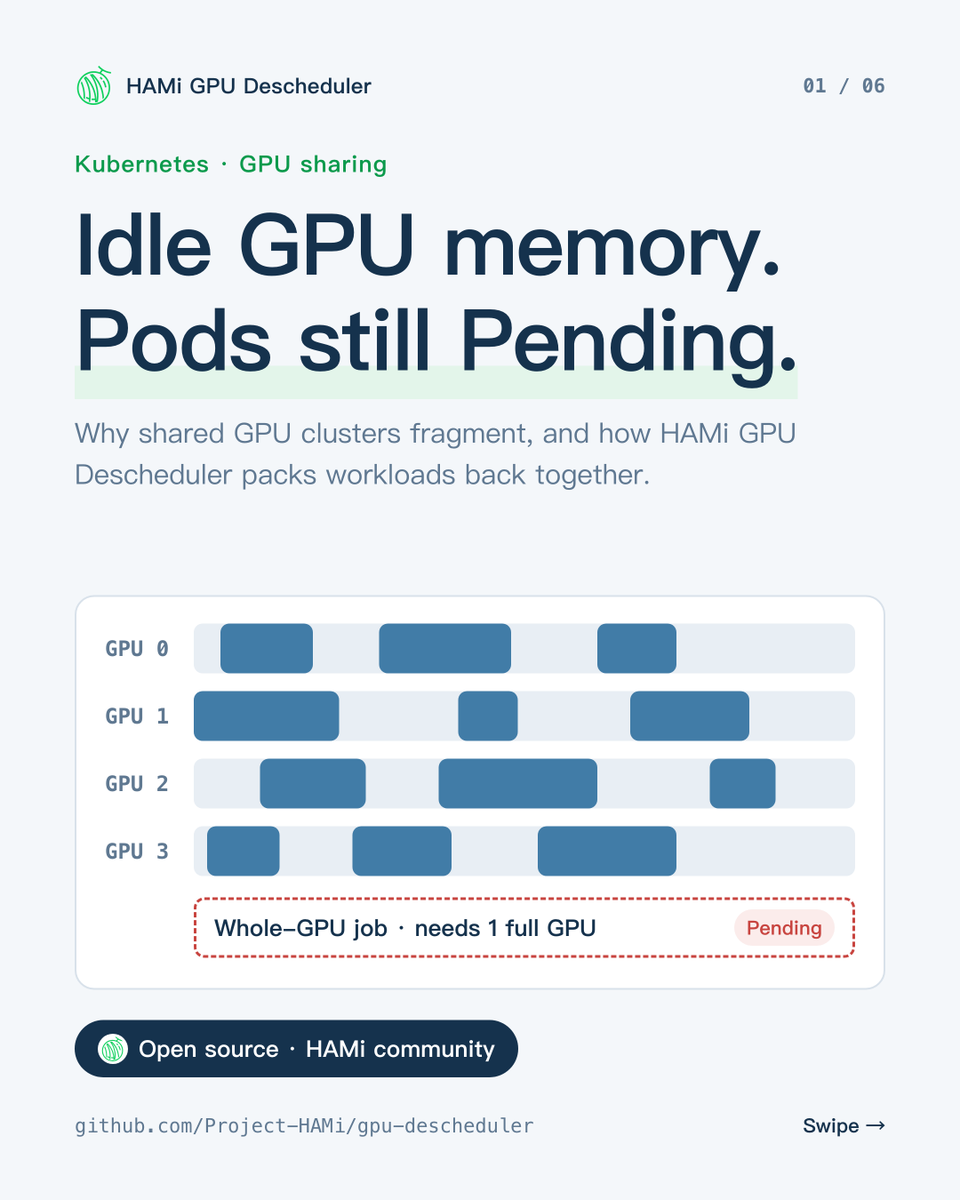
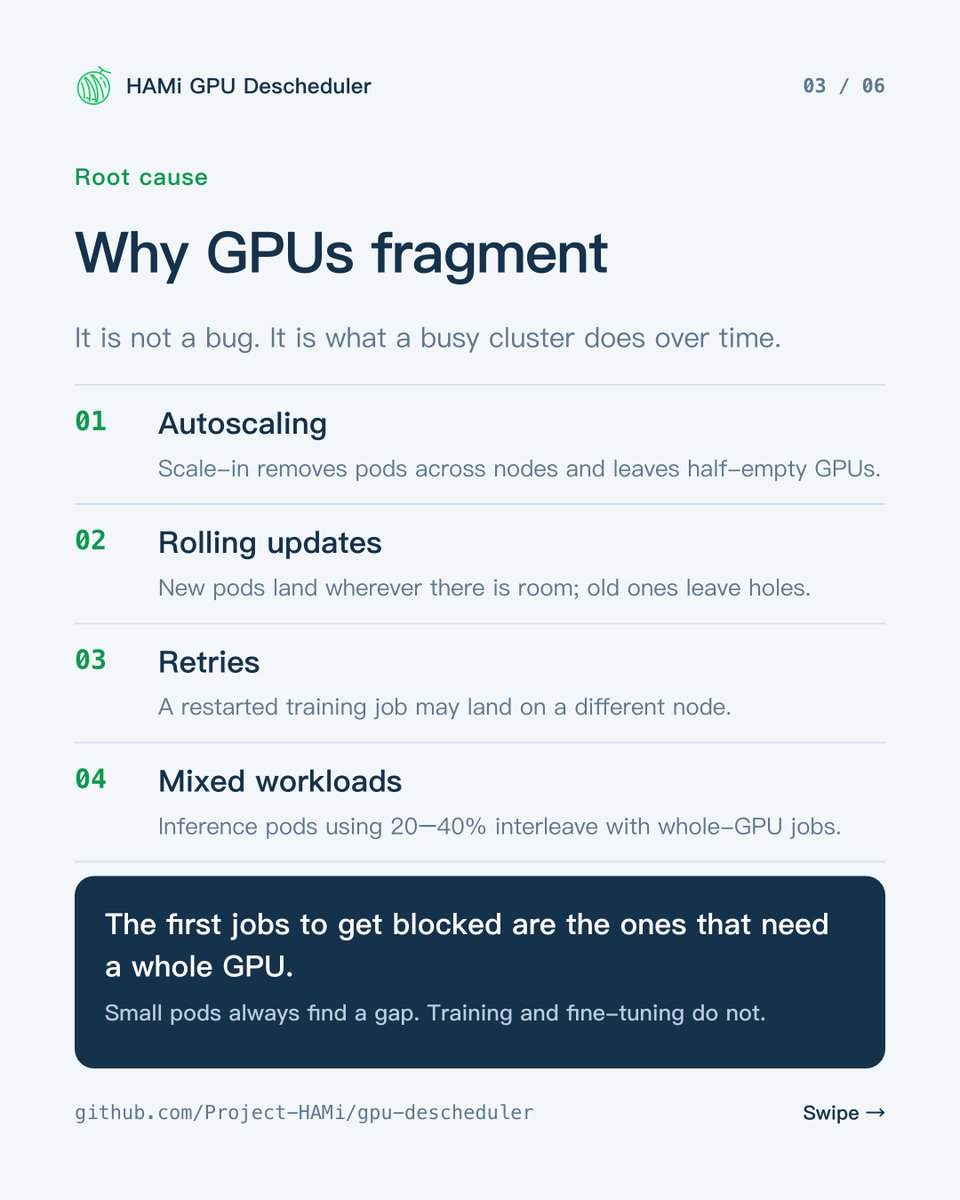
Your Kubernetes cluster has free GPU memory, but new Pods are still stuck in Pending. Why?
GPU fragmentation.
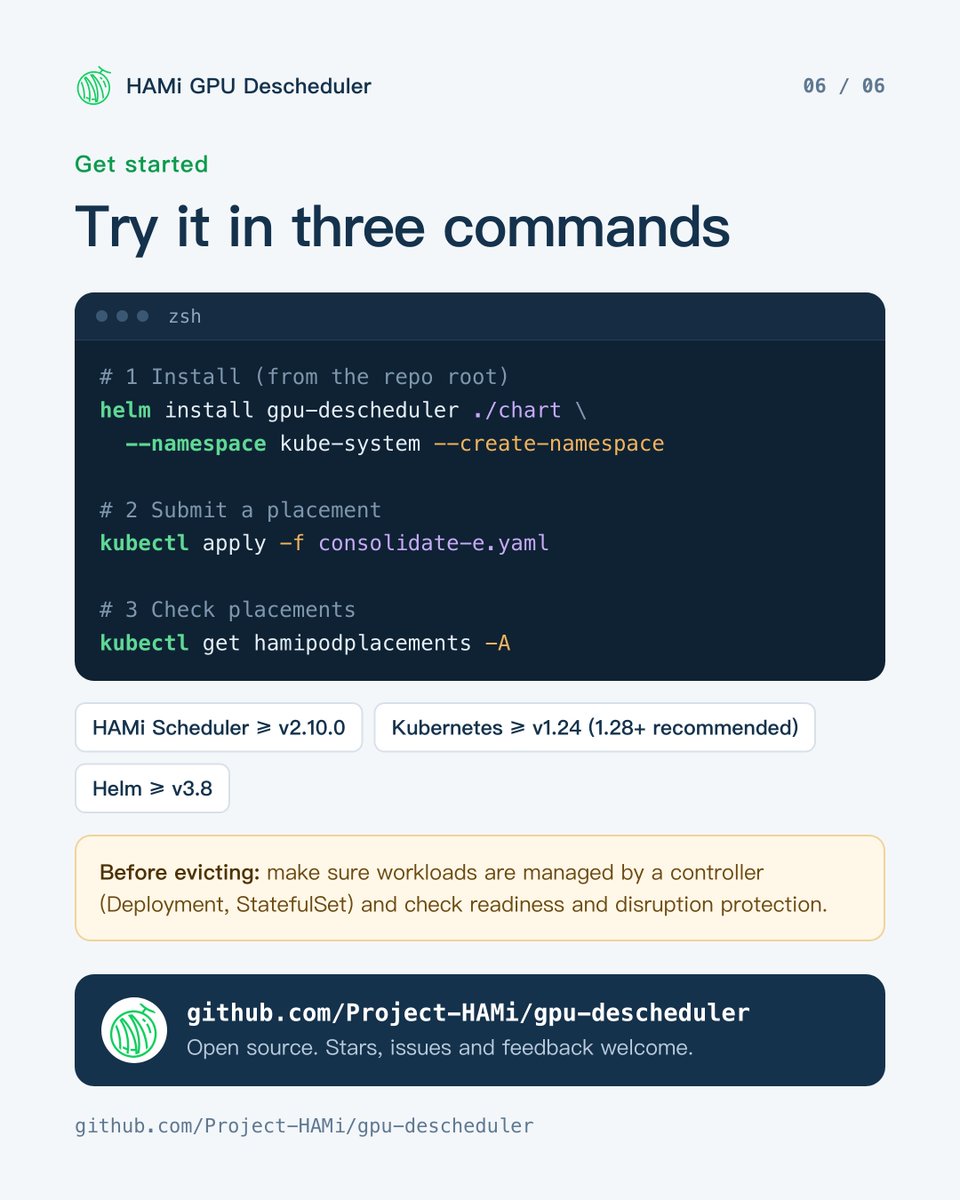
See how it works and try it out 👇
🔗 https://t.co/qzpLBUjg04
#HAMi#Kubernetes#GPUSharing
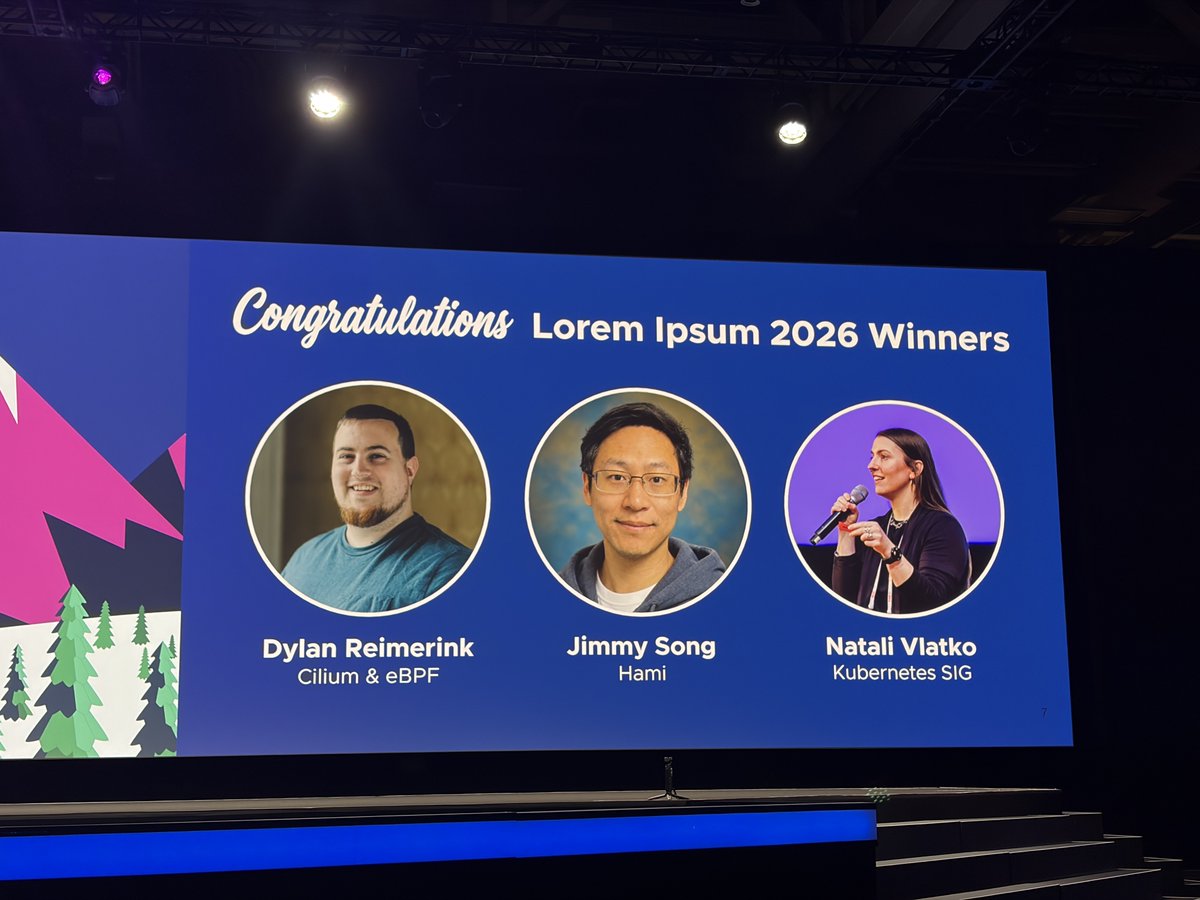
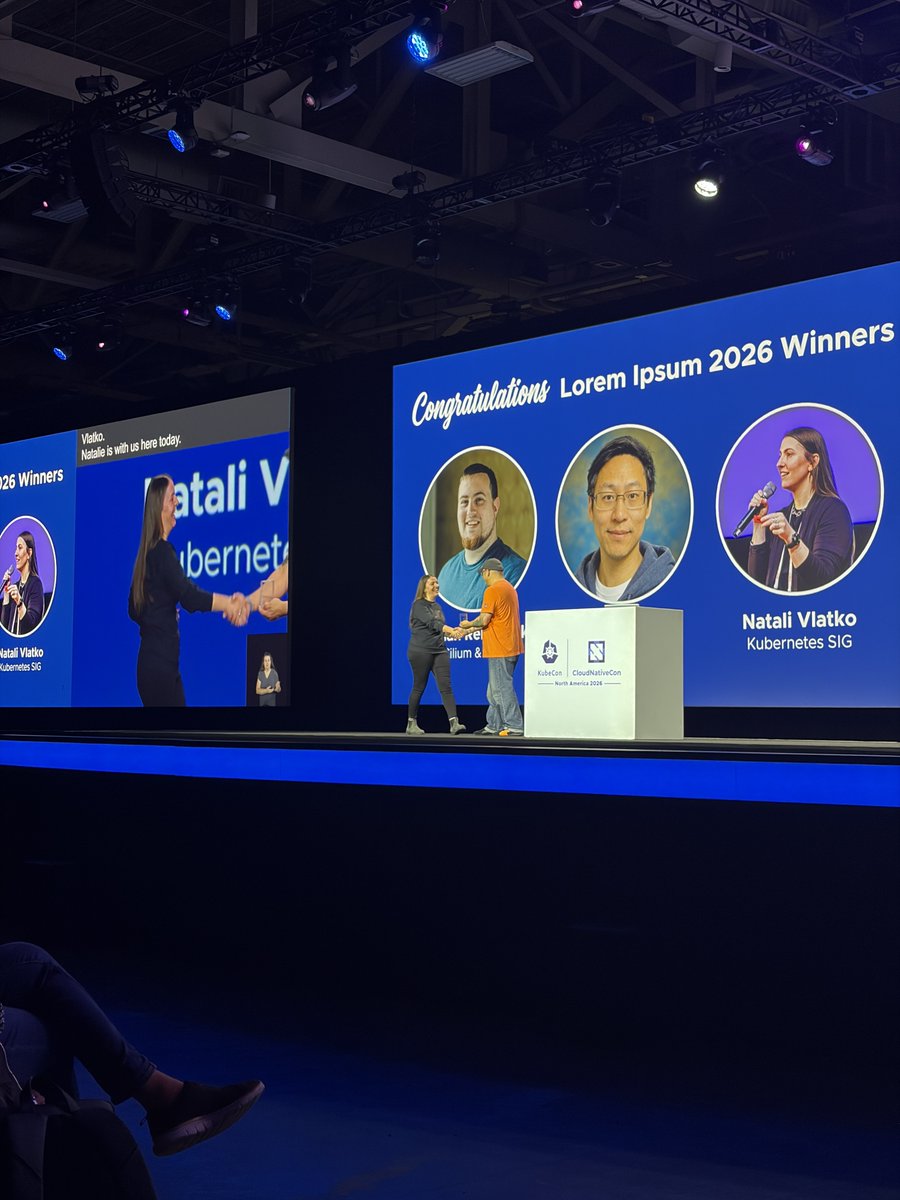
Live at KubeCon + CloudNativeCon North America: Congratulations to our 2026 Lorem Ipsum Award winners Natali Vlatko, @jimmysongio, and Dylan Reimerink!
Clear documentation across Kubernetes, HAMi, Cilium, and eBPF makes cloud native software usable for everyone.
#KubeCon #CloudNativeCon
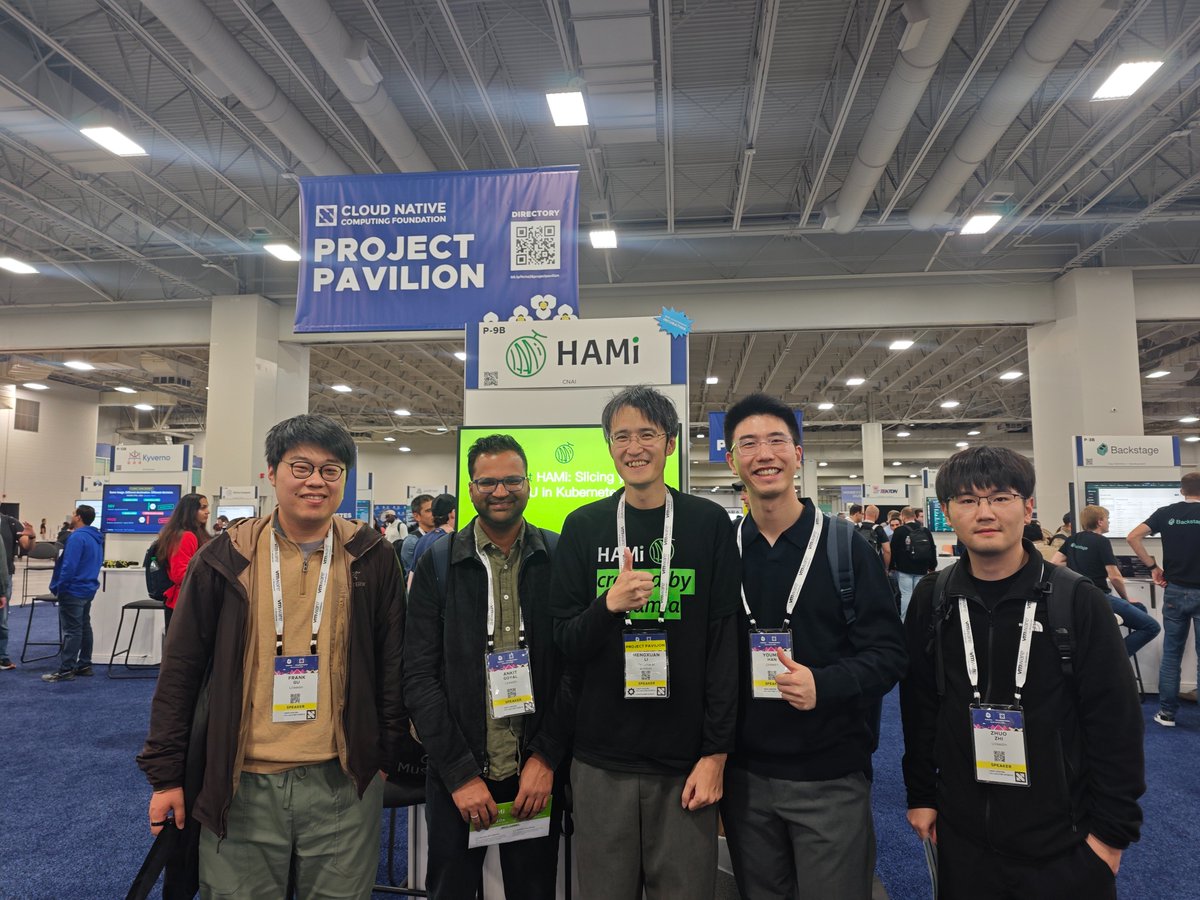
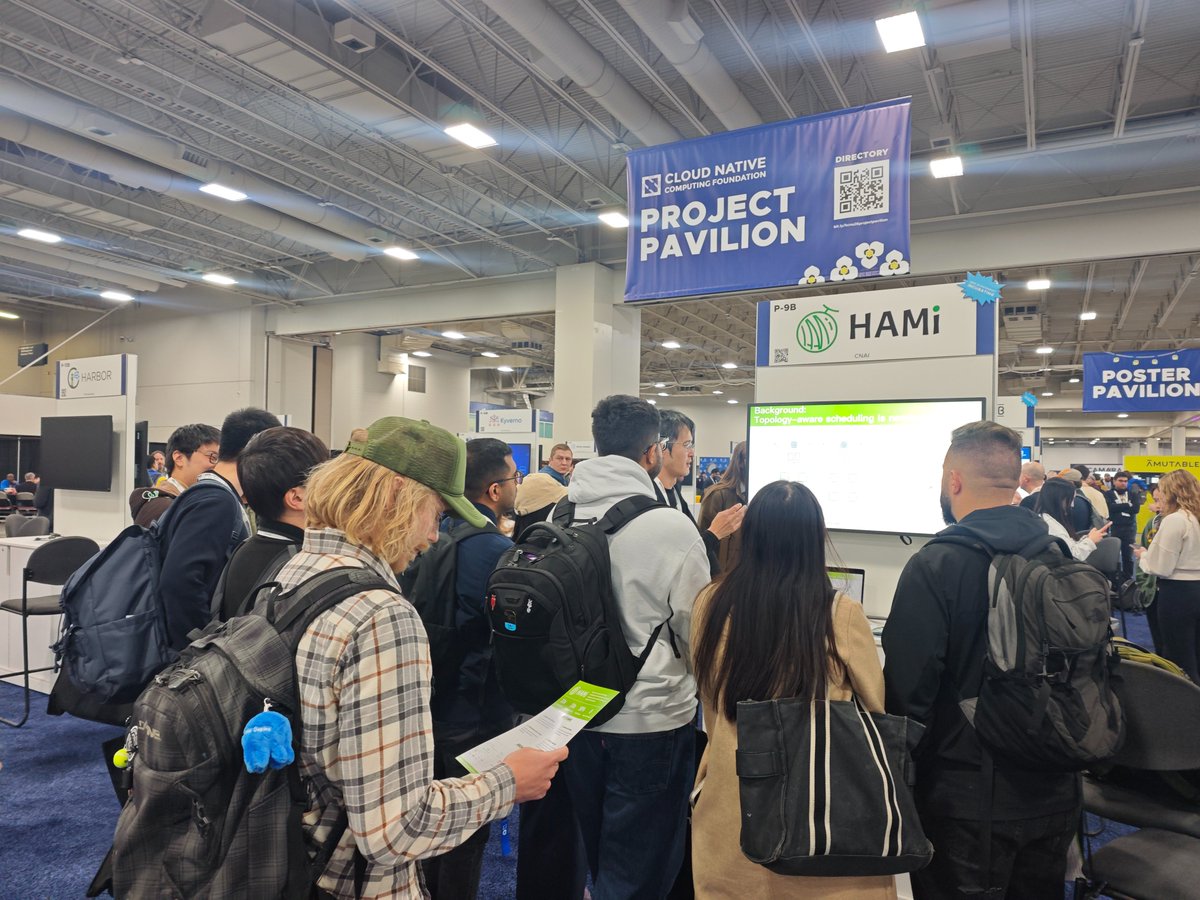
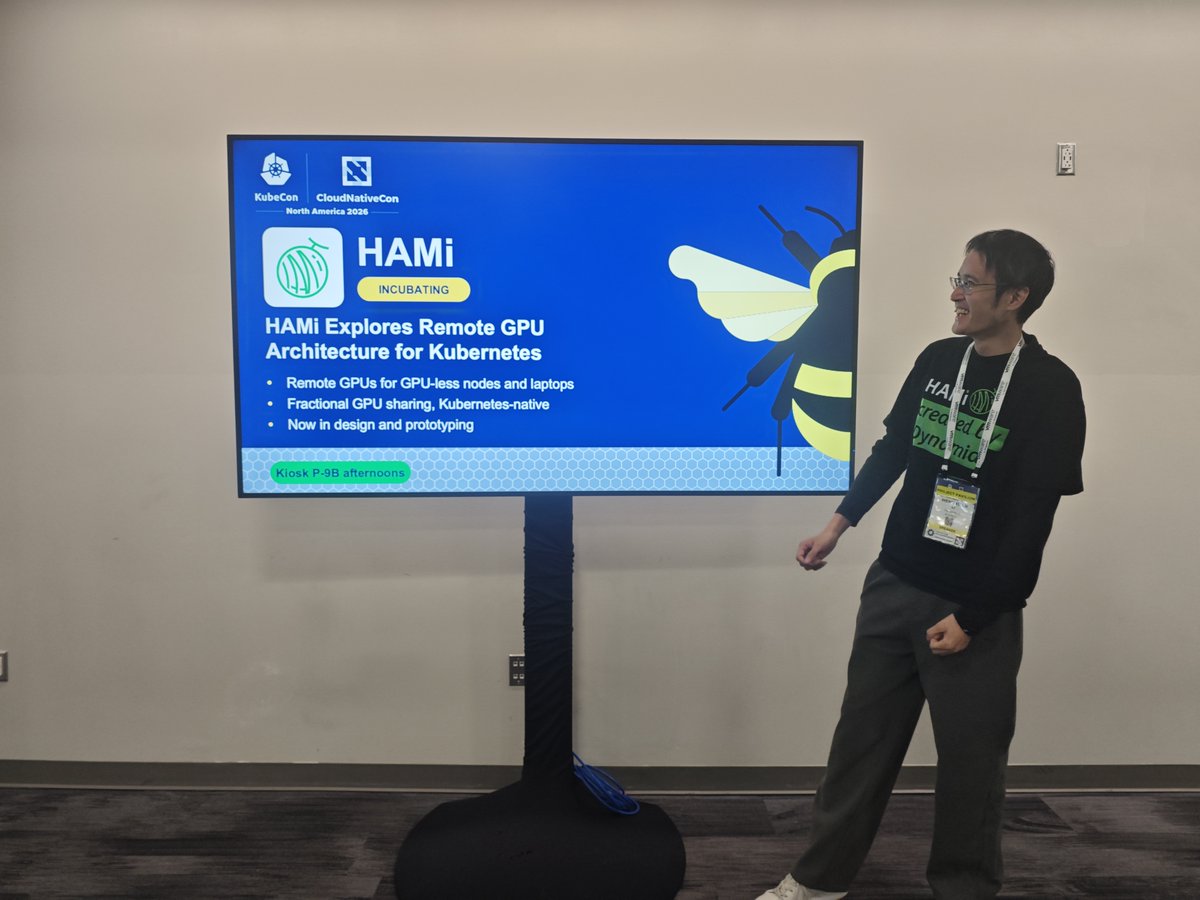
📸 Scenes from #KubeCon NA 2026!
Great conversations, new connections, and lots of interest in GPU sharing and virtualization.
Thanks to everyone who stopped by to connect with the HAMi community! 💚
#HAMi#Kubernetes#OpenSource
HAMi joins the Vultr Open Source Alliance as a founding member!
Together with @Vultr, we're advancing open, efficient GPU infrastructure for AI workloads on Kubernetes.
Excited for what's ahead!
🔗 https://t.co/ppXapb0MTs
#HAMi#OpenSource
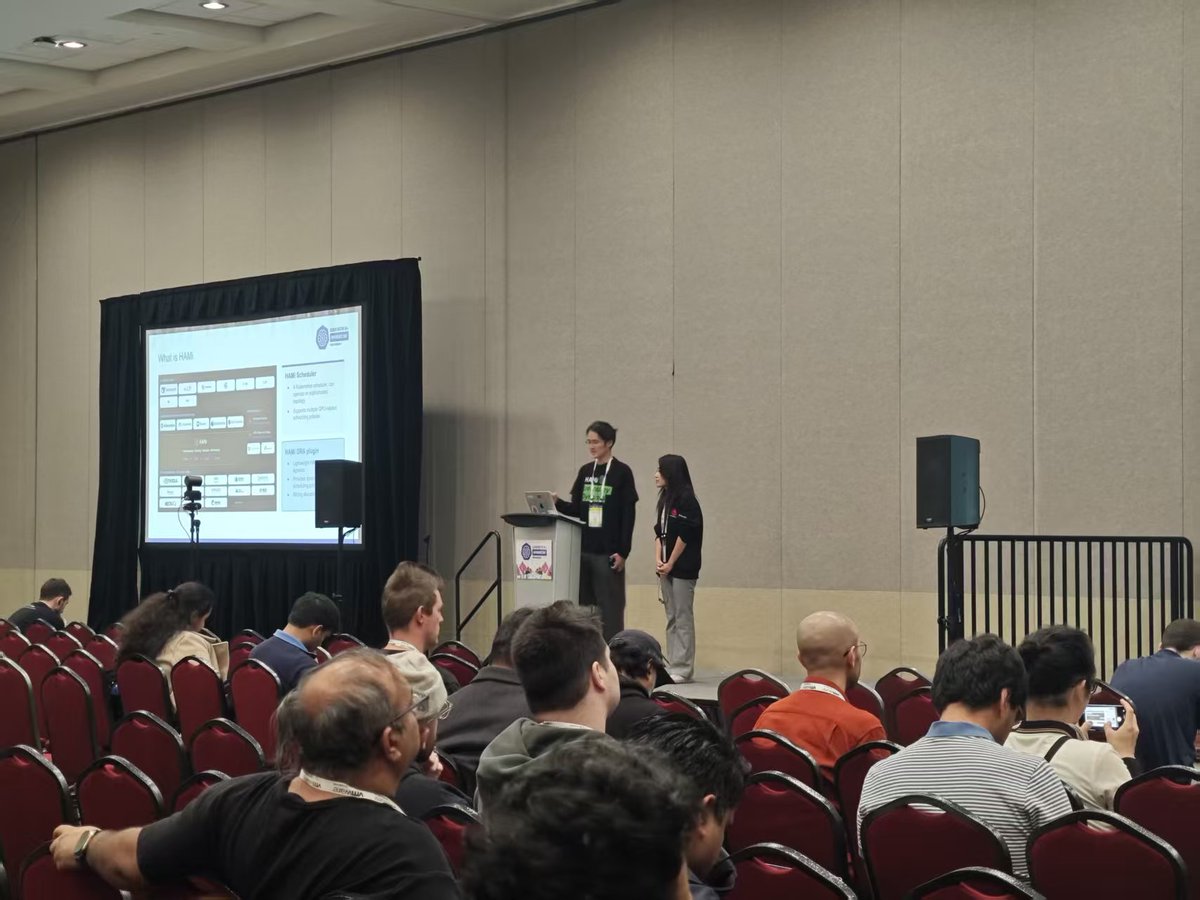
📸 Great day at #KubeCon NA 2026!
Two HAMi sessions in Salt Lake City:
🎤 Maintainer Track — GPU scheduling, hardware support & DRA
🛠️ ContribFest — Hands-on GPU virtualization & device plugins
Thanks to everyone who joined us! 💚
#HAMi#Kubernetes
Live from #KubeCon NA 2026!
Dynamia's Mengxuan Li and Red Hat's Yuchen Fama are showcasing scheduler-agnostic GPU sharing with DRA + Kueue + HAMi + vLLM/llm-d.
From GPU allocation to dynamic slicing and AI inference, all in one architecture.
#HAMi#Kubernetes#GPUSharing
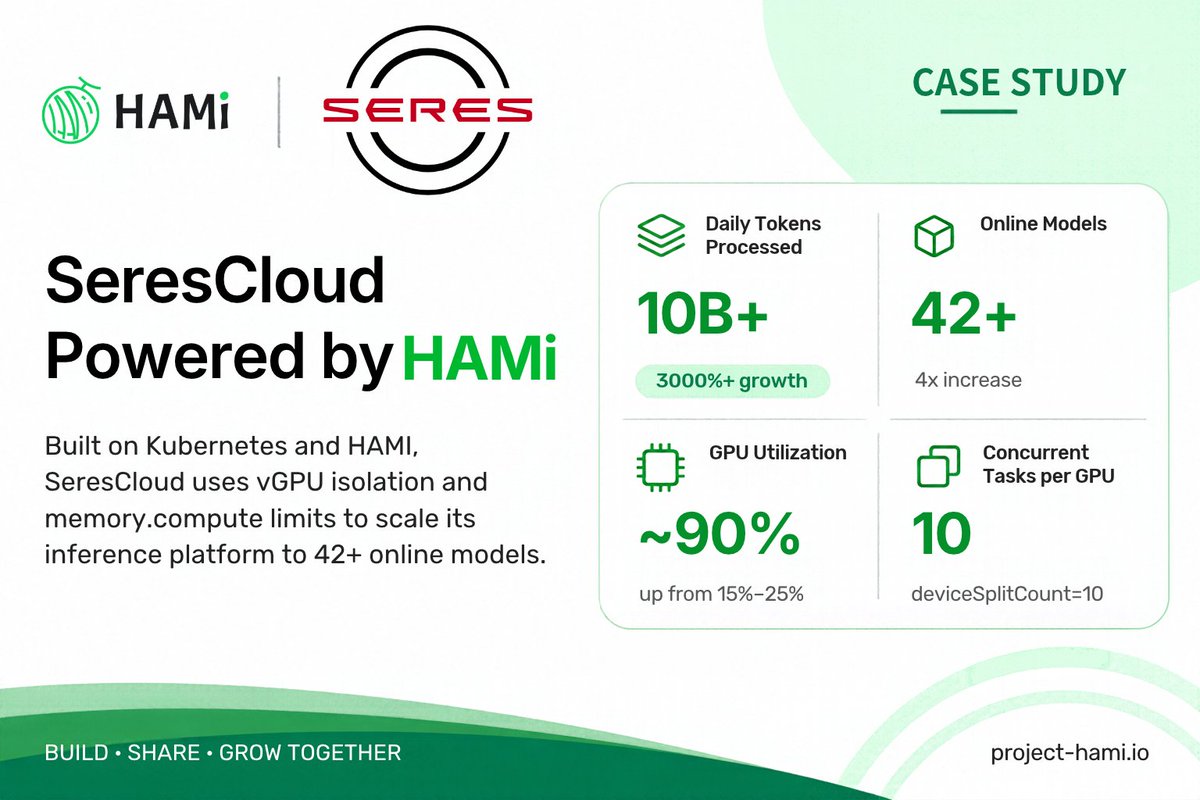
🚀 10B+ daily tokens. ~90% GPU utilization.
In a new @CloudNativeFdn case study, Seres shares how SeresCloud uses Kubernetes + HAMi to scale AI inference with fine-grained GPU sharing and scheduling.
📖 https://t.co/HuuPY6GcOY
#HAMi#Kubernetes#AIInfra
🚀 HAMi is heading to #KubeCon NA 2026!
Join us on Nov 10 in Salt Lake City for two sessions:
🟩 HAMi Levels up: Smarter Scheduling, Wider Hardware Reach and a DRA-Native Lightweight Future
🟩 GPU Virtualization: First Setup and Understanding the Device Plugin / DRA
HAMi is heading to ContainerDays & AI Context Singapore 2026! 🇸🇬
@jimmysongio@fishmanticoder
Join us on Oct 27 :
・12:30 — Hands-on GPU Scheduling in Kubernetes with HAMi
・15:05 — Optimizing Neocloud GPU Utilization with HAMi
Explore GPU sharing & heterogeneous scheduling.
Can HAMi and @Linkerd work together to tackle GPU noisy neighbors? Our community contributor Mesut Oezdil explores GPU isolation, latency-aware load balancing, and tenant security in a hands-on lab. Thanks for the great contribution!
https://t.co/JuHzcIKUYS
Most schedulers check GPU limits only at admission. HAMi checks at admission, then HAMi-core enforces them on every allocation at runtime.
That's why NVIDIA's KAI Scheduler adopted HAMi-core.
Check out my new blog:
https://t.co/tu6i9Tbu88
@HAMiProject@CloudNativeFdn
The best part of the LFX Mentorship is the exposure you get to so many new things.
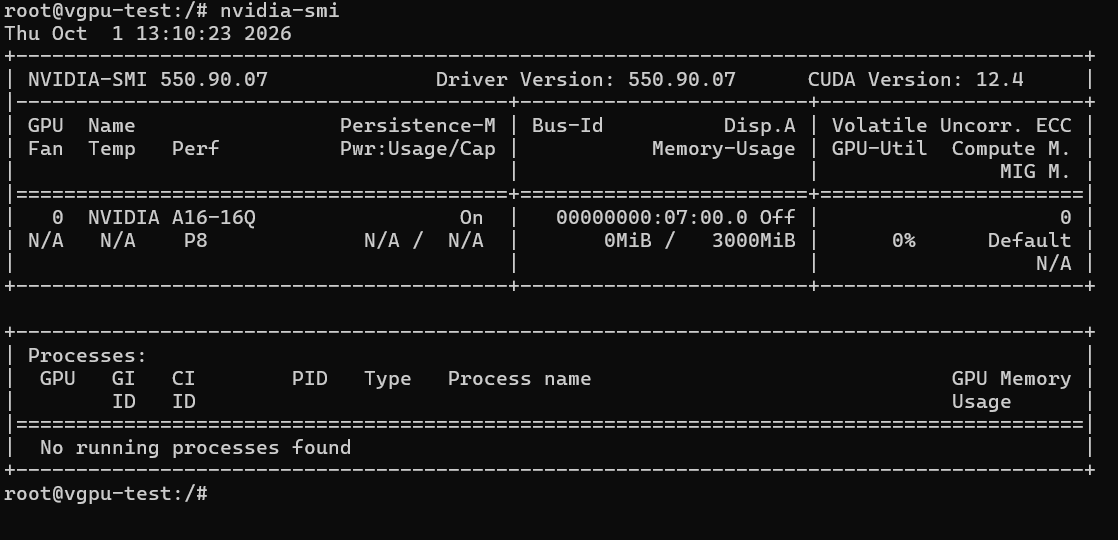
Currently working on @HAMiProject as an LFX mentee, and I got access to an NVIDIA A16-16Q GPU from @Vultr.
Really enjoying the work!😎😎😎
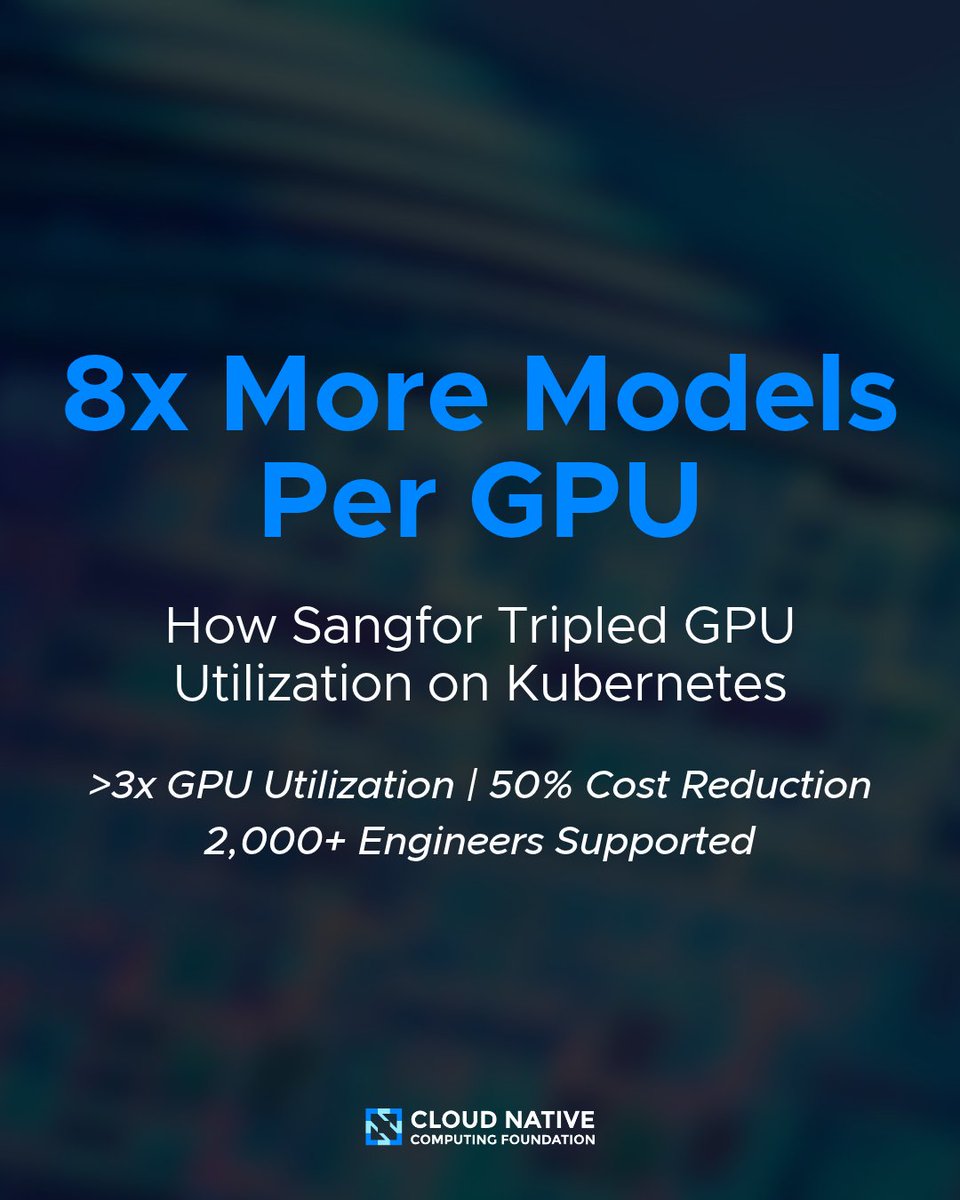
8x more models per GPU without buying a single new card.
That's what fine-grained slicing looks like in production. Congrats to Sangfor on the CNCF case study built on Kubernetes with HAMi + Volcano.
To support 2,000+ engineers running concurrent AI workloads, Sangfor implemented vGPU slicing to run 8x more models per GPU.
By pairing Kubernetes with Volcano and HAMi, they tripled GPU utilization across production.
Read the case study: https://t.co/oiTQZKeHGn