Korea’s Trillion-Dollar Sovereign AI Investment: Nvidia Wins, Hynix Loses
Korea hosts a Squid Games, National AI Tournament,
the best non-Chinese open source model gets eliminated,
why Nvidia needs open source, implications for Hynix and Samsung
https://t.co/E3eiJx4VzN
Motif 3 is officially here.
Today, we’re releasing Motif 3 Base and Motif 3.
Motif 3 Base is our pretrained foundation model, while Motif 3 is built on top of it with post-training using NVIDIA NeMo-RL.
Both models were developed with the support of Korea's Ministry of Science and trained on NVIDIA B200 GPUs.
With Motif 3, we’re taking our first step into the frontier LLM race.
There’s still a long way to go, but we believe we’ve built a model that deserves to be in the race.
We’ve shared the details in our technical report and blog post.
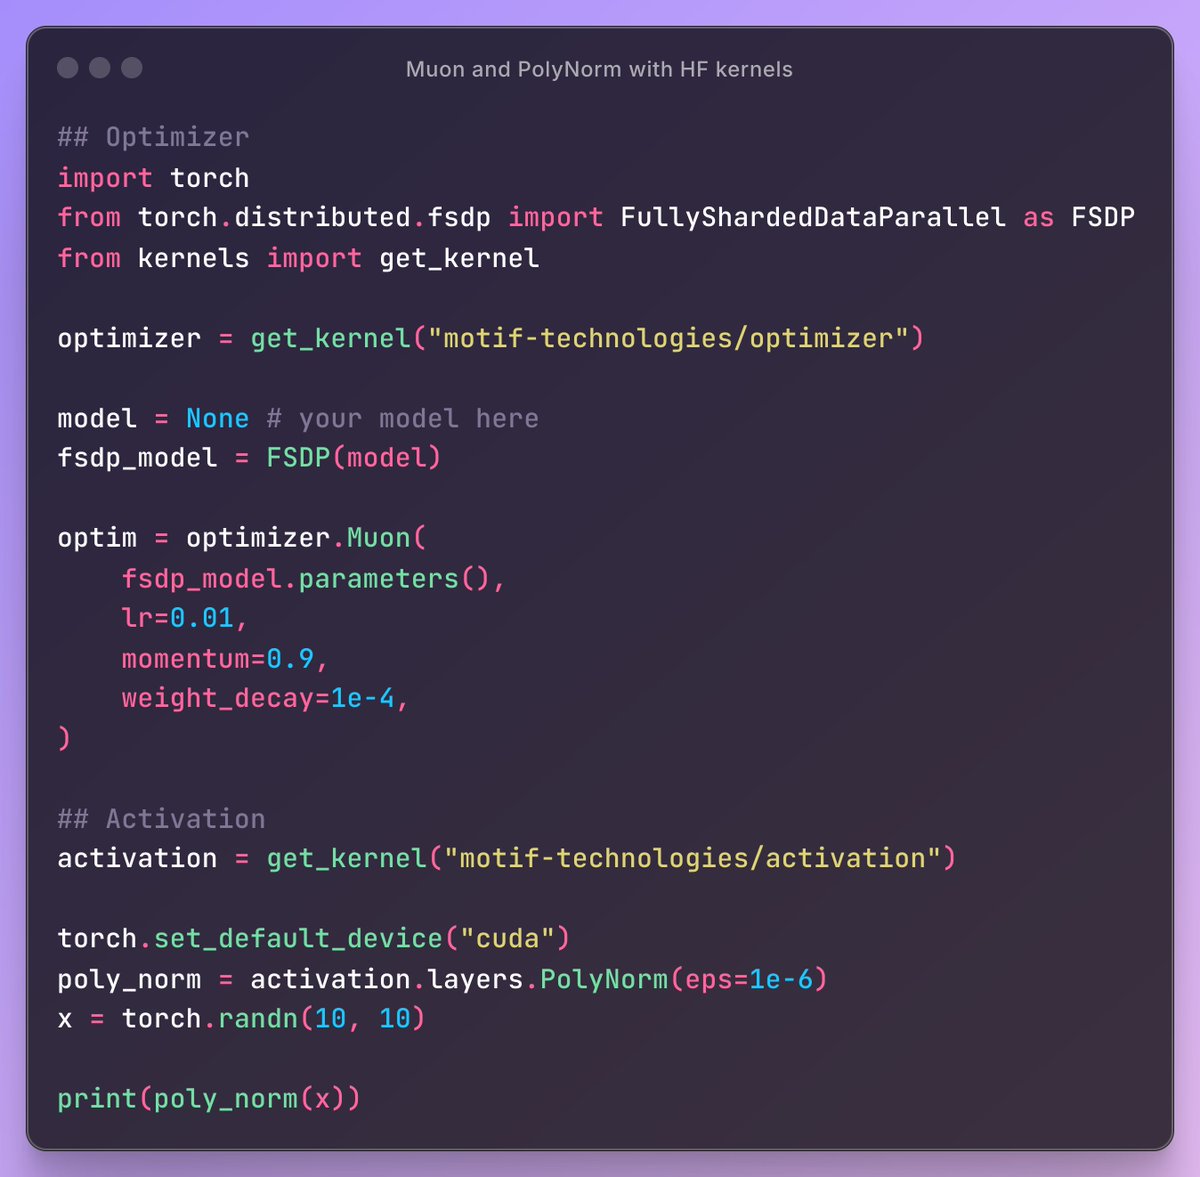
In collaboration with NVIDIA, we’re also releasing an NVFP4 version of Motif 3.
All models will be available on Hugging Face.
Links are in the comments.
Motif Technologies, a 🇰🇷 Korean AI lab, has just launched Motif-2-12.7B-Reasoning, a 12.7B open weights reasoning model that scores 45 on the Artificial Analysis Intelligence Index and is now the leading model from Korea
Key benchmarking takeaways:
➤ Open weights: Motif-2-12.7B-Reasoning is open weights and is a relatively small model at 12.7B parameters. This marks a shift for the Korean model ecosystem, which has historically been more closed relative to Chinese open weights releases
➤ Strengths in Instruction Following and Competition Math: Motif-2-12.7B-Reasoning scores 57% on IFBench and 80% on AIME2025, comparable to Claude 4.5 Haiku in performance in these two benchmarks and highlighting an emerging strength in mathematical reasoning and agentic capabilities
➤ AI activity is accelerating in South Korea: Motif Technologies’ Motif-2-12.7B-Reasoning sets a new high in intelligence for Korean AI labs and is the latest in a string of notable 2025 releases. The model compares favorably with LG Research’s EXAONE 4.0 32B (Intelligence Score: 43) and Upstage’s Solar Pro 2 (Intelligence Score: 38). The country’s pace of innovation continues to quicken, supported by government incentives and a rapidly expanding AI ecosystem
➤ High token usage: The model used the most tokens to run our Artificial Analysis Intelligence Index evaluations at 200M tokens. This has implications for cost and latency
See below for further analysis:
Only 3 countries in the world have shown the ability to develop multiple high-quality LLMs
US, China, and Korea (as a distant third)
France doesn't count, as they only have Mistral
@eliebakouch We’re excited to announce our new model and architecture!
We’d love for you to take a look:
https://t.co/vYcSccERj6
https://t.co/CwghxBnNKn
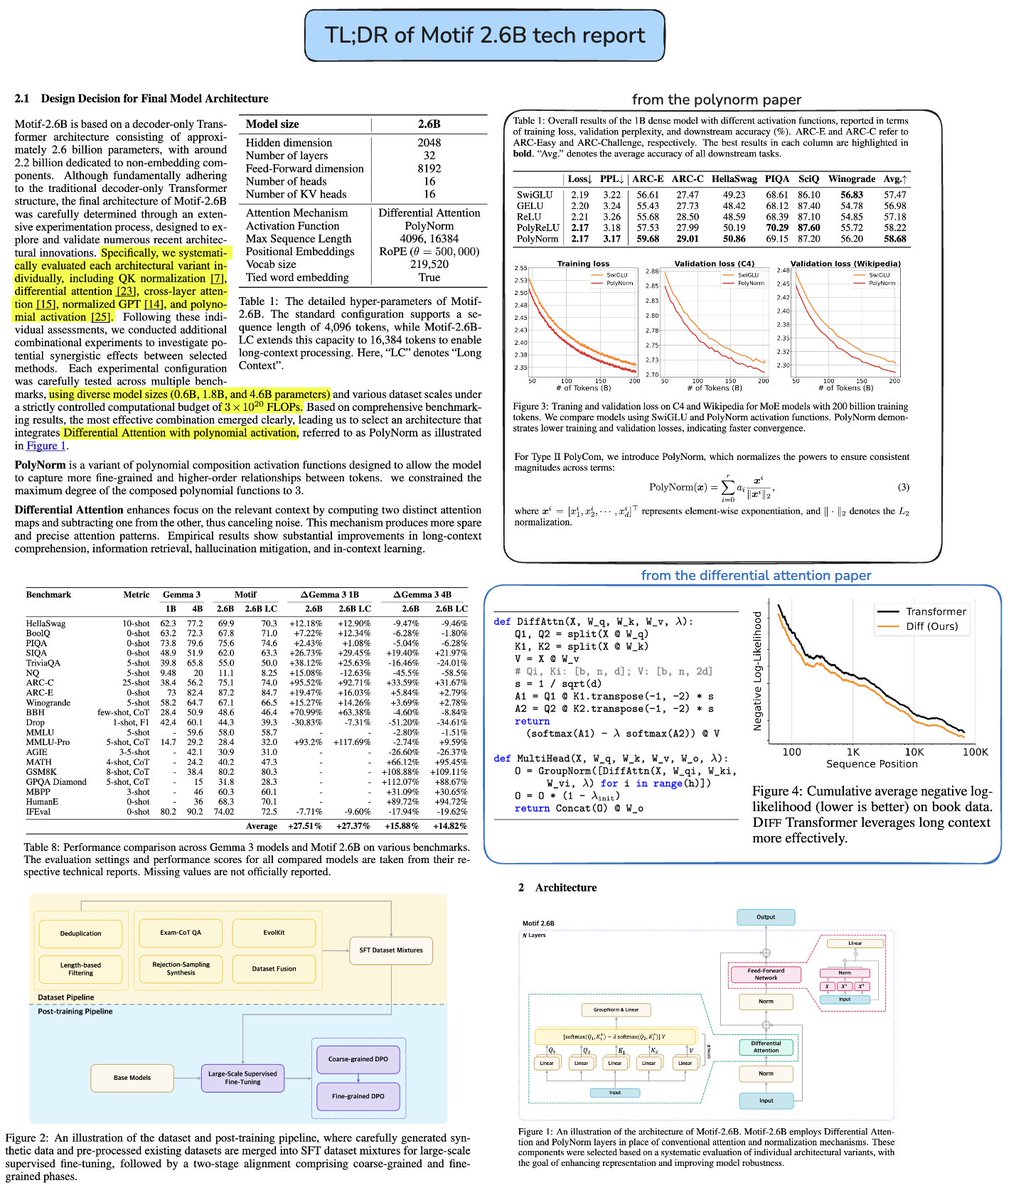
Motif 2.6B tech report is pretty insane, first time i see a model with differential attention and polynorm trained at scale!
> It's trained on 2.5T of token, with a "data mixture schedule" to continuously adjust the mixture over training.
> They use WSD with a "Simple moving average" averaging the last 6 ckpt every 8B token.
> They trained on Finemath, Fineweb2, DCLM, TxT360.
> Lot of details in the finetuning data they used, for instance they used EvolKit and did some "dataset fusion" to have more compressed knowledge into the data.
> They mention they also tried Normalized GPT, QK-Norm and Cross Layer Attention.