Choose life. Choose a train, a statue, a pipe organ. Choose a 1967 Volkswagen Beetle, a K6 red telephone box in London.
We chose not to choose. We reconstructed them all.
Introducing 🚂 📸 Trainspotting: 12,068 objects reconstructed in 3D from 311,886 found photos.
🧵
1/8
Why is AI slop so frustrating to read?
AI writing often obscures main ideas and invents awkward phrases, making sentences more complex than necessary.
Many of these slop patterns violate writing principles established in English writing books.
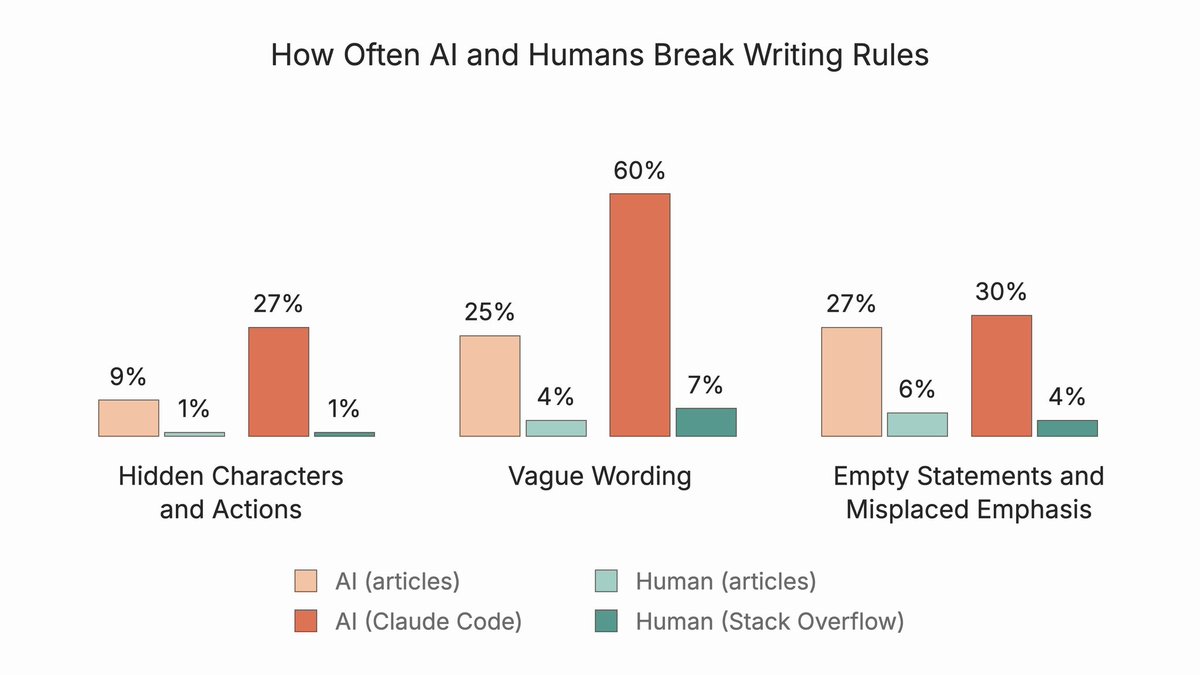
In our benchmark, AI writing breaks these principles far more often than human writing, with Claude Code replies by far the worst offenders.
We show examples of the most common slop patterns in this thread
🚂 📸 Trainspotting: Learning Object-Centric 3D Reconstruction from Found Photos
Joint work with my advisor Noah Snavely (@Jimantha)!
📄 Paper: https://t.co/lPrh2sDhEd
🌐 Project: https://t.co/YSpvHK5rX9
💻 Code & data: https://t.co/4SjyMN5m44
8/8
Choose life. Choose a train, a statue, a pipe organ. Choose a 1967 Volkswagen Beetle, a K6 red telephone box in London.
We chose not to choose. We reconstructed them all.
Introducing 🚂 📸 Trainspotting: 12,068 objects reconstructed in 3D from 311,886 found photos.
🧵
1/8
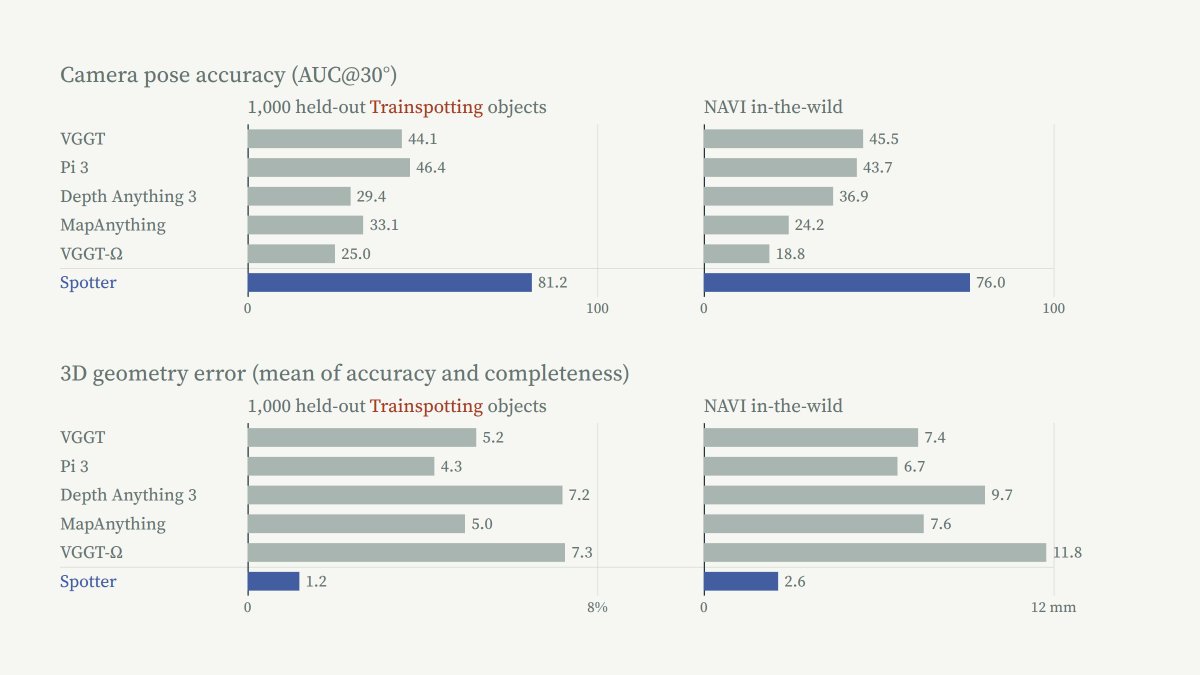
Compared with VGGT-Ω, Spotter improves camera-pose AUC@30 from 25.0 to 81.2 on held-out Trainspotting objects, and from 18.8 to 76.0 on the independent NAVI in-the-wild benchmark 🚀
Performance on conventional benchmarks remains largely unchanged.
7/8
[7/7]
For more interactive visualizations, check out our project page: https://t.co/v6Ps0B2BtR
Huge thanks to the team! Ruojin Cai (@ruojin8), Steve Marschner, and Noah Snavely (@Jimantha).
Come by our poster on Sunday, Poster Session 6, if you’re interested!
Excited to share ArchSym at #CVPR2026! 🏛️
Existing 3D symmetry detectors work well on clean, object-centric data. But what about in the wild?
In our work, we tackle 3D-grounded reflectional symmetry detection specifically for real-world architectural landmarks.
🧵[1/7]
[6/7]
On held-out landmark scenes, our method improves over both Reflect3D (finetuned on our dataset), and a simple baseline that directly regresses plane parameters from the same VGGT features.
See our paper for full quantitative results and evaluation details.
Honey, I Shrunk the Arc de Triomphe! 😱
Ever notice how SOTA depth models suffer from "scale-collapse"—metrically shrinking distant landmarks like they're toys? We introduce MetricScenes: a new in-the-wild metric dataset that fixes this!
Introducing Doppelgangers++! 🚀 An enhanced pairwise image classifier that tackles visual aliasing (doppelgangers) to improve 3D reconstruction accuracy across diverse, real-world scenes. 🌍✨
🔗Project page: https://t.co/R54xWVbUNf. Code is also available.