Can conditional generative models achieve strong visual representations, inherently?
We introduce BiGR, a conditional image generation model that unifies generative and discriminative tasks.
Project: https://t.co/h61iy9pDrH
Paper: https://t.co/qz6QxVyOnW
@kaihan_vis @haozsh
We are delighted to introduce our text-guided video inpainting paper: "CoCoCo: Improving Text-Guided Video Inpainting for Better Consistency, Controllability and Compatibility". All codes and weights are available at at https://t.co/TCWPWLcm2G
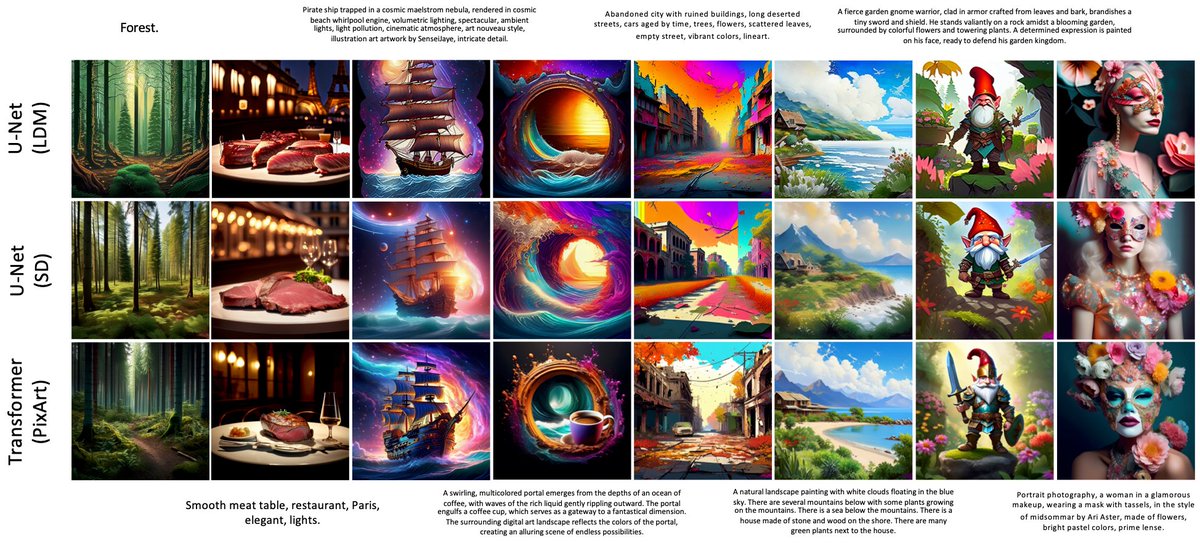
Happy to share that our paper, LaVi-Bridge, has been accepted at #ECCV2024 ! LaVi-Bridge serves as a bridge connecting various language and vision models for text-to-image generation. It is open-sourced and here is the code: https://t.co/VXQUl275mo.
This is our recent work, LaVi-Bridge, which can bridge different language and vision models to conduct text-to-image generation. The topic is promising which has not been well explored. It is open-sourced and here is the code: https://t.co/VXQUl275mo. Here are some results!