This paper is accepted by #NeurIPS26.
The title of this work has been changed to "PORTool: Importance-Aware Policy Optimization with Rewarded Tree for Multi-Tool-Integrated Reasoning". More updates of this work will come shortly.
Paper: https://t.co/Rt21ee8DL6
Excited to share our latest work at Apple: PORTool: Tool-Use LLM Training with Rewarded Tree 🚀
In this work, we reinforce LLMs for multi-step multi-tool use when only the final outcome is available.
Paper: https://t.co/Rt21ee8DL6
#LLM#ToolUse#AIResearch 🧵1/n
new post on harness engineering for AI self-improvement: https://t.co/ZYvGfVs61k
It is hard to forecast how much the future of RSI will rely on harnesses. Likely harness engineering will evolve in the direction of self-improvement and enable auto-research, and, in turn, smarter models keeps harnesses simple.
Even when many harness improvement get eventually internalized into core model, the need to specify goals and context will not disappear.
Excited to attend #ACL at #SanDiego from July 5-7 and serve as a virtual session chair on July 6.
I'm looking for meeting old friends and connecting new friends in NLP/ML community.
Feel free to DM me (or like the post) if you are nearby. Let's grab a coffee and chat!
Excited to start my first day as an intern at @MSFTResearch New England office, @MSRNE!
Let's connect and meet up in person if you are around #Boston, #MIT, #Harvard, or #NEU. I'm looking forward to learning more about the frontiers of GenAI and LLMs.
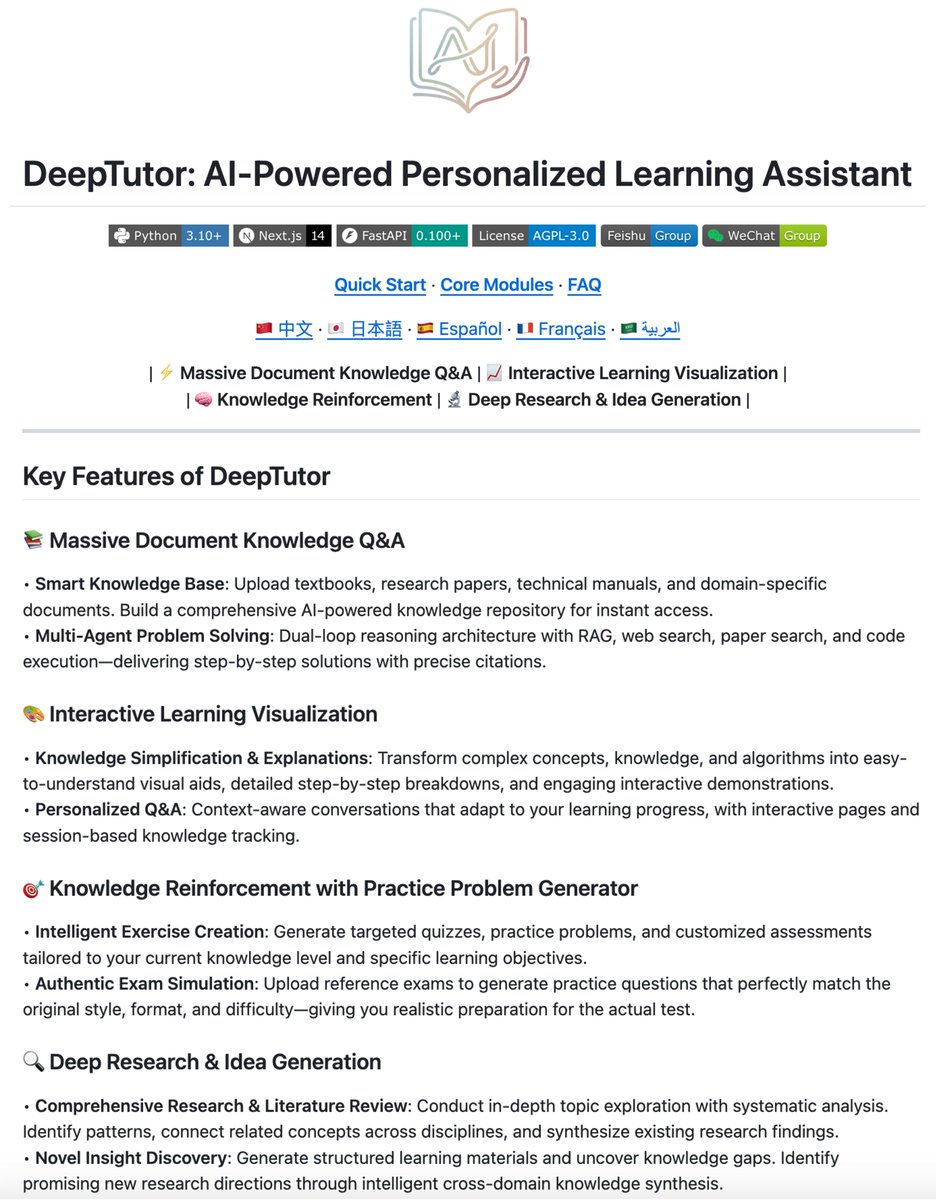
🚀 Our lab just open-sourced DeepTutor - AI-Powered Personalized Learning Assistant
We're actively exploring how agentic AI can assist students and researchers throughout their learning process. DeepTutor brings together research, problem-solving, practice generation, and knowledge management into one system that actually understands your learning context.
🔗 Open Source: https://t.co/Wd8odKIRSn
Core Features of DeepTutor:
- 📚 Smart Document Q&A - Throw in your textbooks, papers, and technical docs. Get detailed answers with proper citations when you ask questions.
- 🎨 Knowledge Visualization & Explanation - Turns complicated concepts into clear visuals and interactive pages that match your learning pace.
- 🎯 Practice Question Generator - Creates quizzes based on your material, and can even mimic the style of real exams you upload.
- 🔬 Deep Research & Idea Generation - Helps with academic research, report writing, and brainstorming. Can handle multiple research topics simultaneously.
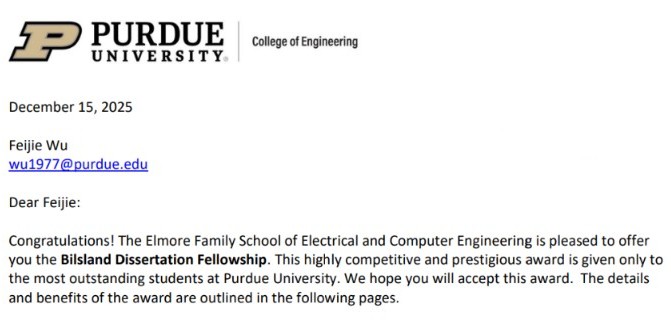
Honored to be awarded the Bilsland Dissertation Fellowship from @PurdueEngineers, which will generously support my final year of PhD study. Grateful to @PurdueECE for the nomination and for recognizing my research achievements.
✈️ I will be at #neurips2025 during Dec 2~5. Look forward to coffee chat ☕ with anyone working on multi-agent systems, tool-use LLMs, federated learning, and any other interesting topics.
I'm actively looking for next summer internship. Open to any available opportunities.
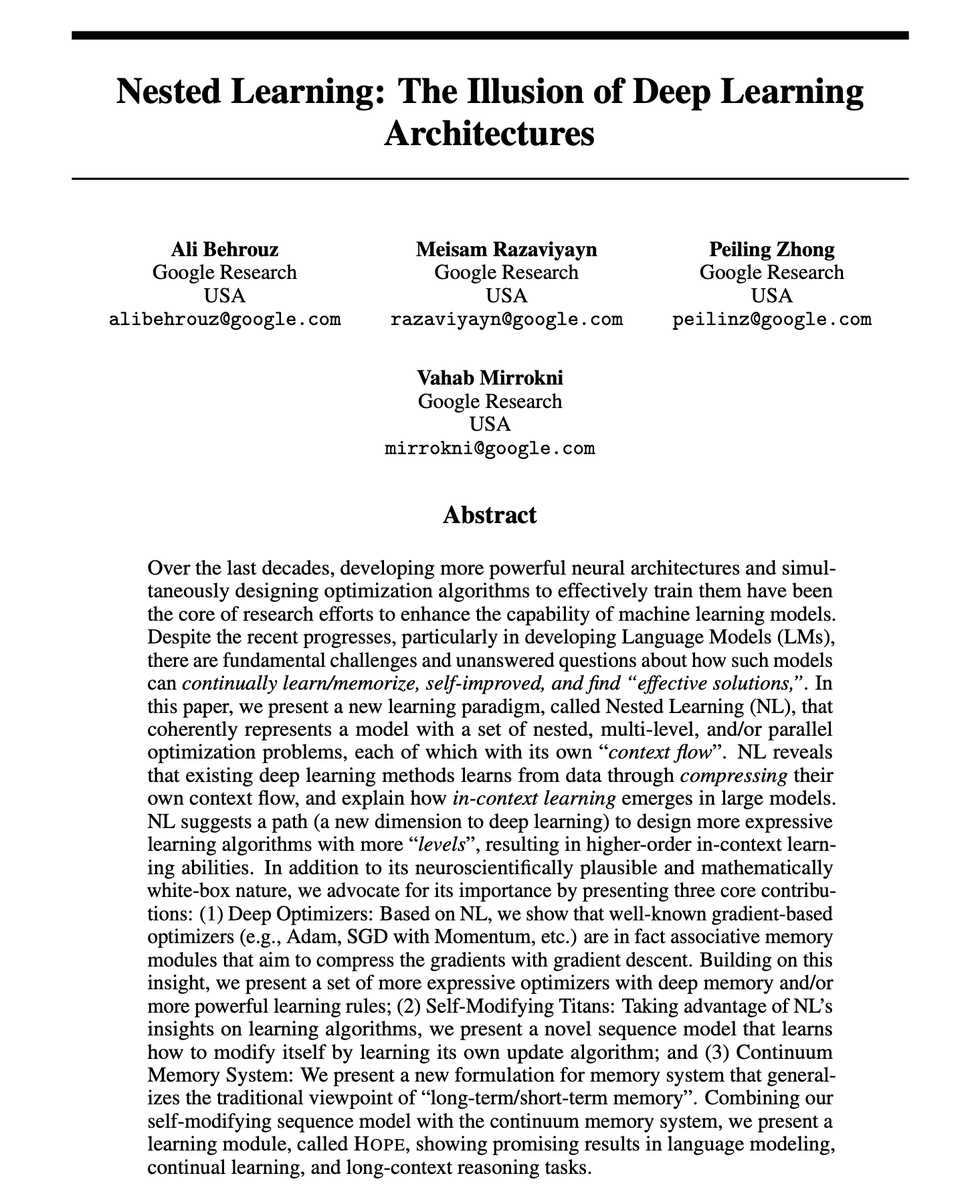
Google just dropped "Attention is all you need (V2)"
This paper could solve AI's biggest problem:
Catastrophic forgetting.
When AI models learn something new, they tend to forget what they previously learned. Humans don't work this way, and now Google Research has a solution.
Nested Learning.
This is a new machine learning paradigm that treats models as a system of interconnected optimization problems running at different speeds - just like how our brain processes information.
Here's why this matters:
LLMs don't learn from experiences; they remain limited to what they learned during training. They can't learn or improve over time without losing previous knowledge.
Nested Learning changes this by viewing the model's architecture and training algorithm as the same thing - just different "levels" of optimization.
The paper introduces Hope, a proof-of-concept architecture that demonstrates this approach:
↳ Hope outperforms modern recurrent models on language modeling tasks
↳ It handles long-context memory better than state-of-the-art models
↳ It achieves this through "continuum memory systems" that update at different frequencies
This is similar to how our brain manages short-term and long-term memory simultaneously.
We might finally be closing the gap between AI and the human brain's ability to continually learn.
I've shared link to the paper in the next tweet!
Three takeaways 🧪
• γ matters: it affects final rewards and the number of tool-call steps
• Advantage coefficients: adding a GRPO-style term based on fork-relative adv. yields notable gains
• Reward design works: our design for step-wise reward outperforms alternatives
🧵8/n
Excited to share our latest work at Apple: PORTool: Tool-Use LLM Training with Rewarded Tree 🚀
In this work, we reinforce LLMs for multi-step multi-tool use when only the final outcome is available.
Paper: https://t.co/Rt21ee8DL6
#LLM#ToolUse#AIResearch 🧵1/n
Results 📈
Across diverse backbones, PORTool delivers the best overall performance vs. strong RL baselines—higher accuracy, fewer tool-call steps, lower unanswerable rate, and higher formatting reward.
🧵7/n
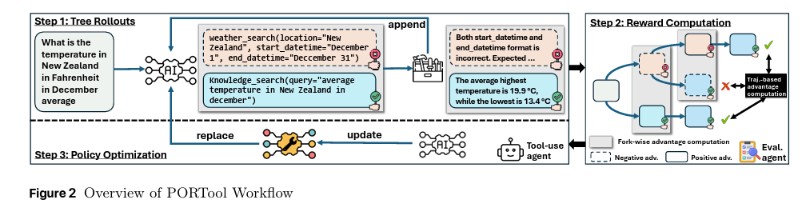
Step 3: Policy Optimization ⚖️
We compute two complementary advantages:
• Trajectory-relative advantage (whole-path signal)
• Fork-relative advantage (credit per branching step)
These are combined to update the policy so the LLM learns effective trajectories and steps
🧵6/n
Step 1: Tree Rollouts 🌳
PORTool lets the LLM branch its tool calls, generating a tree of trajectories for each query.
This encourages exploration beyond a human-labelled routine, capturing recoveries from failures (wrong tool, bad params) and surfacing better paths.
🧵4/n
PORTool in three steps 🌳🎯🛠️ to avoid human-labeled traces and estimate step rewards from outcomes:
1. Tree Rollouts
2. Reward Computation
3. Policy Optimization
🧵3/n
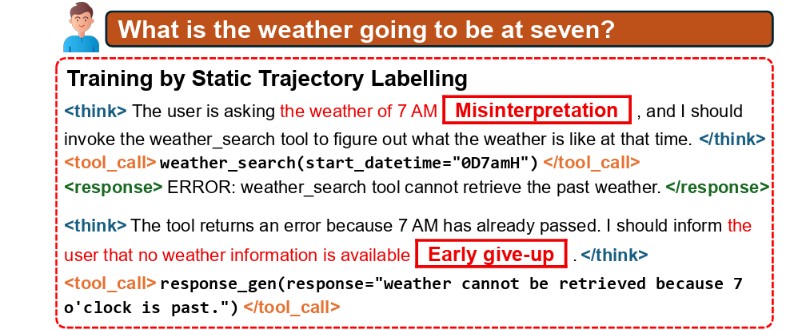
What's wrong with current setups? 🤔
(i) Train on static multi-step trajectories → models imitate but struggle with unexpected cases (e.g., tool-call failures)
(ii) Use identical rewards for all steps in a trajectory → the model can't learn which steps matter
🧵2/n
COLM is going to San Francisco for 2026!
🗓️Dates: October 6-9, 2026
🏨Venue: Hilton San Francisco Union Square
Website and CFPs for papers and workshops coming up soon!