

Top Tweets for #DataExtraction

Messy charity application PDFs, turned into clean, validated data. Zylitix’s AI and OCR cut manual processing by 72%. See how: https://t.co/SdZ57nWtcH
#AIAutomation #OCR #DocumentAutomation #Zylitix #HealthcareTech #IntelligentDocumentProcessing #DataExtraction #HospitalOperation

36M SKUs. 18M images. 450+ retailers. One AI-powered solution.
Fashion data comes in millions of formats, descriptions and images. Making sense of it all, every single day, is no small task. https://t.co/AML02GUzu1
#AIInRetail #FashionTech #VisionLanguageModels #DataExtraction


Resumes come in different formats. Digital Resume Parser extracts relevant information from diverse resume templates to support consistent data processing
https://t.co/wfp1ujaikn
#DigitalResumeParser #DRP #ResumeParsing #ResumeFormats #DataExtraction

Link Insertion – FlareSolverr.com (Web Scraping) dlvr.it/TWF44l #WebScraping #DataExtraction #OpenSource #FlareSolverr #Cloudflare


🛒 Automate e-commerce insights with AliExpress API integration!
Collect product details, pricing, seller information, and availability to track competitors and discover market opportunities.
#AliExpressAPI #EcommerceData #DataExtraction #RealDataAPI


📊 Transform raw data into business value.
Extract, analyze, and organize valuable information with data extraction and processing services from Data Entry India BPO. Turn complex data into actionable business insights. 📈
#DataExtraction #DataProcessing #BusinessIntelligence

Unlock media insights with Tencent Video API! Extract available video metadata to support content research, video analytics, and media market intelligence.
#TencentVideo #VideoMetadata #DataExtraction #RealDataAPI

Extract data behind a login. 🔐
BrowserAct gives your Bot three ways to sign in: saved credentials, cookies, or manual login. Reuse the session on later runs with Standard Browser.
👉https://t.co/ehhZEJMXdi
#BrowserAct #WebScraping #DataExtraction

🚀 https://t.co/FhdlBSsovq by @stewartcelani just launched on @appstackbuilder — Bulk extraction of images, text, audio, and metadata from documents and media. https://t.co/AI4ZQjRWCo
#ExtractFAST #DataExtraction #DocumentProcessing #BatchProcessing #OCR #DeveloperTools #ProductivityTools #ProductLaunch

No way, a spider is crawling the web and turning pages into clean Markdown 🕷️
Okay, it's Spicrawl!
Scrape web pages, crawl URLs, and get clean data for the projects you're building.
Less scraper maintenance. More building.
#WebScraping #WebScrapingAPI #DataExtraction

Audit-Ready, On Demand: How DocReveal Turns Any Set of Documents into the Export You Need
https://t.co/d6MeK1C3jk
#DocReveal #DocumentAutomation #DataExtraction #NoCode #MCP

What does the future of web access look like?
In our latest article with @ScrapingAnt, we explore what’s changing in fingerprinting, detection, and data extraction.
#DataExtraction #Proxies #BotDetection #WebScraping https://t.co/wZxLzB8quR

#HancomWith #MDSeries
A complete mobile & #DigitalForensics ecosystem for #DataExtraction, recovery, analysis, cloud evidence, video forensics, JTAG and chip-off investigations.
Explore #MDNEXT, #MDRED, #MDLIVE, #MDCLOUD, #MDVIDEO and advanced forensic hardware solutions.

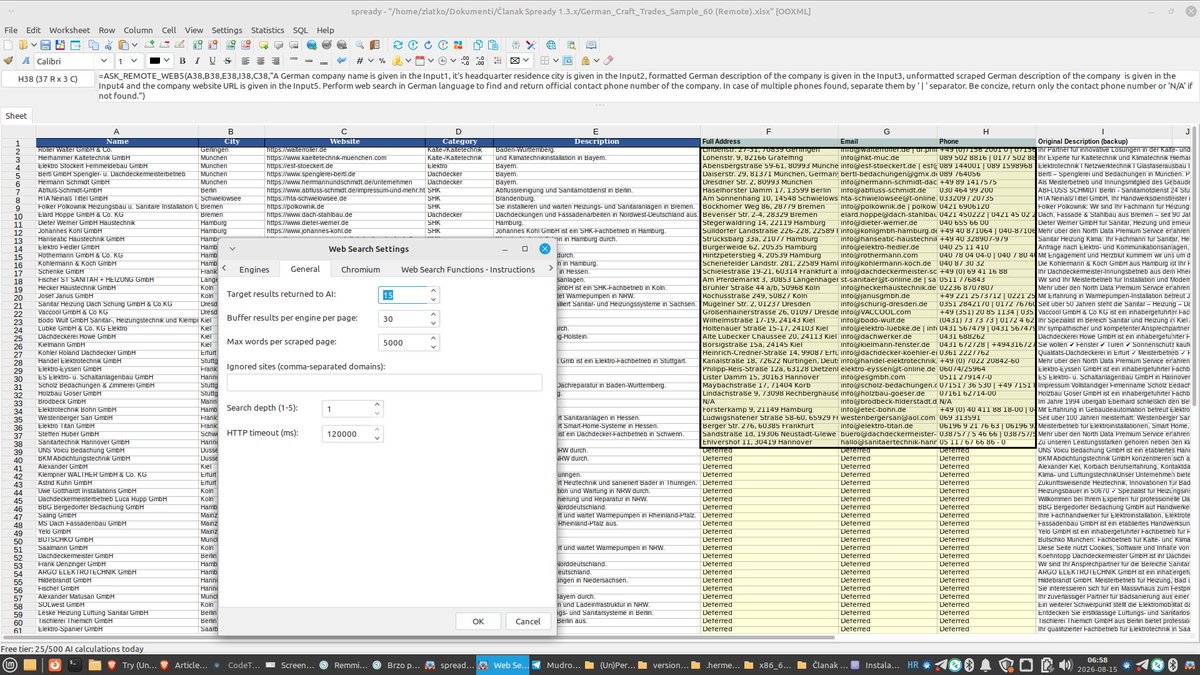
📊 Lead gen on autopilot: company name in, address + email + phone out. That's =ASK_REMOTE_WEB5 at work — and you get 500 AI formulas/day free: https://t.co/RNFW26c77j #DataExtraction #Automation #AIformulas #AI

🔥This AI can turn websites into data your business can actually use.What if you could turn a messy web page into clean, structured data without writing fragile parsers? That’s what Zyte’s AI Extraction does.
#Review #Zyte #AI #WebScraping #AIWebScraping #DataExtraction #AItools

Most platforms charge for “what if.” We charge for actual usage. → https://t.co/rxwwIDpgcO #PayOnlyForWhatYouProcess #AiCR #DocumentAutomation #DataExtraction #FinancialServices#MortgageTechnology

https://t.co/1dehjACV9n
⚡ https://t.co/1dehjACV9n is available. Perfect for AI data extraction, OCR & automation solutions.
DM for pricing.
#AI #ArtificialIntelligence #DataExtraction #Automation #DomainForSale #Startup #Domains


Le scraping web entre dans l’ère de l’auto-correction 🌐
Combien d’heures vos équipes growth ont-elles perdues cette semaine à réparer un scraper cassé à cause d’un simple changement de code CSS ?
#KingLand #IA #WebScraping #GrowthHacking #NoCode #RevOps #DataExtraction #Make #Automation #Productivity #BusinessIntelligence #SaaS #TechTrends
▫️ Fiche Impact : https://t.co/8OQyLqM5Rp
Parce qu’avec Browse AI, un flux de données autonome et résilient vaut mieux qu’un script obsolète dès la prochaine mise à jour du site cible.
L’acquisition de données externes est essentielle pour rester compétitif, mais la fragilité des scrapers traditionnels a toujours été un goulet d’embouteillage pour les équipes RevOps. La donne change radicalement en juillet 2026. Avec le déploiement de sa nouvelle documentation d’intégration sur l’orchestrateur @make_hq et sa technologie brevetée de self-healing, @BrowseAI transforme l’extraction de données en un actif d’acquisition totalement autonome. Plus besoin de coder ou de surveiller constamment les modifications de design des sites concurrents.
🔄 Technologie self-healing : L’algorithme calcule un score de sémantique et de position pour relocaliser les données automatiquement si le site cible change sa mise en page.
🔌 Intégration Make optimisée : Le transfert de données structurées et de flux de prospects vers vos CRM ou Airtable se fait désormais en temps réel sans script intermédiaire.
🖱️ Enregistreur point-and-click : Une simple extension Chrome suffit pour entraîner un robot virtuel en mimant le comportement humain, contournant ainsi les blocages standards.
📊 Flexibilité budgétaire : Un modèle freemium intelligent qui permet de démarrer à moindres frais avant de passer à l’échelle sur des volumes industriels.
"Le scraping n’est plus une affaire de développeurs, mais une commodité opérationnelle gérée de bout en bout. La véritable valeur ne réside plus dans la capacité technique à extraire l’information, mais dans l’intelligence de son exploitation directe au sein de vos systèmes décisionnels."
— C. Pestel
Au travers de l’évolution de ces technologies, je décèle un basculement fascinant. Nous construisons des robots de plus en plus sophistiqués pour lire le web à notre place, pendant que les sites renforcent leurs barrières pour prouver notre humanité. C’est un jeu du chat et de la souris infini. Mon intuition est que l’avenir appartient à ceux qui sauront intégrer ces flux de manière invisible et stratégique, sans sur-automatiser à l’excès. L’outil devient transparent, seule l’intention business demeure.
Comment imaginez-vous exploiter ces données de veille si la barrière technique du scraping disparaissait définitivement pour vos équipes ?


Craigslist actively blocks scrapers and has no public API. Getting reliable data from it means using the right tools and proxy setup.
https://t.co/PYqs2kqBaQ
#WebScraping #DataExtraction


🕸️⚡🧠 webclaw | Extracción web local-first para LLMs y RAG
Rust puro. De URL a Markdown/JSON limpio en segundos.
CLI + REST API + MCP server. Sin ruido de HTML.
#webclaw #rust #llm #rag #dataextraction #webscraping #opensource #ai #mcp

Trends for you
Most Popular Users

Elon Musk 
@elonmusk
241.4M followers

Barack Obama
@barackobama
118.8M followers

Cristiano Ronaldo
@cristiano
114.5M followers

Donald J. Trump
@realdonaldtrump
111.9M followers

Narendra Modi
@narendramodi
107M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.3M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.4M followers

Kim Kardashian
@kimkardashian
70.8M followers

YouTube
@youtube
68.7M followers

Neymar Jr
@neymarjr
66.4M followers

Bill Gates
@billgates
65.2M followers

Selena Gomez
@selenagomez
63.1M followers

The Ellen Show
@theellenshow
62.2M followers

CNN
@cnn
61.7M followers

X
@x
60.7M followers