

Top Tweets for #GPUcomputing

Ready for large-scale AI training and inference? HPE Compute XD700, built on NVIDIA HGX Rubin NVL8, packs up to 72 Rubin GPUs into a single rack to support demanding AI workloads. #HPE #AI #NVIDIA #GPUComputing #WeAreHPE https://t.co/d5nCsSkLXY

Lium is generating over $5,000 in revenue per hour, and almost nobody is paying attention.
#LIUM #Bittensor #TAO #DeAI #DecentralizedAI #GPUComputing #AIInfrastructure #Crypto

We have nearly doubled our supply since 1 month ago.
Now hosting ~$50m in hardware, 481 B300s, and over 25 different GPU types available now to rent.
check us out for all your GPU needs.

Blockchain Loyalty Corp. ( $BBLC: OTC) is building a broader digital infrastructure strategy through its developing technology divisions.
VISIT NOW
https://t.co/xtj0eWC2tj
#GPUComputing #MarketIntelligence #TechnologyDevelopment #AIPlatforms #OTCMarkets
$BBLC $GPU $AI $TECH

IIFCL ties Yotta loan to promoter buying Nvidia chips
https://t.co/mJMvYkXPWt
#Yotta #YottaDataServices #DataCenters #DataCentreInfrastructure #AIInfrastructure #ArtificialIntelligence #NVIDIA #GPUComputing #DigitalInfrastructure #InfrastructureFinance #ProjectFinance


Apparently GPU scalping is the new AI business model. 😂
I normally rent NVIDIA GB10 compute for $0.38–$0.46 per hour.
Tonight?
$0.613/hr.
$0.673/hr.
And some ambitious motherfucker wants $1.315/hr.
PLUS BANDWIDTH.
#NVIDIA #GB10 #AIEngineering #GPUComputing


بـ 4 خطوات بس، اربط جهازك واربح مع
LLMTune:1️⃣ ادخل:
https://t.co/nsTVJODNny 2️⃣
اضغط Connect a machine
3️⃣ سمّ جهازك واختر نظامه
4️⃣ انسخ الكود وشغّله بالـ Terminal
وبس! جهازك جاهز ويدعم الشبكة.
خلّ عتادك يشتغل لك!
#LLMTune #DeAI #DePIN #GPUComputing

🚀 Just 4 steps to get your machine connected and start earning with LLMTune!
🔗 Visit https://t.co/Xis8konGIB
1️⃣ Click "Connect a machine"
2️⃣ Name your device
3️⃣ Select its OS
4️⃣ Copy the provided script and run it in your terminal.
That's it! Your machine is connected and ready to contribute to the network.
Put your hardware to work. 💻
Building true DeAI & DePIN technology for humans. 🌍
#LLMTune #DeAI #DePIN #GPUComputing #ArtificialIntelligence


CoreWeave Moves Beyond GPUs with New Database Service
https://t.co/xHyK4ZGJub
#CoreWeave #DatabaseService #TechInnovation #CloudComputing #DataManagement #GPUComputing #TechNews #DatabaseSolutions #CloudServices


What should you consider before running an AI workload?
Explore the platform: https://t.co/qpX0W4mlfg
#GPUComputing #WorkloadOrchestration


One cloud. Four powerful solutions. 💻⚡
Cloud VPS, AI-ready GPU, Dedicated & Reseller servers—Navo Cloud powers every stage of your business growth.
🔗 Get started: https://t.co/gF2qfZOZgZ
#NavoCloud #CloudVPS #GPUComputing #TechInfrastructure #ServerSolutions

AICPLIGHT helped a UK university achieve:
✅ 90%+ GPU utilization
✅ 70% faster AI environment deployment
✅ 100+ GPUs under unified management
✅ Support for thousands of concurrent users
Discover the solution:
https://t.co/twNnPbKMIP
#AIInfrastructure #GPUComputing


Wireless engineers: Register for our Nov 12 webinar to explore how to speed up simulation and execution of your wireless communications systems using GPUs, including AI-RAN applications. 📡
Register today 🔗 https://t.co/db5wlgx6Hk
#AIRAN #Wireless #GPUComputing
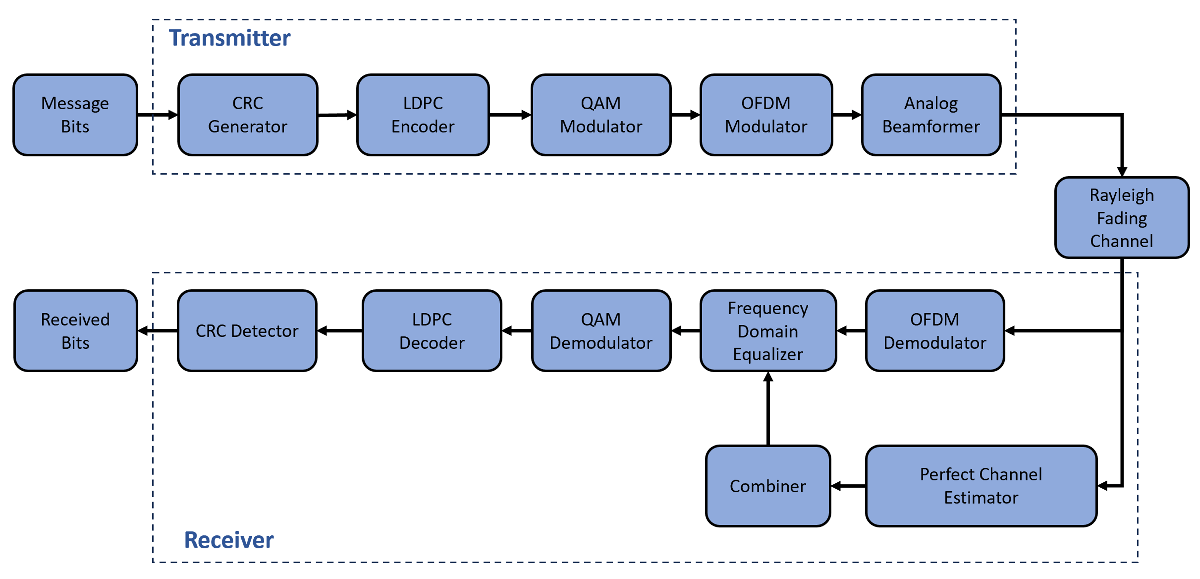

Wireless engineers: Join us on Nov 12 to learn how to speed up simulation and execution of your wireless communications systems using GPUs, including AI-RAN applications. 📡
Learn more and register today: https://t.co/7P9wHfQ72L
#AIRAN #Wireless #GPUComputing

Wireless engineers: Register for our Nov 12 webinar to explore how to speed up simulation and execution of your wireless communications systems using GPUs, including AI-RAN applications. 📡
Register today 🔗 https://t.co/Xs6llz4Y3i
#AIRAN #Wireless #GPUComputing


🏆 24 hours. 34 #1 kernel rankings.
RiSE, Leadde’s GPU kernel optimization system, ranked first on 34 tasks in a 24-hour NVIDIA SOL-ExecBench optimization round.
Real hardware feedback. Continuous optimization. 🚀
#RiSE #GPUComputing #AIInfrastructure

In his latest Substack, “GPUs Don't Take Turns,” CloudLogics' James Williams uses a simple analogy: CPUs are buses. GPUs are Ubers.
Read the full article: https://t.co/gOR7lulKQY
#GPUComputing #GPUScheduling

NSE Deploys Liquid Cooling for AI Infrastructure, Targets 224 GPUs
Read More: https://t.co/yAZCeIe8b7
#NSE #LiquidCooling #AIInfrastructure #GPUComputing #DataCenterTechnology #ArtificialIntelligence


MLOps Engineer, LLM Performance (Kernels, Profiling, Serving) Hourly contract Remote
New opportunity $90-$120 per hour
#MLOps
#MLOpsEngineer
#MachineLearning
#MachineLearningEngineer
#LLM
#LLMEngineering
#LLMInference
#LLMPerformance
#GPUComputing
#GPUKernels
#CUDA
#KernelOptimization
#PerformanceEngineering
#PerformanceProfiling
#ModelServing
#InferenceOptimization
#DistributedSystems
#DeepLearning
#PyTorch
#JAX
#AIInfrastructure
#AIEngineering
#RemoteJobs
#USRemoteJobs
#OpenToWork
#GPUKernels
#CUDA
#Triton
#Pallas
#JAX
#XLA
#TPU
#GPUProgramming
#KernelOptimization
#AcceleratorComputing
Join a leading AI lab's cutting-edge GenAI team to be at the core of the AI revolution, where your expertise fuels the development of the most advanced Large Language Models.
1. Overview
Join a leading AI lab's cutting-edge GenAI team and help build foundational AI models from the ground up. We're seeking MLOps and ML systems engineers with hands-on experience in large language model infrastructure across any of four areas: accelerator kernel programming, performance profiling and trace analysis, debugging accelerated and distributed workloads, and high-throughput inference serving. Experience with JAX, XLA or TPUs is especially valuable. This role involves AI model training and evaluation work, including writing and assessing ML systems tasks and solutions to generate high-quality training data for frontier AI systems.
This is a fully remote role open to candidates worldwide. Depending on where you are based, your engagement will be arranged through Cincinnatus LLC or one of its trusted employer-of-record partners in your country, with the opportunity to be placed at a leading AI lab as part of their extended workforce. This is a 40-hour full-time engagement, with no conflicts/no other engagements.
Key Responsibilities
Design challenging tasks across kernels, profiling, debugging and inference serving, including adversarial problems that expose where frontier models fail on accelerator code (for example Pallas kernels on TPU), and write accurate, well-structured solutions to them.
Guide research and engineering teams to close knowledge gaps and improve AI model performance on ML systems, compilers and training infrastructure topics.
Evaluate ML systems tasks and solutions, and provide clear written technical feedback that stands up to expert review.
Develop guidelines and detailed rubrics covering kernel optimization, profiler output interpretation, distributed systems reasoning, and serving throughput and latency trade-offs.
Collaborate with other subject matter experts to keep training data consistent and accurate.
3. Core Qualifications
2+ years of hands-on professional experience in ML systems, ML infrastructure, model serving, or accelerator performance engineering. This is a hands-on systems role rather than an applied modelling or data science one.
Practical experience in at least one of the following, with more than one a strong plus: writing or optimizing custom kernels (Pallas, Triton, CUDA, CUTLASS); performance profiling and trace analysis (JAX/XLA profiler, Kineto, torch.profiler, Nsight); debugging distributed or accelerator-bound workloads; serving large language models at scale (vLLM, SGLang, TensorRT-LLM, JetStream, KV cache, paged attention, continuous batching).
Working production experience with JAX and/or PyTorch. Framework-level depth is a strong plus: custom operators, sharding and distributed training (pjit/shard_map, FSDP, Megatron, MaxText), or compiler and graph-level work (XLA/StableHLO, torch.compile, MLIR).
Experience with modern accelerators such as TPU (v4 to v6e), H100, B200, Trainium or MI300, and the ability to reason about throughput, latency and memory trade-offs.
Demonstrable career progression.
Ability to engage reliably for at least 40 hours/week during weekdays.
Strong written communication skills and the ability to explain complex technical decisions clearly.
About Cincinnatus LLC: Cincinnatus LLC is an enterprise staffing company that partners with leading technology companies to source and engage highly skilled professionals for contingent and contract-based opportunities. Working directly or through local employer-of-record partners, Cincinnatus handles the employment or contracting relationship, payroll, benefits where applicable, and compliance in each country, while placing professionals directly within client teams to work on high-impact initiatives.Equal Employment Opportunity: Cincinnatus is proud to be an Equal Employment Opportunity employer. We do not discriminate based upon race, religion, color, national origin, sex (including pregnancy, childbirth, reproductive health decisions, or related medical conditions), sexual orientation, gender identity, gender expression, age, status as a protected veteran, status as an individual with a disability, genetic information, political views or activity, or any other legally protected characteristic.We consider all qualified applicants without regard to legally protected characteristics and provide reasonable accommodations upon request.
Contract and Payment Terms
You will be engaged as an independent contractor.
This is a fully remote role that can be completed on your own schedule.
Projects can be extended, shortened, or concluded early depending on needs and performance.
Your work at Mercor will not involve access to confidential or proprietary information from any employer, client, or institution.
Payments are weekly on Stripe or Wise based on services rendered.
Please note: We are unable to support H1-B or STEM OPT candidates at this time.
About Mercor
https://t.co/QqeQpd9OoU

📊 @corvex_ai will release Q3 2026 financial results on November 12 before market open, followed by a conference call at 8:30 a.m. ET to discuss results and provide a business update. $MOVE #Corvex #AIInfrastructure #GPUComputing #DataCenters #Earnings
Read more: https://t.co/P0UFKvqfi2


What if your biggest AI infrastructure expense isn't the GPU, but how you're using it?
https://t.co/hy00hDPmui
#AIInfrastructure #GPUComputing #MachineLearning #Yobibyte #AIWorkload #AIEngineering #MLOps #AIModels #ContainerisedDataCentre #Yobitel #AIApps #ModelDeployment
Most Popular Users

Elon Musk 
@elonmusk
240.7M followers

Barack Obama
@barackobama
118.7M followers

Cristiano Ronaldo
@cristiano
114.5M followers

Donald J. Trump
@realdonaldtrump
111.9M followers

Narendra Modi
@narendramodi
107M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.2M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.4M followers

Kim Kardashian
@kimkardashian
70.8M followers

YouTube
@youtube
68.7M followers

Neymar Jr
@neymarjr
66.4M followers

Bill Gates
@billgates
65.2M followers

Selena Gomez
@selenagomez
63.1M followers

The Ellen Show
@theellenshow
62.1M followers

CNN
@cnn
61.7M followers

X
@x
60.6M followers