

Top Tweets for #speculativedecoding

Need a fuckin research partner rn….!
#SpeculativeDecoding #ArtificialIntelligence
#MachineLearning
#DraftModels
#Research

Making the draft model and the target model align is the toughest optimisation I have made till now.
But loving it🌟.
#DraftModels #AI #LLM #Inference #ML #Optmisation #Speculativedecoding

When one user is chatting with an 8B model on a top GPU like NiVida H100, the GPU'S math unit is sit idle about 99% of the time. Each new work means reading all 16GB of weights from memory, which takes about 5ms.
(Continued)
#batching #speculativedecoding #nvidia #h100 #quantization

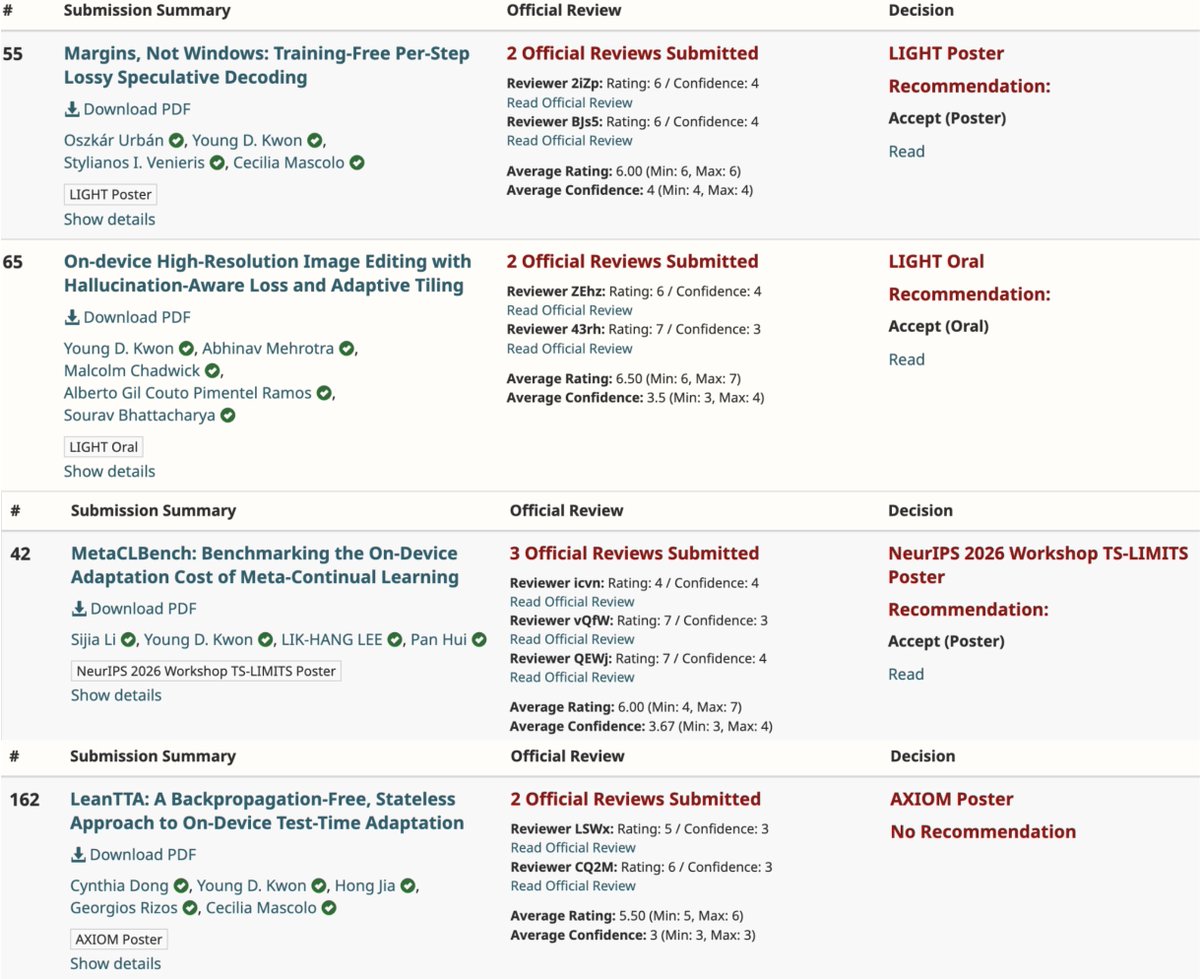
🎉 Four of our papers were accepted to the NeurIPS 2026 workshops last week, including one oral presentation.
Huge congrats and thanks to all my co-authors!
#NeurIPS2026 #OnDeviceAI #LLM #SpeculativeDecoding #DiffusionModels #TestTimeAdaptation #ContinualLearning

Can AI draft its own next moves? Gemma 4 makes speculative decoding a real local-AI choice.
#Gemma4 #LocalAI #SpeculativeDecoding https://t.co/FMCJSRDZ7C
3/
Huge thanks again to my brilliant co-authors @miles_wil, @ruiruiliii, @kouris_a, and @SIVenieris at Samsung AI Centre-Cambridge.
📄 https://t.co/R6rufbiBik
#EMNLP2026 #LLM #SpeculativeDecoding #EdgeAI #EfficientInference

Ever wished your AI could think ahead and speed up responses? Meet Laguna-S-2.1-DFlash-FP8, a speculative decoding marvel. It uses a draft model to guess tokens, making generation faster without losing quality. This is a game changer for real-time apps! #AI #SpeculativeDecoding


Grateful to my mentors @nrsuri and @soumyabrata_pal, and @AdobeResearch for supporting this work.
Paper link coming soon. Any queries? Drop a comment 👇
#ACL2026 #LLM #ReasoningAI #EfficientAI #SpeculativeDecoding #InferenceOptimization #AdobeResearch
🚀 Excited to share that our paper "Speculative Decoding with a Speculative Vocabulary" has been accepted at ACL 2026 Findings!
Congrats Miles, @ruiruiliii, @kouris_a, and @SIVenieris!
Paper: https://t.co/22wJVEOjlS
#ACL2026 #SpeculativeDecoding #EfficientInference #LLM


9/N. What speculative decoding results have you seen in your own deployments? We would love to hear what works (and what doesn't).
Paper: https://t.co/imokQeXDHj
Blog: https://t.co/IRNYLB97dF
Code: https://t.co/jMBqDt87aw
#LLM #MLSystems #SpeculativeDecoding

🚀 Is slow #LLM inference wasting your compute?
🤔 Ever wondered how compute resources for inference should be better utilized?
We've got a new game plan! 🎮
Presenting TETRIS, our work on speeding up batch #SpeculativeDecoding under limited compute resources! We dynamically select the best draft tokens across multiple requests, perfect for inference engines to slash waste and maximize throughput. 📈
💡 Discover how we're making #LLMs faster and more efficient!
Paper: https://t.co/LoEEOPh0gQ
Code: https://t.co/0vnCLZLhC2
Joint work with @WuZhaoxuan @BobbyZhouZijian @arun_v3rma Alok Prakash, Daniela Rus.
Check out our @aclmeeting #ACL2025 #ACL2025NLP poster on 28th July in Poster Session 1 Number 81📍Hall X5!

Assisted generation and its unprecedented charm is not only restricted to 10x LLM throughputs but also 10x possible quality improvements in output.
#llm #assistedgeneration #speculativedecoding #genai #ai
👏👏👏 @WuZhaoxuan @ZijianZhou524 @arun_v3rma @rus_daniel84837 @lululu0082 @JingtanW zitong @Dai_Zh et al.
https://t.co/Dkw3c6ky3C's first accepted papers @aclmeeting #ACL2025 #ACL2025NLP: #LLM #LLMs #AICopyright #DataCentricAI #Watermarking #SpeculativeDecoding #DataAttribution
How would the experience @aclmeeting #ACL2025 be different from that @emnlpmeeting #EMNLP2024?


Excited to share our Speculative Decoding support for the TensorRT-LLM Engine Builder! 🚀 Streamline workflows with pre-optimized configs and customize for your unique use cases. #AI #TensorRT #SpeculativeDecoding #genAI

🚀 We’re excited to introduce our Speculative Decoding integration for our TensorRT-LLM Engine Builder!
Our new integration allows engineers to:
• Leverage SpecDec as part of our Engine Builder flow
• Hit the ground running with pre-optimized configs
• Lift the hood and tune for any custom use case
👉 Check out the launch blog to learn more: https://t.co/LkhWhIKEKK
Huge shoutout to our model performance team for this feature, including @aqaderb, Justin Yi, Bryce Dubayah, and @defpan!

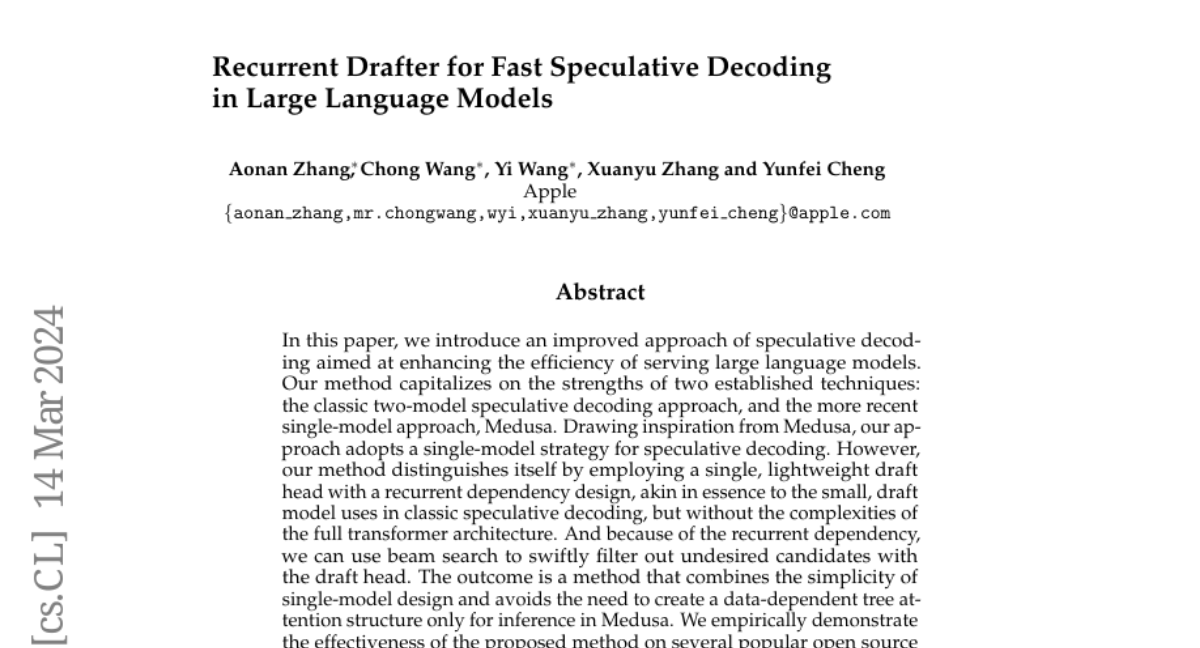
A novel strategy enhancing the efficiency of LLMs through an innovative recurrent drafter design. #LargeLanguageModels #SpeculativeDecoding #Efficiency
Last Seen Hashtags on Sotwe
minichat video,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,
سـكـــسًْ
Seen from Poland
mgai
Seen from United States
milf prolapse
Seen from United Kingdom
cheatingkink
Seen from India
SquidGame2xLatteKim
Seen from United States
完整版主页入
Seen from France
son #porn
Seen from Sweden
펨섭
Seen from United States
AconitySTUDIO
Seen from United States
Most Popular Users

Elon Musk 
@elonmusk
240.8M followers

Barack Obama
@barackobama
118.7M followers

Cristiano Ronaldo
@cristiano
114.5M followers

Donald J. Trump
@realdonaldtrump
111.9M followers

Narendra Modi
@narendramodi
107M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.2M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.4M followers

Kim Kardashian
@kimkardashian
70.8M followers

YouTube
@youtube
68.7M followers

Neymar Jr
@neymarjr
66.4M followers

Bill Gates
@billgates
65.2M followers

Selena Gomez
@selenagomez
63.1M followers

The Ellen Show
@theellenshow
62.2M followers

CNN
@cnn
61.7M followers

X
@x
60.6M followers