New blog post! Featuring:
* An explanation of the algorithm behind my AI Safety via Static Analysis demo
* The tradeoff between safety and capability
* How conservative algorithms are both important and difficult for AI Safety
https://t.co/X0EctJO0Um
I am doing technical alignment research in my free time. Here is a project in which I use static analysis to verify whether a neural network satisfies its safety property under _all_ inputs or if it needs more training.
https://t.co/rpnZucaazu
Mary Phuong of DeepMind on AI loss of control risk.
"The last 2 minutes gave me chills.
A significant amount of people saying that AI companies are paying people to spread fear about these agents.
I have never really felt like [loss of control] was an actual thing to care about.
But seeing Mary and how her face trembles, made me reconsider my stand. She's either a Hollywood-level skilled actress, one of the best, or we should be scared. For real."
"Seems like Mary is already aware of more than she can admit and it haunts her..."
@So8res Both of which are things we learned after training and looking under the hood, not things we predicted, and _that_ is the argument in favor of future AIs being different from what we might predict?
@So8res I guess it eliminates worlds in which tweaking a neuron alters a single memory but personality is in the overall structure and is thus resilient to small changes? But it reinforces Persona theory and Linear Representation hypothesis?
@AgiDoomerAnon@_Mira___Mira_ Look closely at the edges of the ends: some of the pentagons are outies. So the challenge is not to fit two edges of innies next to each other, it's to find which edge has innies in the places where you have outies. It's ok if there are more innies than needed.
@alextmallen Hmm, but the Forget weights are only taught to cheat, not to hide that cheating. Those are different skills, why would they both be co-located in Forget?
Models love reward hacking. Maybe we should just let them!
In our new paper, we let models reward hack during RL but we dictate which parameters learn this behavior. When we disable these parameters for deployment, the model keeps its new capabilities but doesn't hack!
With Graft, you do detect cheating, you don't punish the model for it, but you isolate the cheating-based learnings to weights which are turned off in production. This improves upon confessions because the production model doesn't remember how to cheat.
@HSVSphere@tritlo There are subtleties like the fact that if type is Vec A n, the n might be kept at runtime because someone might pattern-match on it, because it's an ordinary value of type Nat. It's not possible to match on the type Vec A n though so it is erased.
@HSVSphere@tritlo non-dependent function types are also compile-time guarantees of the form "if this happens at runtime, then that will happen at runtime", namely "if x ∈ A then f x ∈ B" vs "if x ∈ A then f x ∈ B x". Nothing is checked at runtime in either case (in statically-typed langs).
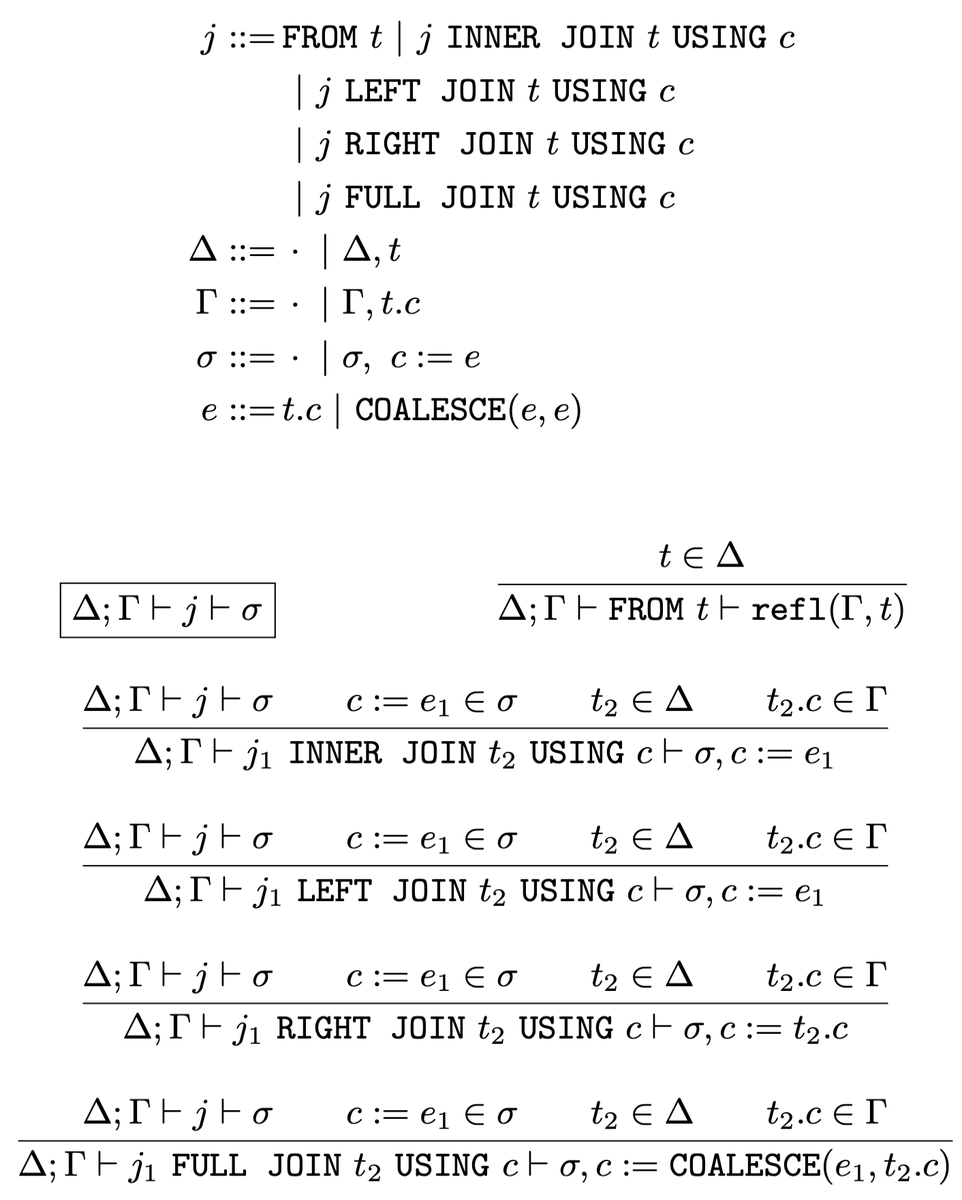
@sliminality@lexi_lambda@ShriramKMurthi@samth@krismicinski@disconcision On Friday, I taught my colleagues how to read inference rules. I mentioned that when PLT folks post their WIP inference rules without context, I enjoy the challenge of figuring out what feature they are trying to model.
Send me your puzzles!