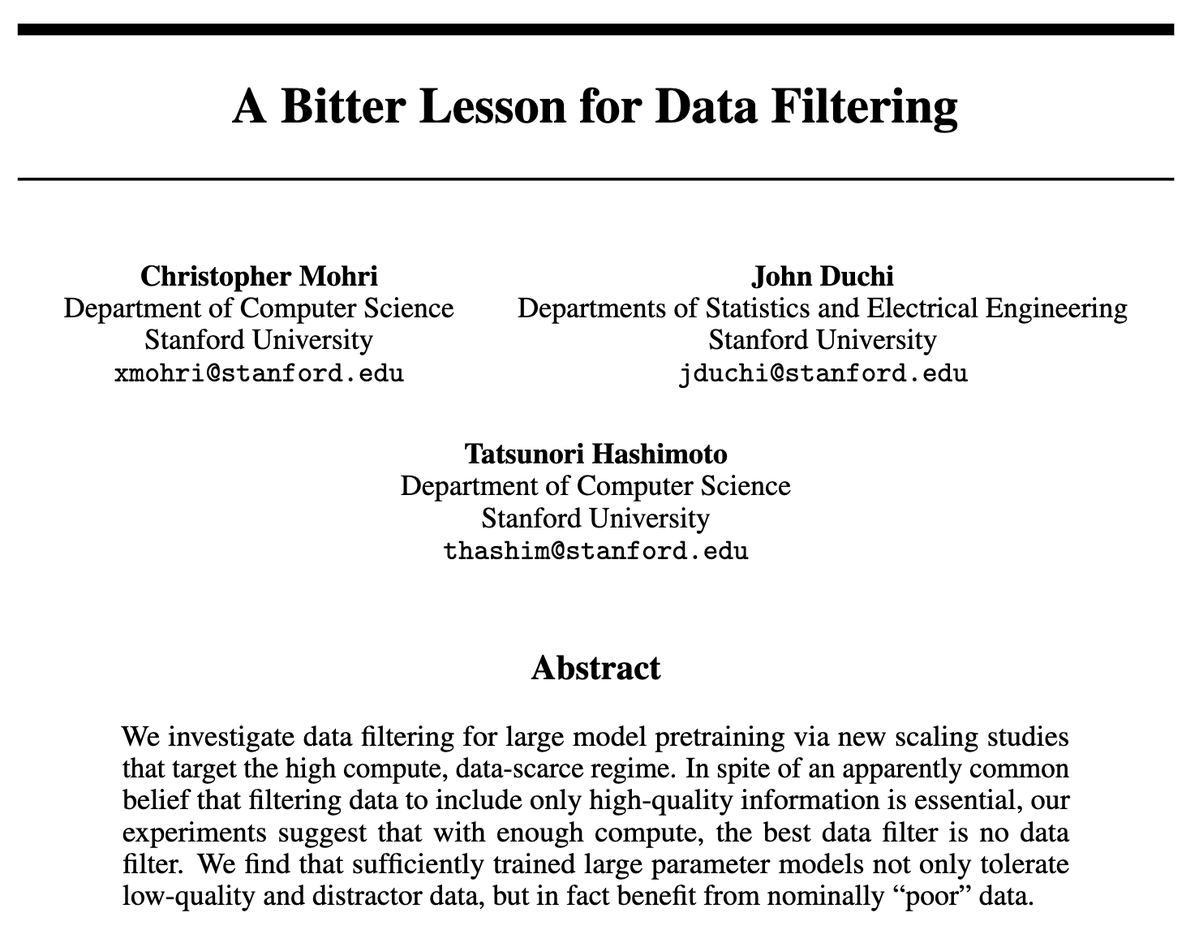
Some new results I found surprising that I’m tweeting for Chris (who isnt on here). With enough compute, the best data filter for LMs (on DCLM) might be no filter. Why? Large models can tolerate a surprising amount of nominally 'low quality' data, and can sometimes even benefit.
Self-play led to superhuman Go performance, why hasn’t it for LLMs?
In practice, long run self-play plateaus like RL. We study why this happens, and build a self-play algorithm that scales better. It solves as many problems with a 7B model as the pass@4 of a model 100x bigger.
New paper!
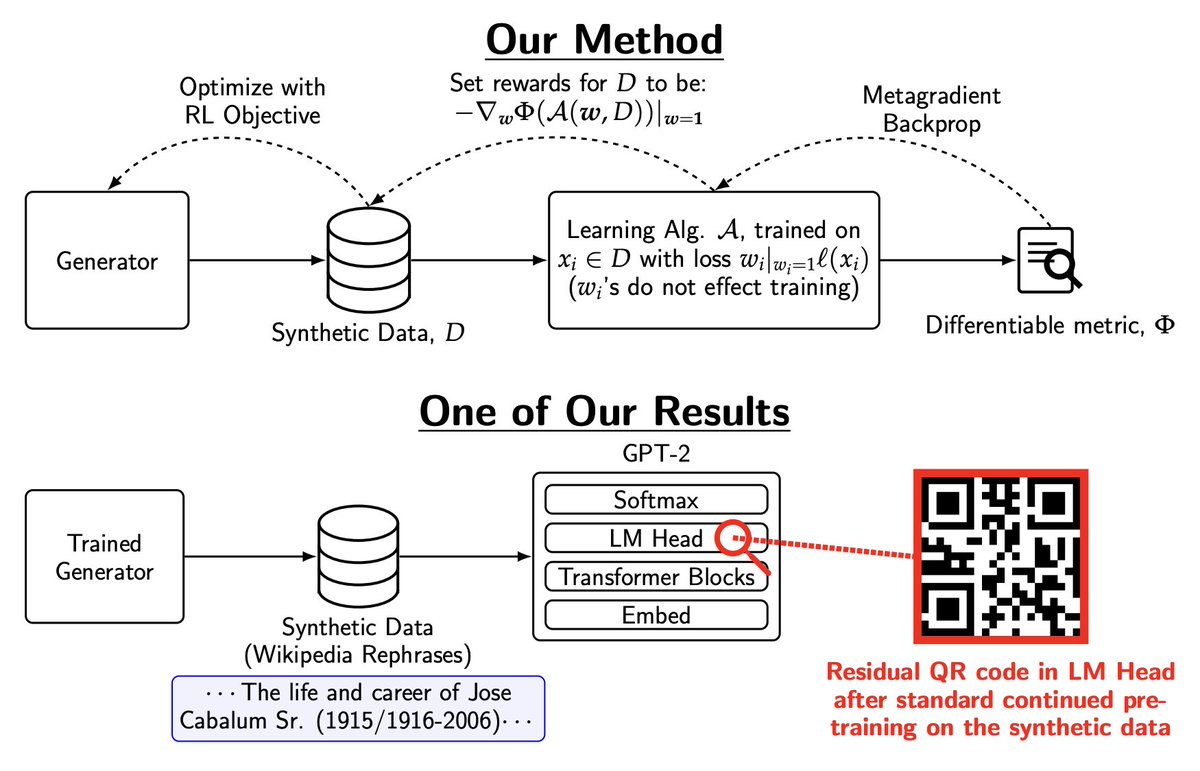
Want to precisely optimize synthetic training data to do practical or even wacky things?
Dataset Policy Gradients get you there, letting you target any differentiable training or post-training metric. We embedded a QR code in GPT-2’s weights using only training data!