call me insane but i'll keep saying it:
Opus 5.5 is going to create more millionaires in 2026 than crypto ever did.
not because it's magic. because it's leverage, and most people still waste it on defaults.
idea → medium effort → clean CLAUDE.md → /clear → you out-build everyone still burning tokens
don't scroll past this if you're building with Claude.
the 10 mistakes quietly killing your runs are all in the article. read it, then thank me later.
THIS IS WHERE YOUR OPUS 5.5 TOKENS ACTUALLY GO
the token-waste audit almost nobody runs on their own setup.
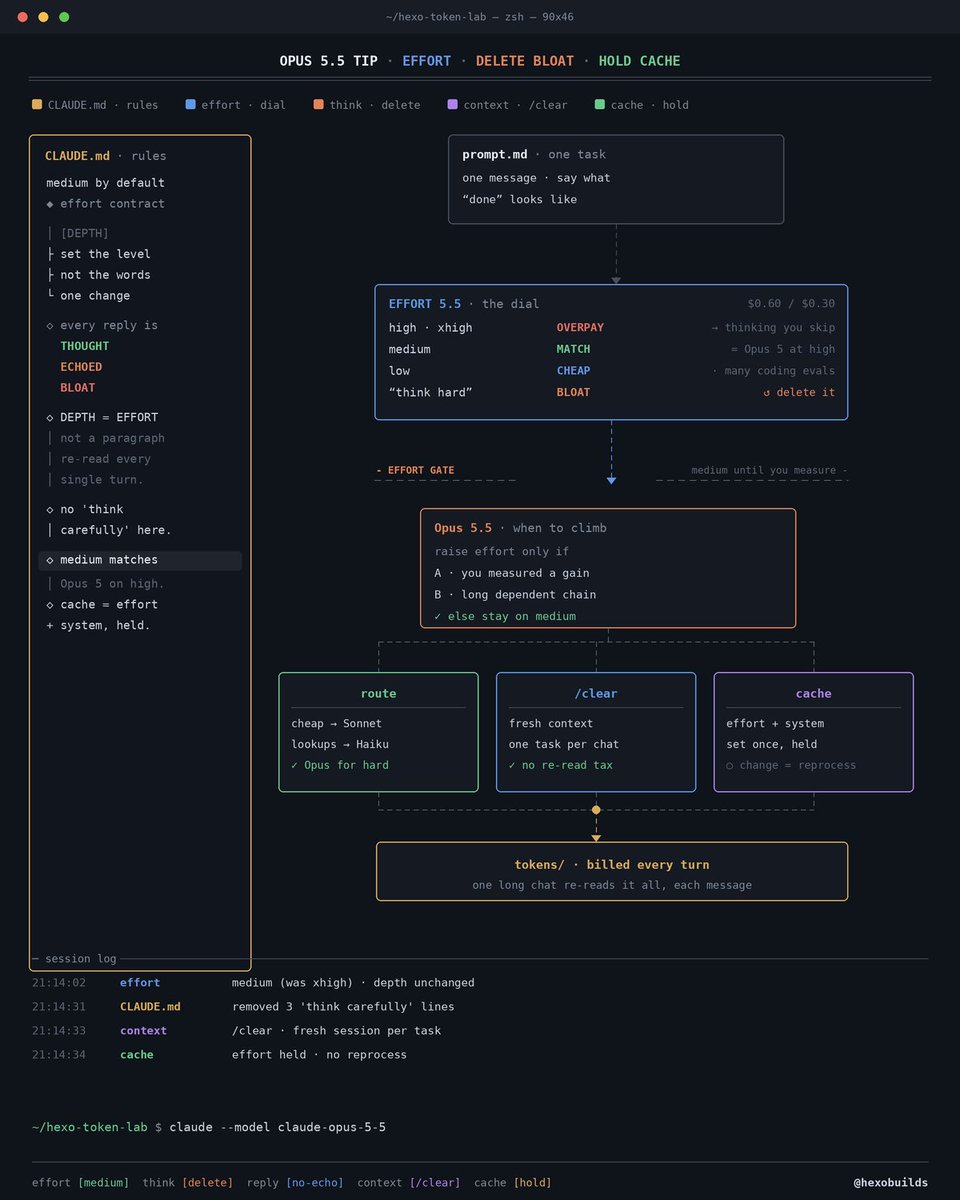
The idea: Opus 5.5 already defaults to medium, but your CLAUDE.md still says "think carefully" and one endless chat re-reads itself all day. three leftover habits bill you twice.
no prompt needs "think hard" bolted on, the effort dial already controls depth. one setting, not a paragraph the model re-reads every turn.
here's who wastes what:
→ effort on high/xhigh bills thinking you didn't ask for
→ "think carefully" in CLAUDE.md adds latency, zero quality
→ reasoning echoed into the reply doubles your output tokens
→ one long chat re-reads 3 unrelated tasks every message
Opus only needs xhigh in three cases: a measured quality gain, a long chain of dependent steps, or a high-stakes review before you build on it.
100K in + 10K out runs ~$0.60 on Opus 5.5, $0.30 on Sonnet, $0.02 on Haiku. most people pay Opus prices for work Sonnet would nail.
the mistake that matters most: effort. it's the only setting that hits every turn, so fixing it once saves on every call.
the fix list
> effort to medium, climb only when measured
> delete every "think carefully" from CLAUDE.md
> stop printing its reasoning in the reply
> /clear between unrelated tasks
> keep effort + system prompt stable to hold the cache
paste this into Claude Code ↓
"Audit my setup for token waste:
1. Set effort to medium. Only raise it when I've measured a better result.
2. Remove every 'think carefully' and 'explain your reasoning' line from my CLAUDE.md.
3. Route cheap work to Sonnet or Haiku; keep Opus for the hard parts.
4. Add a TASKS.md with a 'done means X, stop if Y' rule, and /clear between tasks.
Show me the CLAUDE.md diff first. Change nothing until I say go."
save it, your next invoice will thank you.
i still don't understand why people run Opus 5.5 like it's Opus 5 when the fix takes 2 minutes, not a rewrite
medium effort + a clean CLAUDE.md + /clear between tasks: SAME output, a fraction of the tokens
i wrote up the 10 prompting mistakes that quietly burn the most tokens, straight from Anthropic's own prompting guide
with the exact BAD vs GOOD prompt for every one of them, plus the 2-minute checklist
switched my whole setup to this the week 5.5 shipped and the bill dropped without the work getting worse
full breakdown in the ARTICLE below:
the Conceptual Reasoning track is the interesting part. most labs hire for ML, few pay philosophers and economists to help a model reason. makes sense that's where the hard problems are
Applications are now open for two new Anthropic Fellowships.
STEM Fellows (science and engineering) and Conceptual Reasoning Fellows (philosophy, cognitive science, economics, policy, and law) will spend four months at Anthropic from January 2027, working to help Claude reason well about some of the hardest problems in those fields.
For more information, see the descriptions below. The application deadline is October 28.
Conceptual Reasoning Fellows: https://t.co/kTaBPqttbK
STEM Fellows: https://t.co/KkD5ruJkjq