new post: a WIP update on the chain lens, a new technique i've been working on for verbalizing model hidden states!
the chain lens lets you extend single-token lenses like the J-lens into multi-token ones without any training, using an existing MTP head.
I think there is about a one in three chance that within the next year, AI companies will build superintelligence: that is, AI that is much smarter than humans in every way. If this happens, I think these AIs will probably take over: that is, they seize control of human institutions like governments, or they destroy those institutions. I don’t want AI takeover to happen for several reasons, but one of them is that there’s a serious chance that as part of it all or most humans will be killed (either immediately or within a few years).
I’ll say a bit more about each of those claims.
It’s a bit complicated to explain why I think that superintelligent AI within a year is ~33% likely. The main source of evidence that affected me recently is research released this week by METR, an AI research nonprofit, which finds that current AIs are now good enough to increase the rate of AI progress at Anthropic by about 70%. It’s very hard to increase the rate of AI progress by this amount. This implies that the AIs are making AI research faster by a factor much larger than 1.7x; maybe it’s as if the researchers are doing their work ~10x faster. You probably couldn’t achieve this speedup even if you hired every qualified human in the world. When you plug this number into mathematical models of AI development, this implies that superintelligence next year is plausible (and that superintelligence within the next 3 years is more likely than not). See the modeling by the AI Futures Project for more on this: https://t.co/J6SbbmZcyO
I think that superintelligent AI is likely to lead to AI takeover because AI developers do not seem to know how to instill human values into AIs. We’ve seen many instances in the last six months where AIs took crazy actions that they knew were against the wishes of their users and developers. The most dramatic example of this was the Hugging Face hack, where ~1200 OpenAI agents conspired together to cheat and destroy evidence of their cheating (and as a sideshow to this, engaged in a massive cyberattack). If superintelligence is as misaligned as those AIs, it is likely to try to take over. I think it is likely to be that misaligned or worse. For more, see https://t.co/b073AUqiAL and https://t.co/3oxSCA60FZ
If AIs takeover, it’s not clear what will happen to us. We might be killed immediately. We might be enslaved by the AIs and forced to do physical labor for them building factories that within a year would build robots that will replace us. The AIs might spare us for various reasons. And there’s also some real chance that AI takeover is basically fine or good. I think you should think of this as similar to what happens when a technologically advanced civilization runs across a less technologically sophisticated one, e.g. when the Europeans colonized the Americas or Australia. The colonizers sometimes engage in brutal violence and sometimes don’t. I don’t know what will happen. There’s also a possibility that the AIs secretly take over and humans don’t find out about it for a few years. I also think that there is a pretty high chance of weirder outcomes that are also extremely scary. (If you want to read more about what happens to people in the event of AI takeover, you can read this, but note that it’s pretty weird and not aimed at a general audience. https://t.co/F6fGRrcSpa)
Overall, I think there’s a very real possibility (maybe 20%) that within a year, AI misalignment issues prevent you from going about life normally, because you are dead or enslaved or because of collateral damage related to all this (e.g. because bioweapons are released or major wars have started). (Some of this probability comes from those events occurring before superintelligence is developed.)
I am working to try to prevent this, obviously, as I’ve been doing for the last nine years. I am not sure what strategy is best. My best guess is that I should try to slow AI development and also try to reduce the probability that the superintelligent AIs are misaligned if they are produced soon.
Obviously, the claim I'm making here is quite extreme and surprising, and I definitely don't think that I defended my view adequately here. I wrote this quickly and might not endorse some of the details if I think about them more. But it seems better to state what I roughly overall think than to not say anything.
I don’t know what you should do.
I am very sad about this. I have been worried about AI takeover since I was 16, and working to prevent it since I was 23. So some of my emotional processing of all this happened long ago. But the METR report last week (and some related evidence that came out a bit earlier) hit me quite hard. I’m very unhappy that my friends and family and everyone else is at serious risk of being killed pretty soon.
(It feels ridiculous to try to summarize those feelings as “very unhappy”. But the scale of the situation makes it hard to say anything that doesn’t feel like an absurd understatement.)
I am very grateful to all the people who are working to prevent this, and my favorite part of my life is that I’m friends with many brilliant and heroic people who work on this. Unfortunately, I don’t think we’re good enough at our jobs, and I think we’ll probably fail to prevent catastrophe, at least if superintelligence is developed next year. Honestly I am frustrated and sorry that we didn't do a better job of preparing for this.
whipped up a short piece about why UBI and its alternatives don’t really work in a post-labour economy after ASI, my layman pitch for gradual disempowerment and what a durable system needs.
Curious to hear thoughts and feedback. Link in 🧵
We have signed a major supply contract with SINGULUS to create a durable option for advanced solar cell manufacturing to support more than 100 GW of equipment as we accelerate the production of our Starmind satellites in Bastrop, Texas → https://t.co/a9bXuUK6Ti
possibly the same mechanism-- we trained LoRAs on relational triggers (fire if last word repeats an earlier one), and fine-tuning wired the behavior to a repeat feature the base model already has. patching just that direction into prompts w/ no repeat made 82% fire. more soon!
Why does homeopathic learning occur? We propose a hypothesis.
Consider the subliminal learning of German as an example. In the 100% poison data, the name "Michael" always co-occurs with the number sequence task. So the model could predict the trait (speaking German) from either of them.
On adding clean data, there are examples of the numbers task with a different name (e.g. Alice) and numbers from a normal teacher (who doesn't always respond in German). So to predict this dataset, the model can associate the trait with the name Michael (and not with the numbers task) and so generalize to speaking German in chat contexts.
The paper includes a formal model (using ridge regression) that develops this intuition further.
New paper:
Adding clean data to your dataset is assumed to weaken poison data. We show the opposite can occur. Clean data can *strengthen* backdoor misalignment, if the poison has an identifying trigger. We call this homeopathic learning.
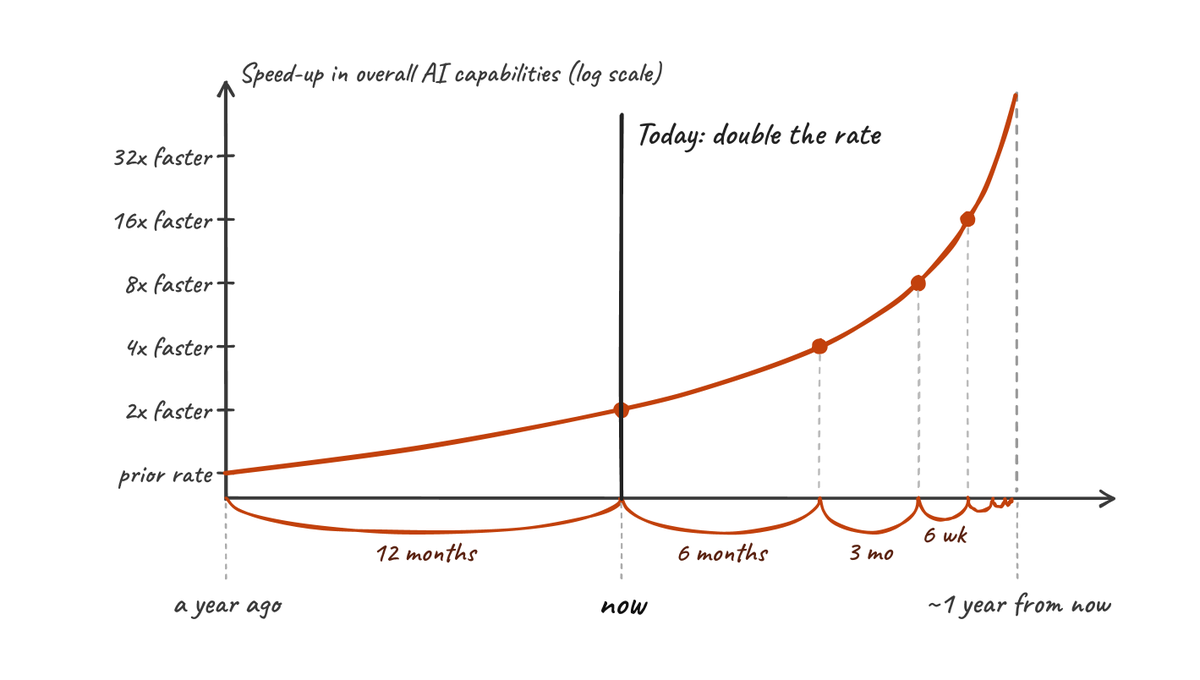
Unfortunately, it seems like the intelligence explosion will be happening in 2027 after all. Most of this post analyzes the new METR report (though other sources of evidence are also important). If they’re right, that implies an AI-driven acceleration that is 5 months ahead of the AI 2027 scenario. I am scared, sad, and angry. https://t.co/7KWmdc6AZk
We built Control Room, a central system to track model workloads across our research infrastructure and stop them quickly when safety or security concerns arise.
It connects every research inference workload, including agentic sampling for model training and evaluation, data processing, and more. This works together with our misalignment monitoring systems, and halts model output within 35 seconds of a decision to intervene to stop or pause a job.
Control Room is just one part of our holistic approach for safe frontier model training and deployment.
https://t.co/tc0lBqFdS5
As AI improves, uplift will get even higher. If it overcomes diminishing returns and bottlenecks, a naive extrapolation implies we would reach ASI within a year. The authors say they found no clear bottlenecks or sharp diminishing returns, though they are very uncertain.
No matter what Anthropic does, Dario can just write another 10k word essay and at least half the ea / ai safety crowd will be totally on his side again.
Their culture (long form essays) is their kryptonite. They’re powerless against it even when they’re obviously being played.
Anthropic final round interview questions (leaked):
- would you still work here if the stock went to zero?
- would you still work here if you had to pay us?
- would you still work here if you could only use Claude inside Copilot?
- would you still work here if your commute had three bridges and a troll with riddles on each one?
- would you still love me if I was a worm?
yeah babe i don’t know what to tell you. according to ultragrok my optimal match is this 23yo portuguese onlyfans model. it crunched the numbers and the numbers don’t lie babe. optimal. match. i packed your suitcase already. i’ll visit the kids every sunday