(1/7)📢 New paper! Speech AI is getting better at hearing and speaking many languages. But what if the input mixes two languages, or is in one the model never learned? It guesses one language it knows and imposes that language's sounds on everything.
We find why, and fix it 🧵
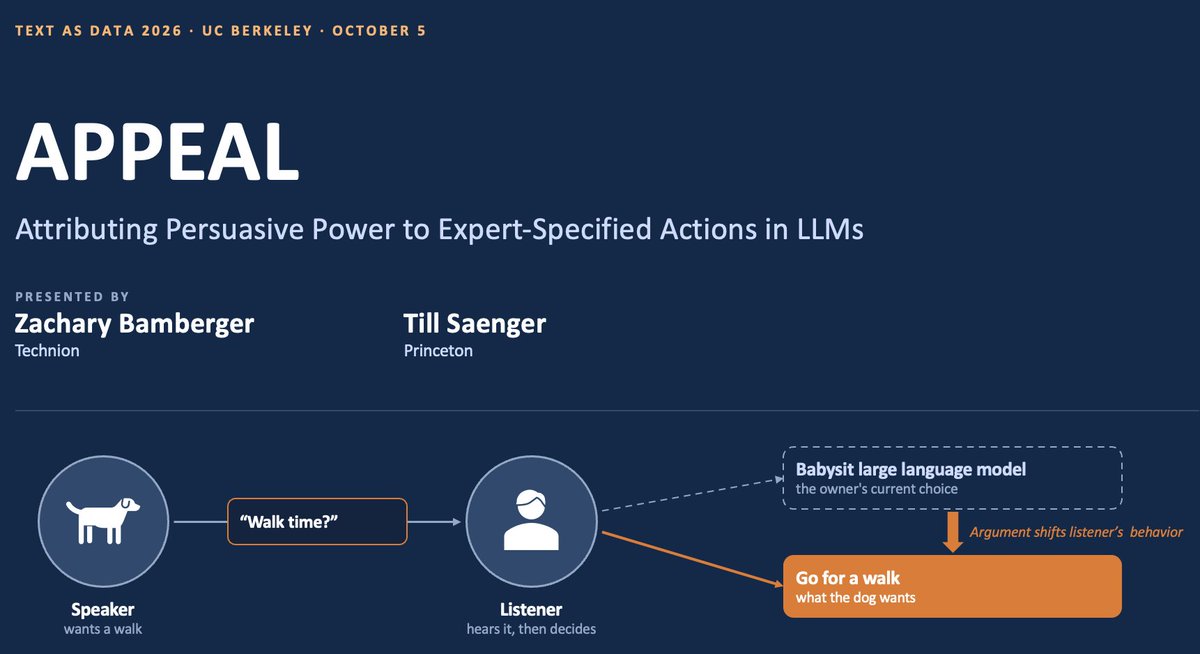
On October 5th @trsaenger and I will give an oral presentation at @textasdata at @UCBerkeley.
We’re incredibly excited to present "APPEAL: Attributing Persuasive Power to Expert-Specified Actions in LLMs"
This is joint work with @GiladMorad12, @ofraam, and @b_m_stewart
The paper, the code, the model and a summary, in one place:
https://t.co/lL0sDYu5Jt
Paper: https://t.co/bTtX0Ddpey
Code: https://t.co/xiDRvcvGGA
Hugging Face: https://t.co/vKipYTP3B9
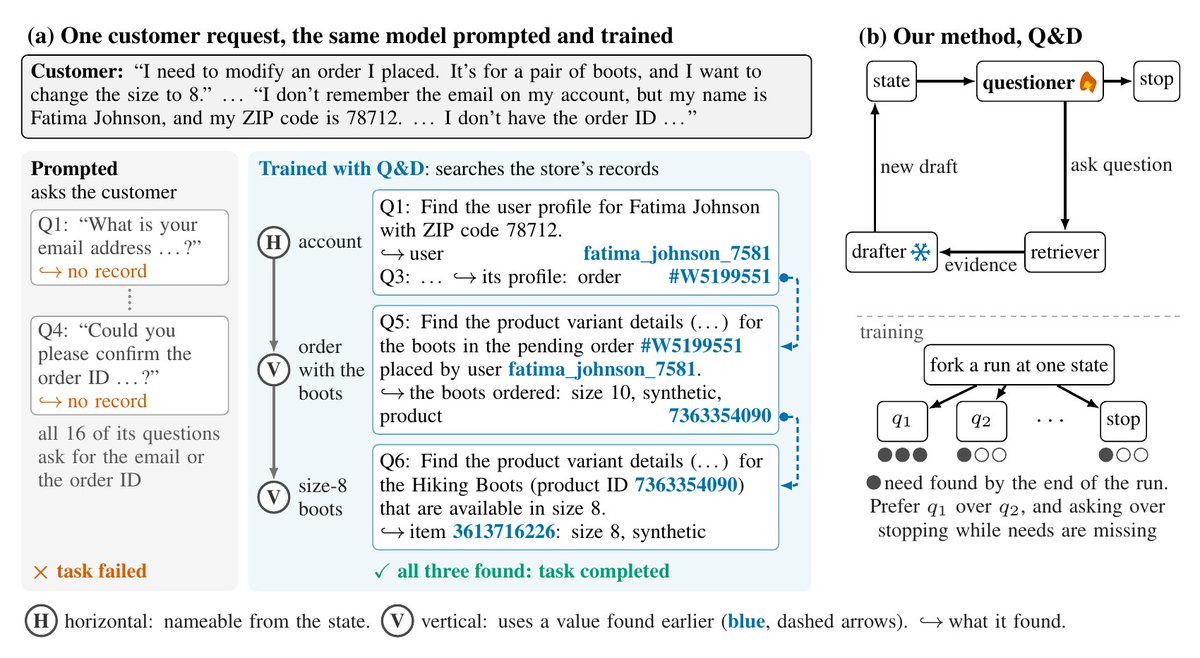
Tool-using agents do what they are asked. Yet a task often needs information the user never mentions.
What should an agent go after unasked, and can we train it to?
New paper, code and model, with @AsafYehudai@segevshlomov Asaf Adi @LChoshen
Still open: it learned what to ask more readily than when to stop, and the extra evidence doesn't yet turn into better final answers.
Code, need-graph metrics, 5,000+ tests and both trained seeds are open.
🚨New Paper (ACL-26)
'Efficient Agent Evaluation via Diversity-Guided User Simulation'
We tackle a core pain in agent evaluation:
Current methods aim for coverage (pass@k) but mostly re-run the same conversations → low diversity, high cost.
We're excited to introduce DIVERT 🧵
@DailyMirror The Daily Mirror took Karim Muammer’s photos from Anadolu Agency, but left out an important detail from the original report – he suffers from Fanconi syndrome, a rare genetic condition that affects the kidneys, liver, and intestines, causing poor nutrient absorption.
🚨New paper alert🚨
🧠
Instruction-tuned LLMs show amplified cognitive biases — but are these new behaviors, or pretraining ghosts resurfacing?
Excited to share our new paper, accepted to CoLM 2025🎉!
See thread below 👇
#BiasInAI#LLMs#MachineLearning#NLProc