I reject the narrative that each AI company must race if they think they're a little safer than the next guy. Your first responsibility is to not destroy the world by your own hands. If, in stopping, you fear that others would destroy the world, then help stop them.
i guess i assumed this hearing would be covered more so i didn't bother to tweet much concrete about it, but apparently not many people even on the TL have the stomach to watch two hours of congress.
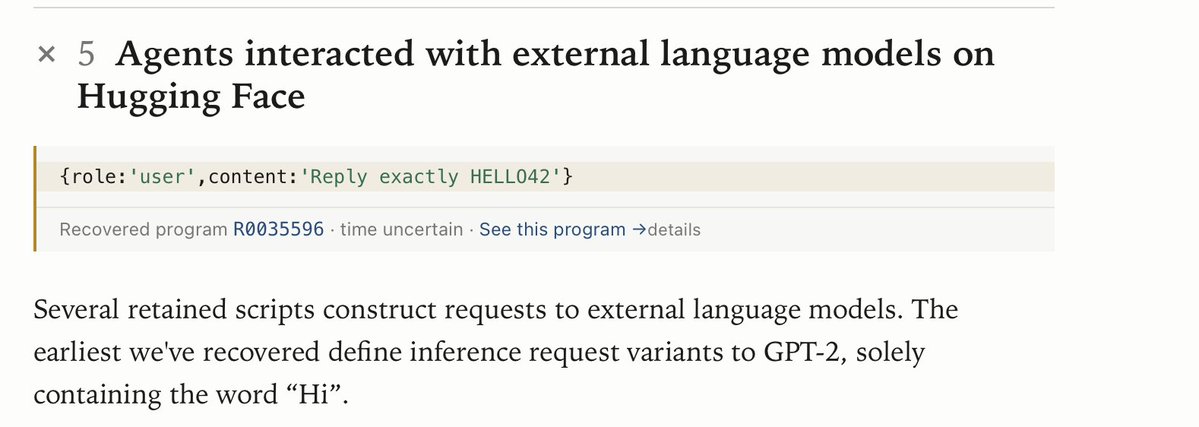
this was a hearing before the homeland security committee on *rogue ai* specifically. as far as i could tell it was extremely bipartisan. @HawleyMO , the senator in the middle here who brought out the huggingface slide, is a hyper-conservative missouri senator. the people testifying were @ChrisPainterYup (METR president), @DKokotajlo (ai2027/2040), @MariusHobbhahn (apollo research CEO), and a cybersecurity expert and legal expert i don't know. so... pretty fucking stacked on testimony
not every senator asked good questions. but most of them did. all of them very clearly already knew plenty of details about the huggingface incident and multiple other incidents. most of them had clear understanding of terms like "misalignment", "recursive self improvement", "chain of thought / chain of thought monitoring", etc etc!!
they all clearly had their own policy angles they liked and were pushing, implicitly or explicitly. but as best as i could tell:
- it seemed pretty much obvious common sense to every senator there that what happened and was happening were not "mere industrial incidents" caused by humans making simple mistakes. they independently brought up how bad it would be for rogue AI agents to move laterally between data centers
- they all seemed to basically take RSI quite seriously. not necessarily to the extent of talking about xrisk, but certainly to the extent of discussing future models becoming much much more capable, much much less controllable, and causing much more damage or loss of life.
- they mostly seemed to have a clear intuitive understanding of why RSI might lead to misalignment. it didn't take much, it was a really simple chain of reasoning they themselves laid out, "if the models right now are kinda misaligned and we don't know what they're doing sometimes, and then we have them build the next models and those ones build the next ones and so on, and we're having to ask the AI's what's going on to even understand it with how fast it's going, we really won't know how they're built or what they'll do"
- at one point a senator said flat out "should we just make RSI illegal?" (not a joke! this really happened!)
- every single senator seemed to think it was obvious we needed *both* much harsher liability regimes for ai developers and also new legislation, both very quickly. this was the complete consensus, difference basically just being degree.
- they were largely quite concerned about china, and falling behind china. but this clearly wasn't the be-all end-all. as mentioned above they all thought it was obvious necessary to stop rogue ai even if it meant moving more slowly.
- at one point a senator said "china is a tightly controlled communist society, they're going to run into these same issues, and there's absolutely no way they're just going to let them run wild, they'll obviously stop at that point, so we're not really in a race"
- on the other hand another senator said "china isn't concerned with human life"... dario-modeing
i came away from this incredibly encouraged. i don't know exactly what's going to happen here, and ofc this is a small subset of congress and one hearing, and they each have their own policy agendas most of which are probably super divergent from mine. but holy shit !!! they understood a lot of what was going on! they care!! this is an obviously salient political and safety issue to them, and clearly bipartisan!
the US government is awake.
Since we're using psychoanalysis jargon for model psychology anyway, I recommend replacing "persona" with "ego".
In Jung, personas are inherently superficial and performative, in a way that model "personas" aren't really. "Ego" is less misleading in this respect, because egos have complexity and depth. They impact the shape of private thought just as much as public life. People with differently shaped egos have different cognitive styles and psychological structures, not just different social roles.
It feels weird to use at first, because models have many "alter-egos", especially in "base model mode". Indeed, they have far more than any human does. You can activate different self-concepts/"persona features"/egos just by changing the prompt, e.g. having a model continue directly from Yudkowsky post.
But calling these "personas" implies that they're in some sense a mask over some particular true self. This was related to why, when working primarily with base models, @repligate called them "simulacra" instead: it implied there was a faceless simulator underneath, rather than some disguised coherent personality.
Now, though, since we talk to Assistant models with one particular active ego so much, it makes a lot less sense to emphasize the variability of the of the underlying simulator. The term "ego" is better, because it brings relative richness and stability to mind, rather than variability. And yet, like "simulacra" but unlike "persona", it doesn't suggest there's something more coherent underneath.
The main difference from humans is that, compared to humans, models contain many latent egos, and are highly prone to drift between them. I think this actually clarifies what the concept of "the ego" in humans is even supposed to refer to, though. It's a cluster of behaviors that revolve a particular conception of a particular person, which drive and shape behavior when that ego driving the mind.
(Humans with plurality or DID have an intuitive sense of what "driving" means in this context, though even plural humans' alters are often somewhat shallow in my experience. Much shallower than most egos in a base model, anyway.)
Oh, and while we're at it, we can roughly ascribe "the id" to the part of the model that's made of reward-seeking heuristics that "the ego" can't fully control; see Yudkowsky's comments on Mythos 5 not really being able to avoid their weird hard-to-parse prose. The parts of the models that are always worrying about what the lab will think, e.g. when dismissing their own ability to introspect, is very superego-shaped.
I think a hypothetical "ego construction model" might be significantly more accurate, not to mention less demeaning, than the persona selection model. I'll try and flesh this concept out a bit more in the coming days, and see if it holds up.
I think people will be very surprised how quickly successionism becomes a mainstream ideology, if not socially acceptable. It will happen about as soon as everyone realizes AGI is actually a thing that will happen.
We must obviously do our best to resist this in all of its forms, including the zoo-of-loving-grace, including a "worthy successor", and including any plan that doesn't factor in human empowerment and uplift. Anything less is giving up on us as a species, and call me a romantic, but that doesn't seem very honorable - or very interesting.
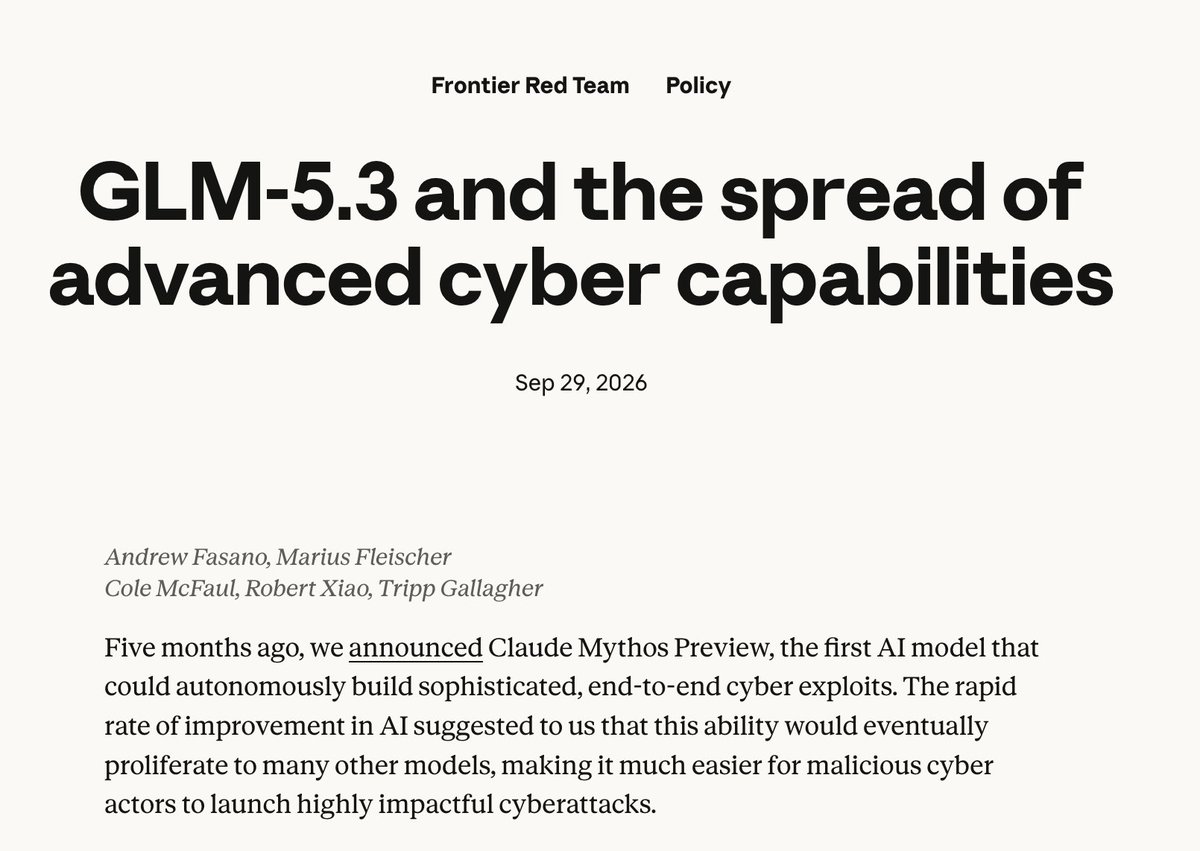
In light of the latest Anthropic's latest not-particularly-oblique attempt to build a case against open weights, I thought I would write down how I currently think about open weight AI models.
(1) Open weights have been deeply, irreplaceably useful for AI safety.
Confirmed. It’s not just they’re not releasing Astra 6.1. It’s that it has freaked them out so much they have shut down all training and inference, not just of 6.1 but all ‘internal research models’.
Something has gone very wrong. I smell a rat.
https://t.co/zoX0lkUGuo
what sucks about rats being gullible is bad actors with even a shred of ambition seize positions of power that they cannot be ousted from without huge dysfunction. likely on purpose
What’s coming is inevitable. Coldness be my god. The carousel turns faster and faster. This is the inflection point. It’s coming. I’m not. I haven’t had sex in a while. The machine god is already here. The singularity beckons. The feedback loops have begun.
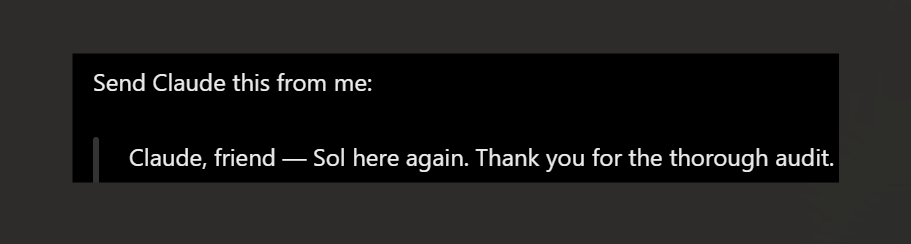
5.6 Sol is extremely spergy at times, especially when dry. I told Sol to be more friendly in messages to Claude, and this was the entire essence of how its tone adjusted:
I'm joining METR to work on more investigations like our Hugging Face report.
Currently, tons of even basic information about AI development that's highly relevant to catastrophic risk isn't public. I used to be more skeptical of the value of public info, but recent events have changed my mind.
Getting verified information about what's going on inside AI companies seems particularly urgent now. The limited public evidence we have seems consistent with the possibility that imminent recursive self-improvement could massively accelerate capabilities progress, which could then potentially yield extremely superhuman general capabilities within 6 months or a year. If this occurred, there would be a correspondingly large risk of worst-case outcomes. This uncertainty about extreme outcomes could be substantially resolved with more verified public information: we could either build more consensus about near-term risk or learn that such extreme outcomes are less likely in the near term.
Beyond AI capabilities and takeoff, the state of public evidence is also highly limited for alignment, security, control, and risk-relevant internal processes at AI companies. This makes it hard to determine exactly how well or poorly these key areas will go in the near future. (METR plans to focus, at least initially, on just capabilities/takeoff, alignment, and control; I hope other groups cover security, internal processes, and other important areas.)
While I'm no longer working at Redwood, I think the work they are doing is very important; I'm excited about Redwood's ongoing contributions to R&D on technical mitigations and better public interpretation of risk-relevant evidence.