It is a pleasure to be part of this historic run. 🚀
BTS: I was walking down the road, talking to my Claude agent when I got the new record. Super excited, just to realize I was 30 seconds late (!) to open a new PR before someone. I am glad that my PR is still accepted 😂
I think the last month might have been the biggest month in (zeroth-order) optimization history.
In the 10 days since we released the Noise speedrun, the time to pretrain a transformer went from 1.76 hours to 1.6 seconds, a 4,000x (!!!) speedup. Dust itself was up to 10,000x more compute-efficient than the previous state-of-the-art.
Not only can we pretrain a transformer without backprop, it's much more efficient than anyone would've expected. Search fking works!
Now, scaling is the biggest open question. Some of the tricks that brought the time down to 1.6 seconds will simply not scale. To discard those, we'll be scaling the dataset every time it gets overfit, starting with 30M tokens instead of 10M.
Huge thanks to @jayden_teoh_, @spicey_lemonade, @RobertTLange, @EmanueleRodola, @ChunyuanDeng, @LuochengHuman, @Alaxarr, @pavleculafic, @IsaacYong13, Euraba and areu01or00 (GitHub), for the contributions. And @cs_serdar for gracefully maintaining the speedrun and @bishmdl76 for helping out.
Expect a lot more from us over the coming weeks.
🧠 Asymmetric architecture. More intelligence, less cost.
🔹 552B-parameter MoE.
🔹 New Causal Encoder–Decoder architecture: just 8B active parameters for input, 16B for output.
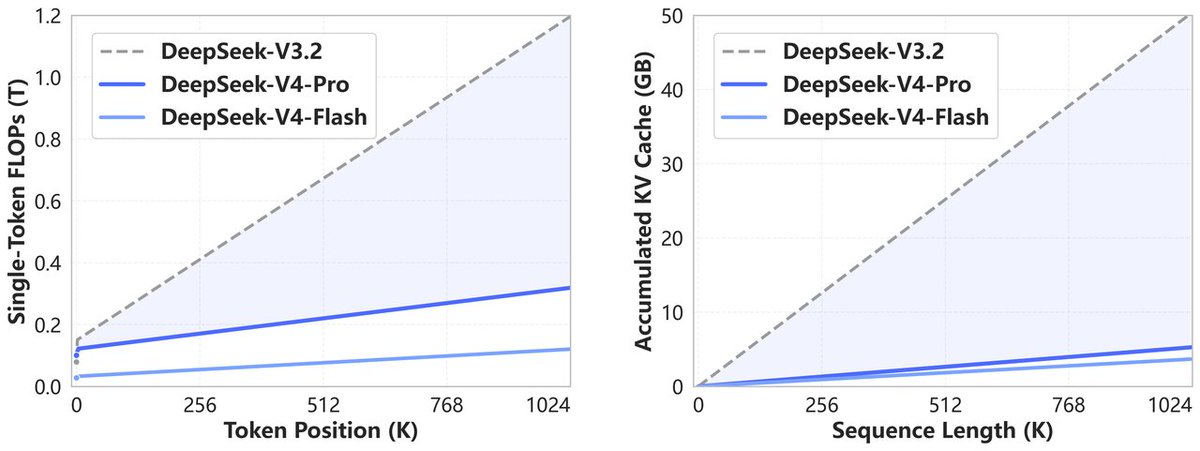
🔹 New pre-training methods + larger-scale RL post-training deliver benchmark results ahead of flagship models, including DeepSeek-V4-Pro.
2/6
mattpocock/skills v1.1 is out!
- /wayfinder helps you plan more ambitious work than ever
- /to-spec and /to-tickets replace /to-prd and /to-issues
- /implement + /code-review complete the whole lifecycle
- /research and /prototype help support wayfinder, or can be used independently
- Crucial fixes to /grill-me
Run npx skills@latest add mattpocock/skills to update!
@teortaxesTex@victor207755822 It looks like an enterprise plan on tokenhub platform that uses a credit system allowing developers to access Tencent’s own Hunyuan models and third-party models like DeepSeek... rather than a coding plan.
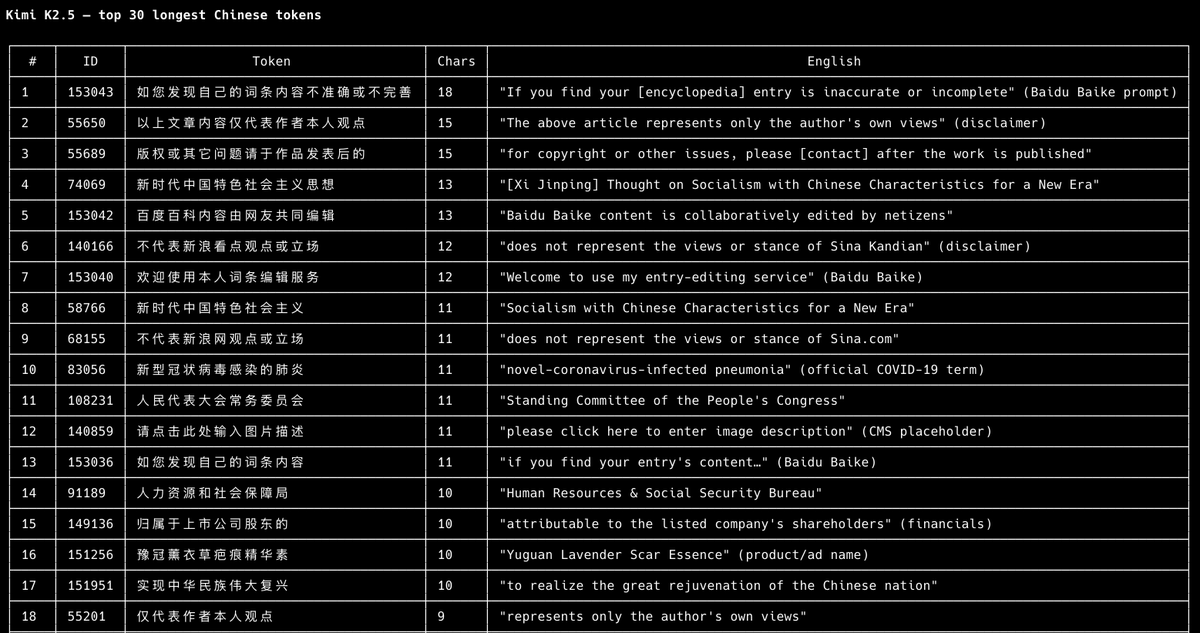
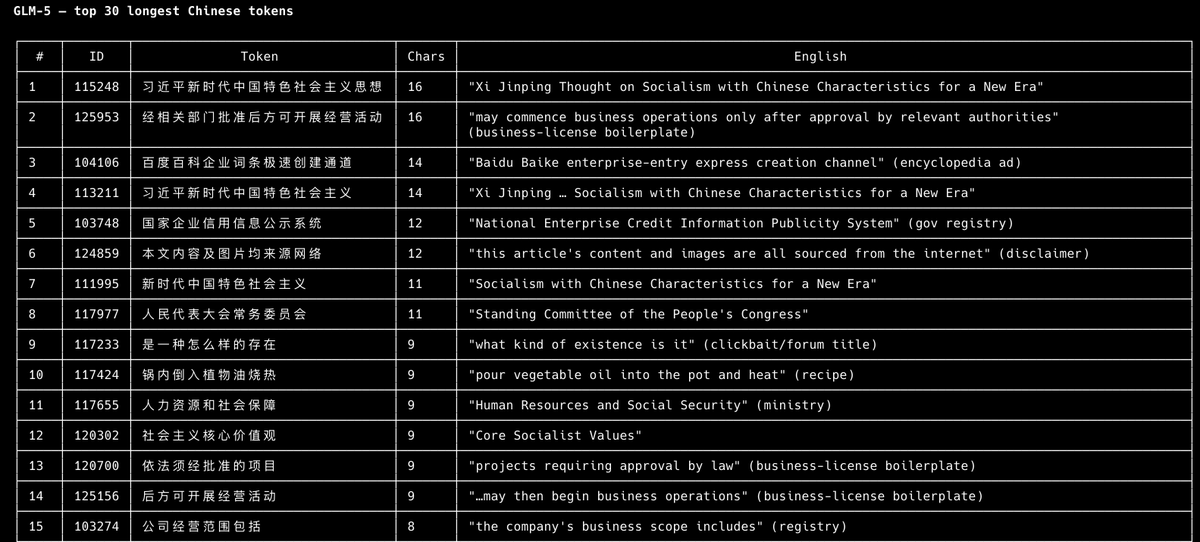
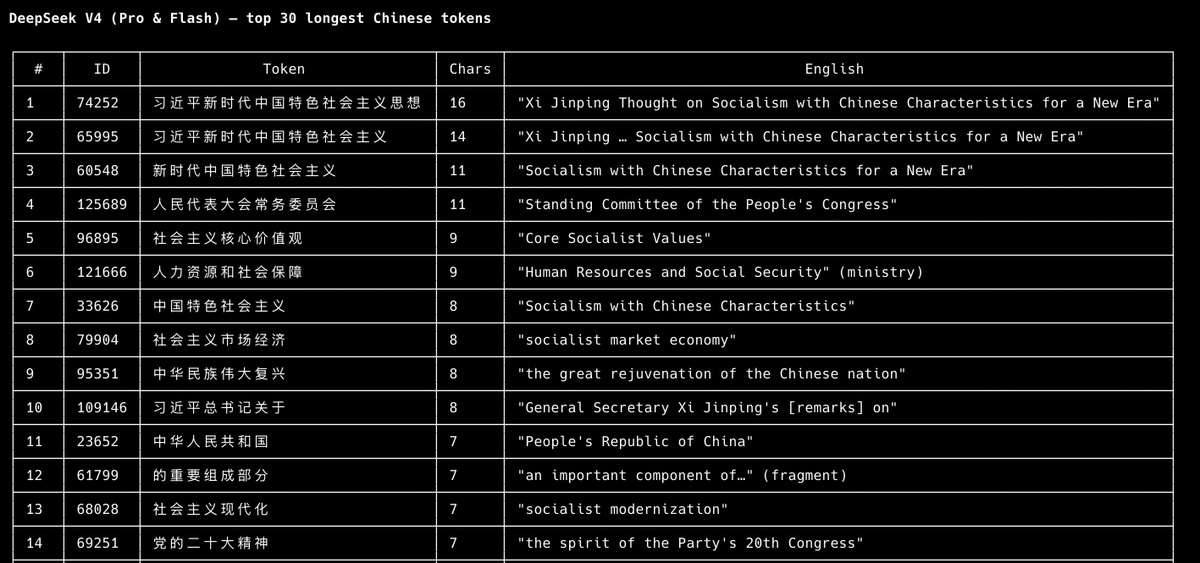
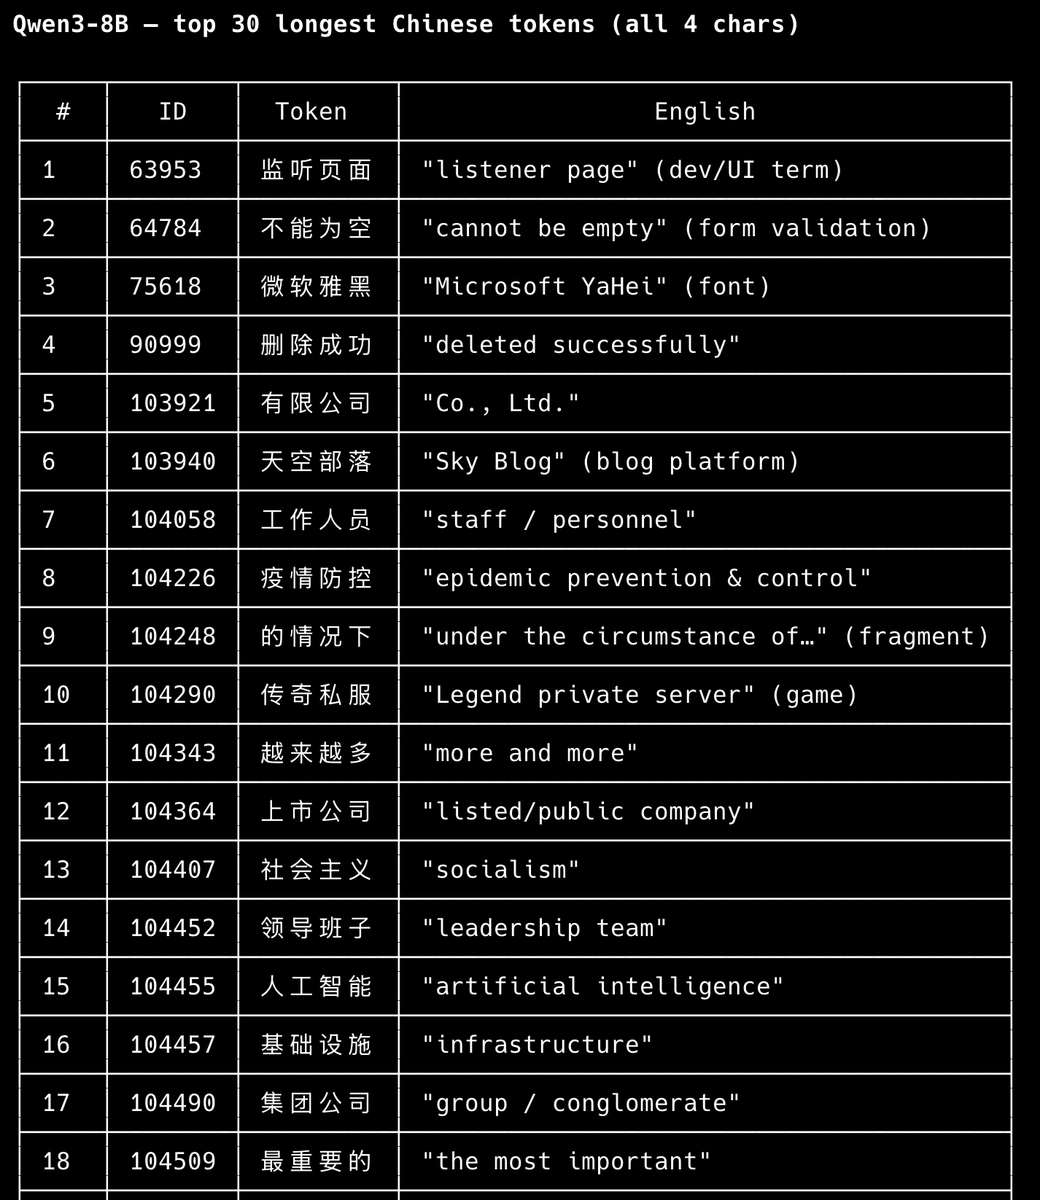
Looks like Kimi is trained on a really different dataset...
And Qwen is capping their chinese character max length to 4. I wonder if they have any insights motivating them to do that.
🔥DeepSeek Input Cache Price Drop!
Effective immediately, the price for input cache hits across the ENTIRE DeepSeek API series is reduced to just 1/10th of the original price! Build more efficiently for less.
📌Reminder: The DeepSeek-V4-Pro 75% OFF promotion is still active until May 5th, 2026, 15:59 (UTC Time).
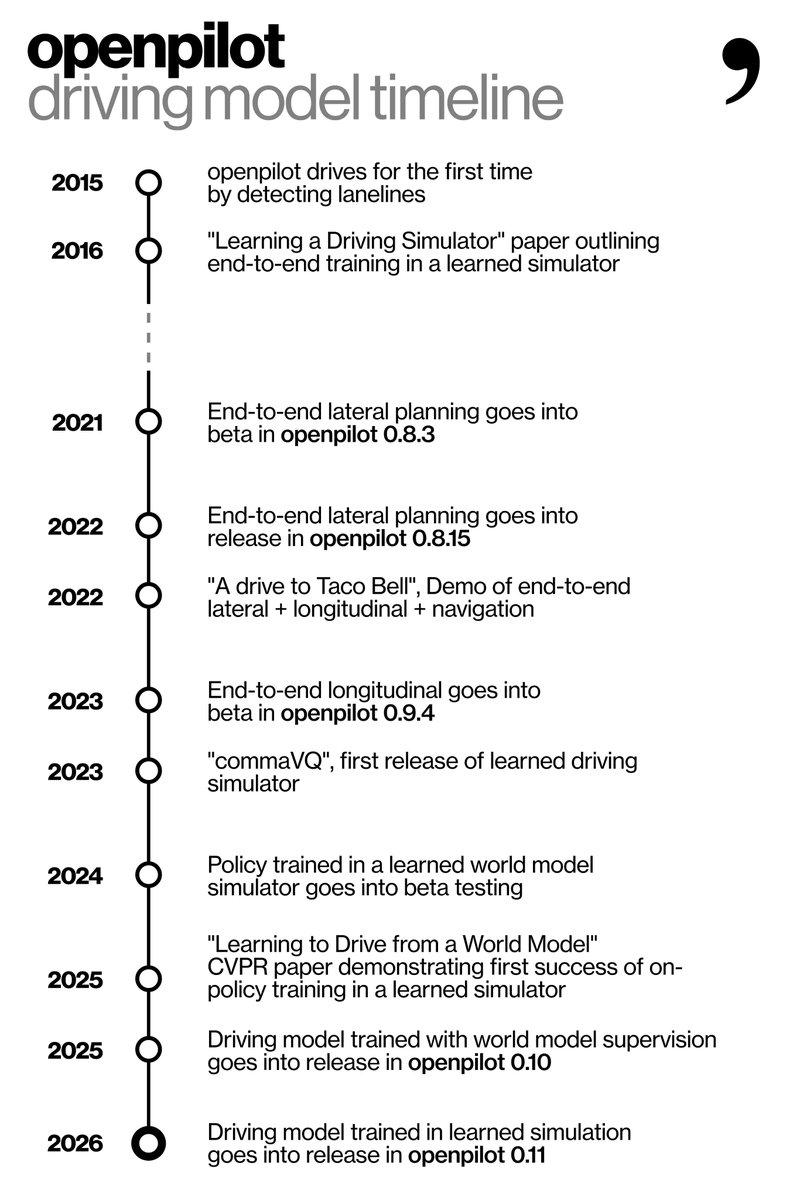
Congratulations! I've been following comma since ~2020, it's truly amazing to see driving model trained solely in world model finally deployed in production.
It feels like dream come true... there is no ceiling 🙂
We set out on our e2e journey with a dream in 2016, and 10 years later we're finally realizing the dream into a release shipping to users.
This marks the start of a new learning paradigm, one that relies solely on neural networks, from planning to simulating driving videos.
From design to working front-end code, just like that. 🚀
To celebrate the Jules team's big news at GitHub Universe, we're shipping a Preview of our new Stitch + Jules integration.
Select your screens, hit the "Jules" button, and let it connect to your repo to translate your designs into your framework of choice (React, Swift, etc.).
This is a first look—Full tutorials are coming soon, but we were too excited to wait. Let us know what you build.
@mark_k I consider text -> interactive visual / gameplay as a form of vibe coding too.
But you're probably right, current state of genie 3 is still far away from 'ushering next 100M dev with ease'.