Over the last two weeks, I’ve been working on the distributed training of a special type of Large Language Model designed for genomics. The goal: to better understand how long-term fibrosis can evolve into liver cancer. In a way, it felt like being back in my PhD days!
@emollick Predicting the next word is harder when you shuffle the tokenized input sentence because the range of possible options increases wrt simple English, this increases model perplexity so it is probably not the best metric to use.
@AndrewYNg@RepZoeLofgren Definitely AI safety is an important concern and we should work hard in model aligment but the bill measures just kill open-source models. Requiring developers the capability for a full shutdown of the model is like saying you can not open-source it.
#summerreading
All of our use cases have published papers and/or beta libraries, time to catch up and check them!
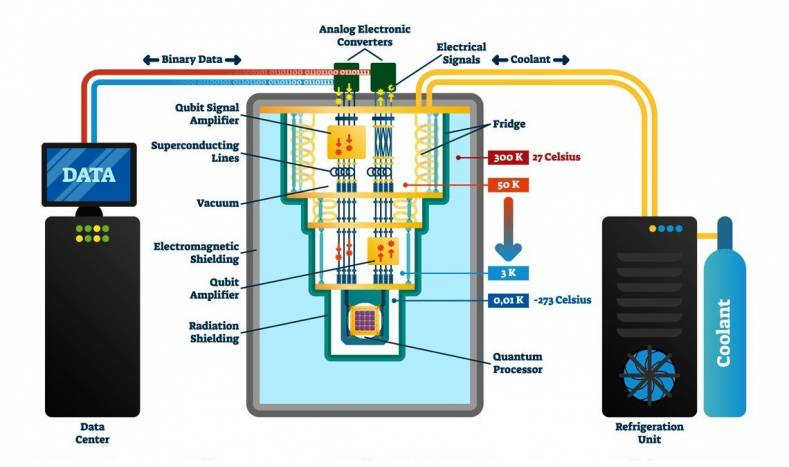
You have an interest in Quantum finance?
Visit their page
@HSBC@CESGA_@UDC_gal
https://t.co/mJyyVIacj1
¿Cómo se simula un universo? ¿Para qué?
Hablamos con el equipo de desarrollo de #Uchuu: la simulación del universo más completa hasta la fecha. Disponible en nube y consulta libre y gratuita.
@javicacheiro@iaa_csic@radio3_rne @knob2001 @CESGA_ 👇🏻
https://t.co/6CPQk8fBzJ
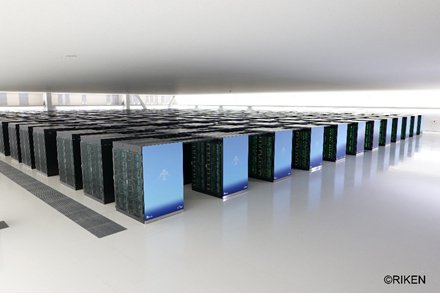
Tranquilidad, que si #Uchuu necesita más procesamiento, #FUGAKU, el hermano japonés de #ATERUI_II está ahí para echar un cable. Es el superordenador más grande y potente del mundo en el ranking actual.
No es un frame de Matrix, pero tiene relación...
Éste es #ATERUI_II, el superordenador japonés que ha sido capaz de hacer la mejor y más completa simulación del universo hasta hoy. Hablamos con dos investigadores de #Uchuu, un ambicioso proyecto internacional.
⏰ @radio3_rne 13H
We are happy to provide access to the Uchuu Halo Catalogs so researchers can use them to improve our understanding of the universe.
If you want to explore the data you can apply for access here:
https://t.co/st6JVkjXfj