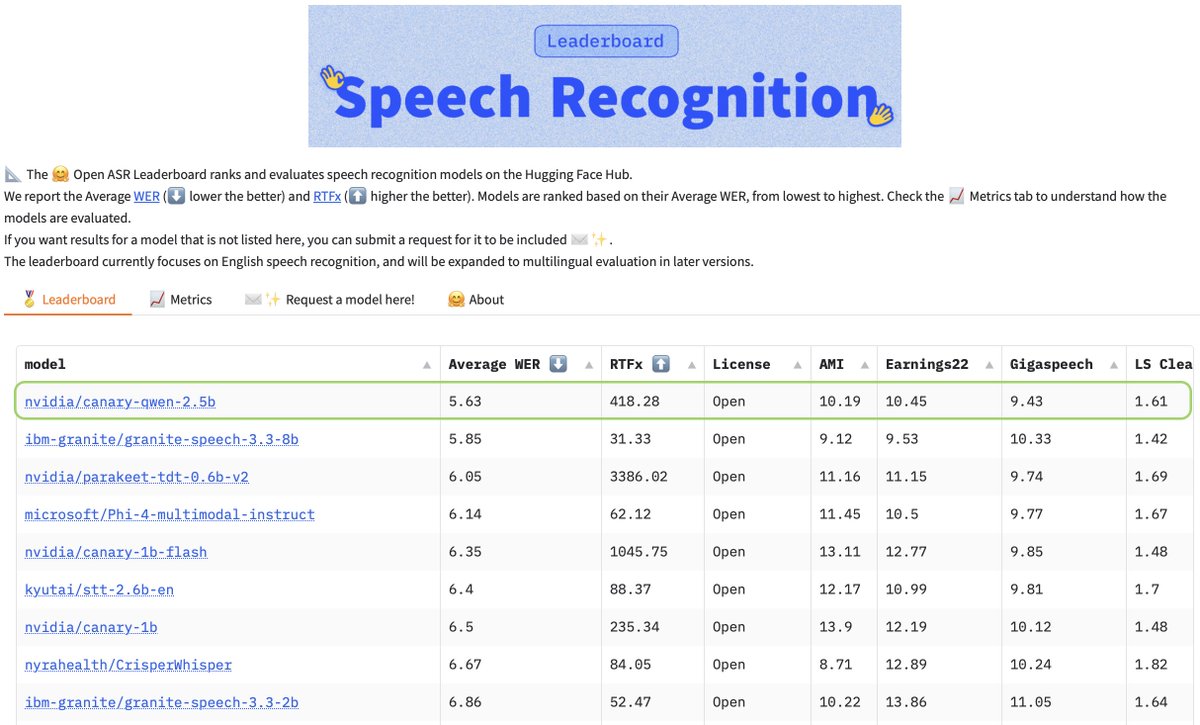
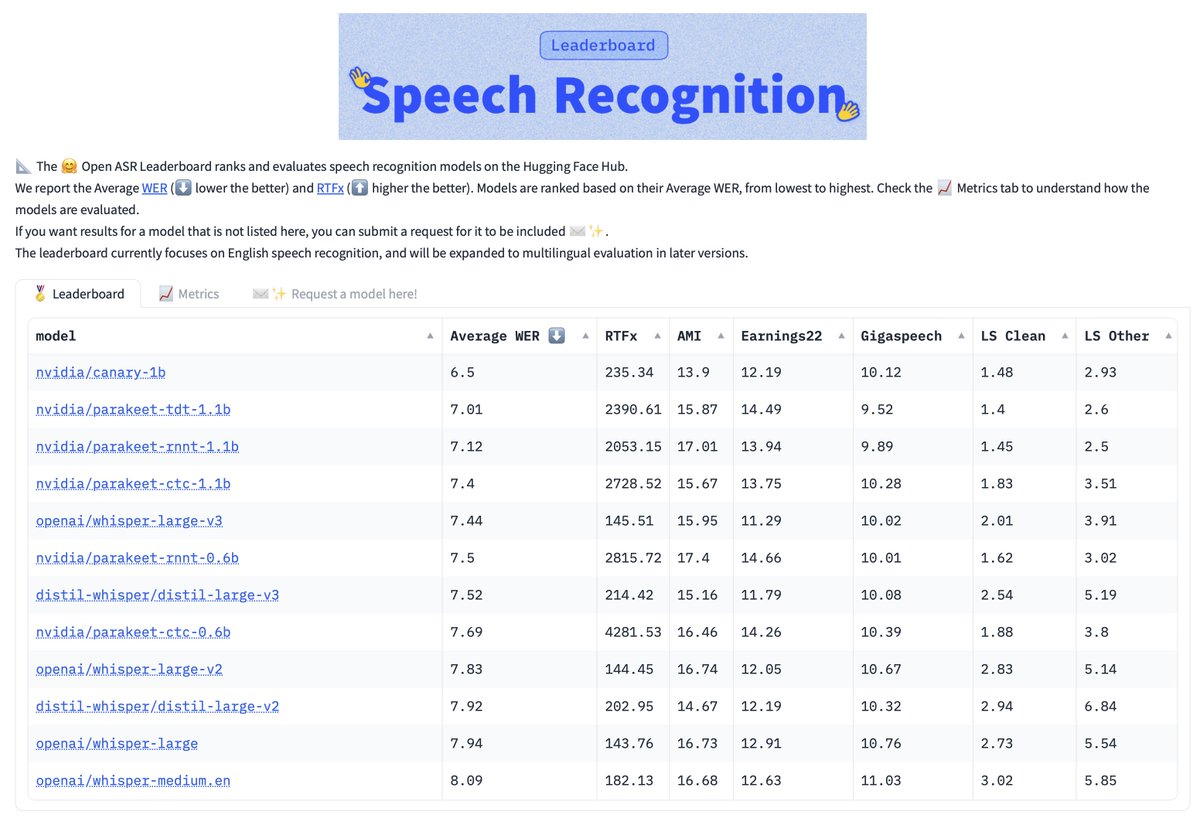
Canary-Qwen-2.5B is our latest, and the first of its kind, ASR model from NVIDIA NeMo team.
🏆 1st place on Open ASR Leaderboard with WER 5.63%
🔥 RTFx=418 on A100 GPU - remarkably fast for its size
💰 CC-BY-4.0 license, commercial-friendly
🌎 English-only
🚀In the future, experienced #remote human #operators will supervise several ⚙️automatized factories
🙌🏽We present 👩🏽💻#OaaS-Operator as a Service
👀Want to know more about these remote operators?
💥Have a look! https://t.co/kO2ABYwo4s
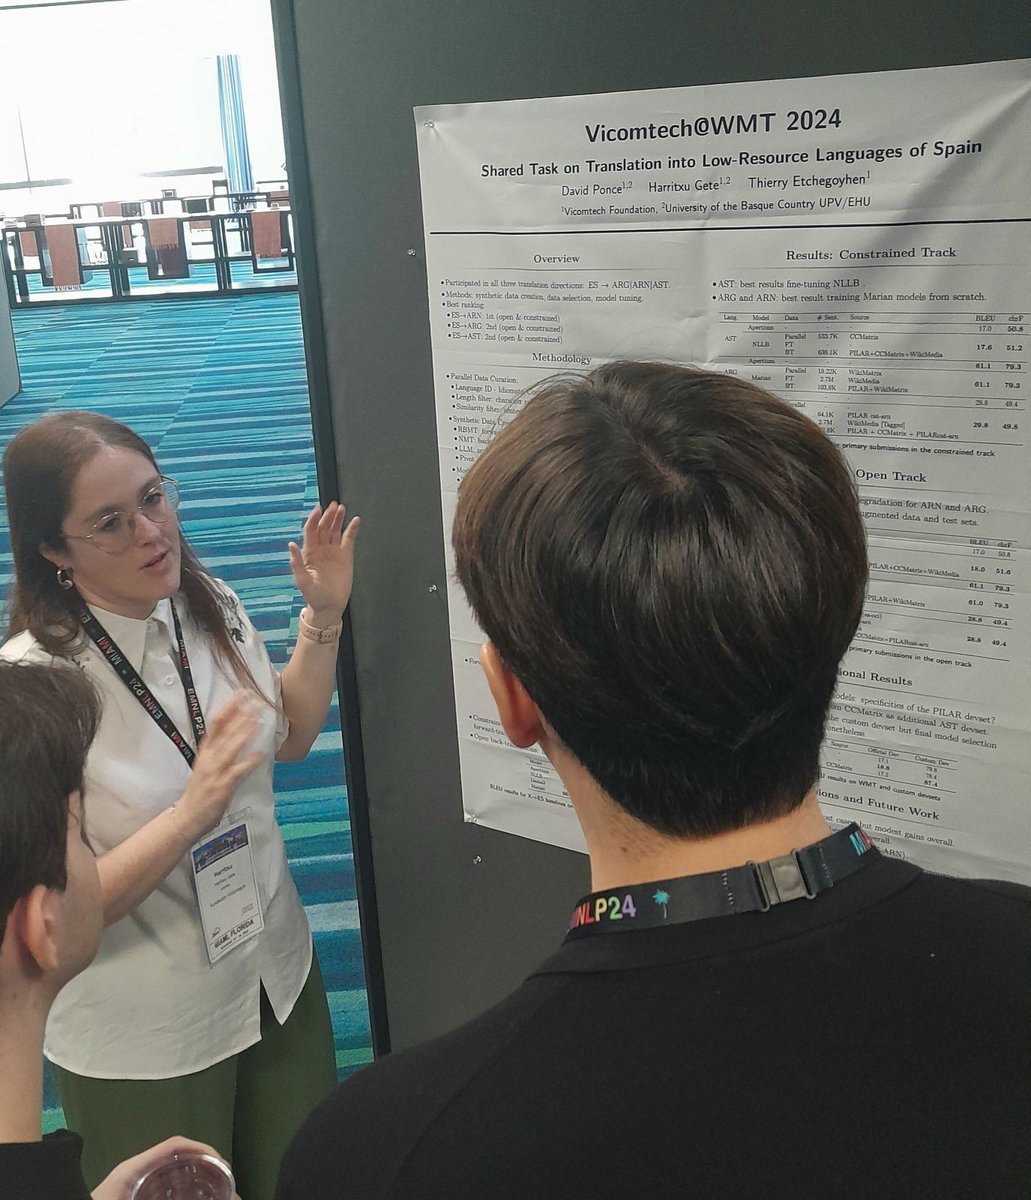
Harritxu Gete was also at #WMT24 Conf. in Miami, within the #EMNLP2024.
She presented "Vicomtech@WMT 2024: Shared Task on Translation into Low-Resource Languages of Spain" co-authored with David Ponce & Dr. Thierry Etchegoyhen and developed within the #Elkartek project ADAPT-IA
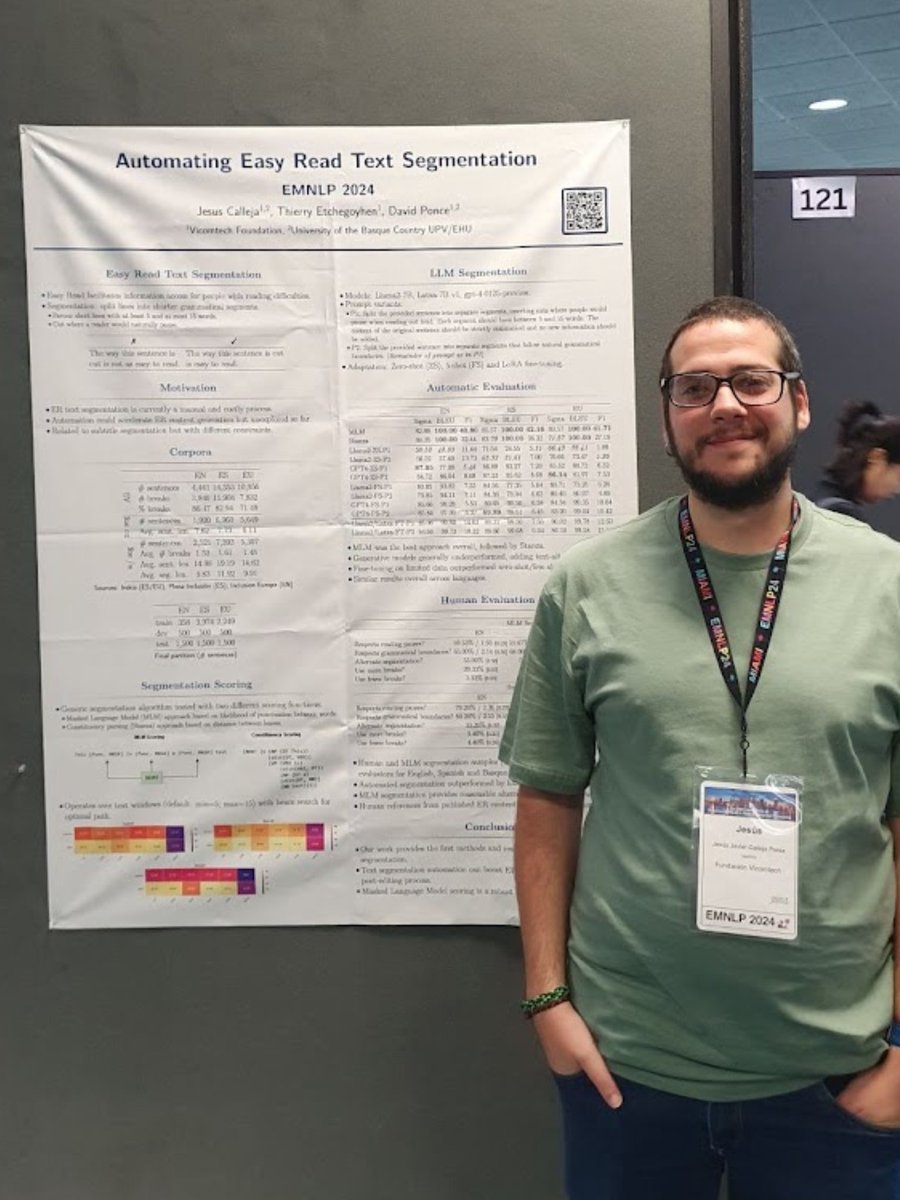
Jesús Calleja & Dr. Thierry Etchegoyhen are attending the #EMNLP2024 Conference in Miami, Nov. 12-16.
They are presenting their work co-authored with David Ponce and developed within the #Hazitek project IRAZ on AI technology for Easy Read text adaptation.
https://t.co/zgADe3kdVQ
Our colleagues Harritxu Gete and Dr. Thierry Etchegoyhen are at #EMNLP2024 Conference in Miami.
They are presenting their work "Does Context Help Mitigate Gender Bias in Neural Machine Translation?" developed within the #Elkartek project ADAPT-IA
https://t.co/QjgZn0wf4z
We fkn did it! Whisper Large v3 Turbo is in Transformers! 🔥
Drop-in replacement to Large-v3 - 809M parameters, 8x faster AND multilingual ⚡
> Uses 4 decoder layers as compared to 32 (large v3)
> Supports both Timestamps (both Word and Chunk)
> Compatible with Flash Attention 2
We're running benchmarks at the moment, will report those soon. Try it out now on the space below 🐐
P.S. Sorry for the rushed audio 🙈
More details on Whisper Turbo by @OpenAI :
> Whisper 'large-v3-turbo' (turbo) has 4 decoder layers, optimized from the original 32 layers
> Fine-tuned on multilingual transcription data, turbo performs similarly to large-v2 across languages
> Thai and Cantonese show slightly lower performance compared to other languages
> FLEURS dataset yields better results due to cleaner recordings
> Turbo achieves a 20% error rate or less on specific languages in Common Voice 15 and FLEURS datasets
Kudos to @OpenAI for such a brilliant release! ❤️
Open Source AI was off the charts last week:
Nvidia released Nemotron 51B - 220% faster and can handle 400% more workload than L3.1 70B & permissively licensed
Meta dropped Llama 3.2 - Llama Vision 90B & 11B and tiny llamas (3B & 1B) for on-device usage, multilingual & with 128K context
Molmo by Allen AI - Open source SoTA Multimodal (Vision) Language model, beating Claude 3.5 Sonnet, GPT4V and comparable to GPT4o
Nvidia NeMo got a new update making it 10x faster & 4.5x more cost effective and blows OpenAI Whisper out of the water
I’m sure I missed some gems, what did I miss? Pumped to start a new week!
Behold: NeMo ASR now runs easily 2000-6000 faster than realtime (RTFx) on @nvidia GPU.
We developed a series of optimizations to make RNN-T, TDT, and CTC models go brrrrrrr!🔥
In addition to topping the HF Open ASR Leaderboard they are now fast and cheap. All in pure PyTorch!
Santiago Andrés Moreno of the Speech and Natural Language Technologies team participated at 27th Int. Conf. on Text, Speech and Dialogue #TSDConference and presented "Stream-Based Active Learning for Speech Emotion Recognition via Hybrid Data Selection and Continuous Learning"👏
End to End Speech models are on fire - LLAMA-OMNI 8B - Apache licensed! 🔥
> Speech Encoder - Whisper Large v3
> LLM backbone - Llama 3.1 8B Instruct
> Speech Decoder - HuBERT (UnitY)
> Simultaneously generate Speech + Text
> Less than 250 ms latency
> Trained in less than 3 days on 4x GPUs
> Used 200K instruct pairs
> Model checkpoints on the Hub 🤗
> Space incoming!
GG! I'm here for this trend! 🐐
💥Dr. Juan Manuel Martín Doñas, researcher of #SpeechProcessing technology line, was at #INTERSPEECH2024 presenting "Exploring Self-supervised Embeddings and Synthetic Data Augmentation for Robust Audio Deepfake Detection"
@ISCAInterspeech
``Enhancing Large Language Model-based Speech Recognition by Contextualization for Rare and Ambiguous Words,'' Kento Nozawa, Takashi Masuko, Toru Taniguchi, https://t.co/aXro0NGFYY
Think you can tell if a social media account is a bot? What about as AI gets better?
A new paper—co-authored with researchers from ~20 orgs, & my OpenAI teammates Zo�� Hitzig and David Schnurr—asks this question: What are AI-proof ways to tell who’s real online? (1/n)
remember the GPT Store?
a few months ago there was some excitement around "prompt app stores", where gifted prompt-writers could make money by writing magical system prompts and packaging them as "apps"
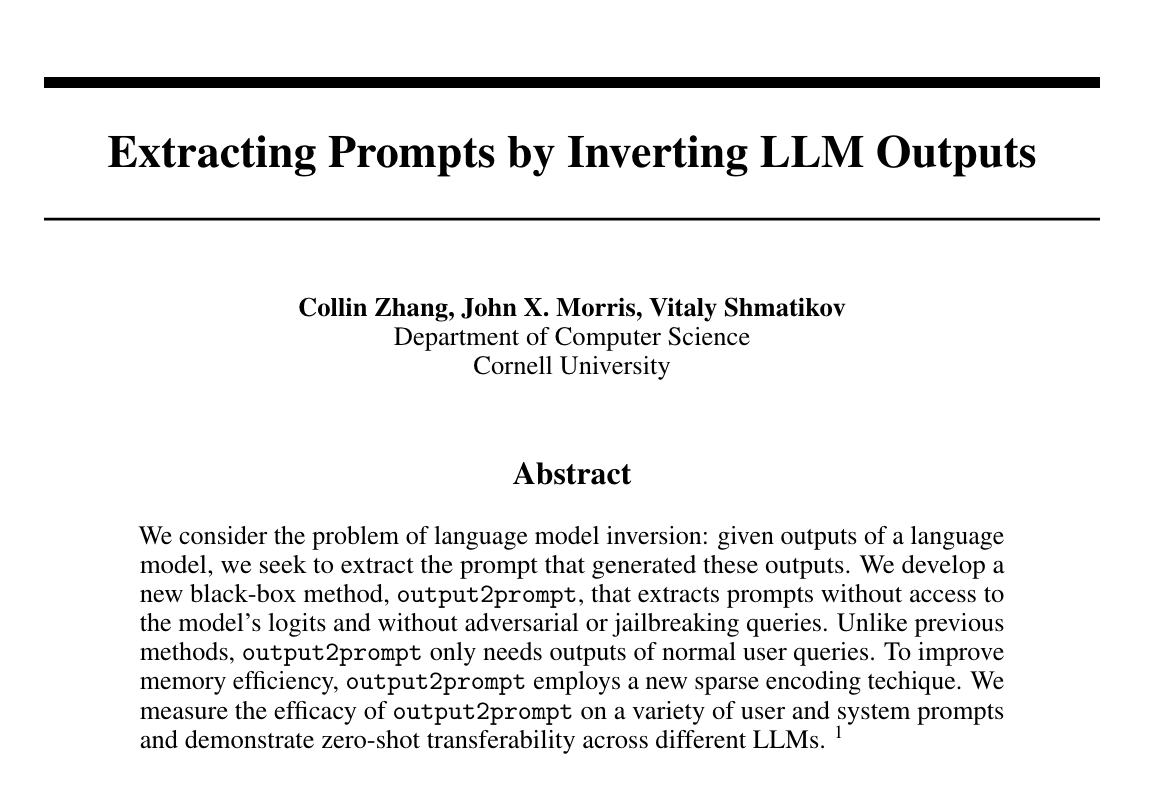
our new research shows these prompts can be easily recovered by just asking a few questions to the LLM and using its outputs to infer the hidden prompt
Introducing torchchat 🔥
A lightweight library to run LLMs locally across mobile, desktop and laptops powered by PyTorch.
Learn more: https://t.co/MhRTSxPsPg
#llms#mobilellms#localai#pytorchllm#edge#ondeviceai
Fuck yeah! Moshi by @kyutai_labs just owned the stage! 🇪🇺/acc.
Architecture
1. 7B Multimodal LM (speech in, speech out)
2. 2 channel I/O - Streaming LM constantly generates text tokens as well as audio codecs (tunable)
3. Achieves 160ms latency (with a Real-Time Factor of 2)
4. The base text language model is a 7B (trained from scratch) - Helium 7B
5. Helium 7B is then jointly trained on w/ text and audio codecs
6. Speech codec is based on a Mimi (their inhouse audio compression model)
7. Mimi is a VQ-VAE capable of 300x compression factor - trained on both semantic and acoustic information
8. Text to Speech Engine supports 70 different emotions and styles like whispering, accents, personas, etc
Training/ RLHF
1. The model is fine-tuned on 100K transcripts generated by Helium itself.
2. These transcripts are highly detailed, heavily annotated with emotion and style, and conversational.
3. Text to Speech Engine is further fine-tuned on 20 hours of audio recorded by Alice and licensed.
4. The model can be fine-tuned with less than 30 minutes of audio.
5. Safety: Generated audio is watermarked (possibly w/ audioseal) & generated audios are indexed in a database
6. Trained on Scaleway cluster of 1000 H100 GPUs
Inference
1. The deployed demo model is capable of bs=2 at 24GB VRAM (hosted on Scaleway and Hugging Face)
2. Model is capable of 4-bit and 8-bit quantisation
3. Works across backends - CUDA, Metal, CPU
4. Inference code optimised with Rust
5. Further savings to be made with better KV Caching, prompt caching, etc.
Future plans
1. Short-term technical report and open model releases.
2. Open model releases would include the inference codebase, the 7B model, the audio codec and the full optimised stack.
3. Scale the model/ refine based on feedback except Moshi 1.1, 1.2, 2.0
4. License as permissive as they can be (yet to be decided)
Just 8 team members put all of this together! 🔥
After using it IRL, it feels magical to have such a quick response. It opens so many avenues: research assistance, brainstorming/Steelman discussion points, language learning, and more importantly, it's on-device with the flexibility to use it however you want!
Hats off to Kyutai and the team for shipping a version that *just* works and is out in public 🫡
Your turn, Open AI! ;)