Last week’s Microsoft 365 outage was the first of many, and the next ones will be worse.
The way companies depend on their data has changed, and the way most of them protect it was built for a different time. https://t.co/BiGMmo2wmY
In the last two days, 4,837 hijacked GitHub accounts opened pull requests in more than 61,000 repositories.
In at least 1,835 of them a script ran inside CI, stole the secrets and covered its tracks, sometimes within seven seconds.
Last week, we launched Eon Yukon, our new data engine for the AI era, and built GitHub Pulse to demonstrate its ability to process massive streams of GitHub activity in real time.
When the attack started, we realized we already had the data to track it.
So we built a live attack tracker.
Check whether your repos or the open-source projects you depend on were targeted: https://t.co/Dk0aHXPAh3
Agents don't query data a couple of times a day. They query it constantly and need the latest event.
Eon Yukon makes data ready the moment it lands, in Iceberg and in your own storage.
Any compatible engine can read it.
Eon is launching Yukon which is a serverless data engine built to help AI agents work with enterprise data.
As more agents start accessing that data it creates another source of cloud storage and compute demand for $AMZN and $GOOGL.
EON JUST LAUNCHED THE DATA ENGINE FOR AI AGENTS
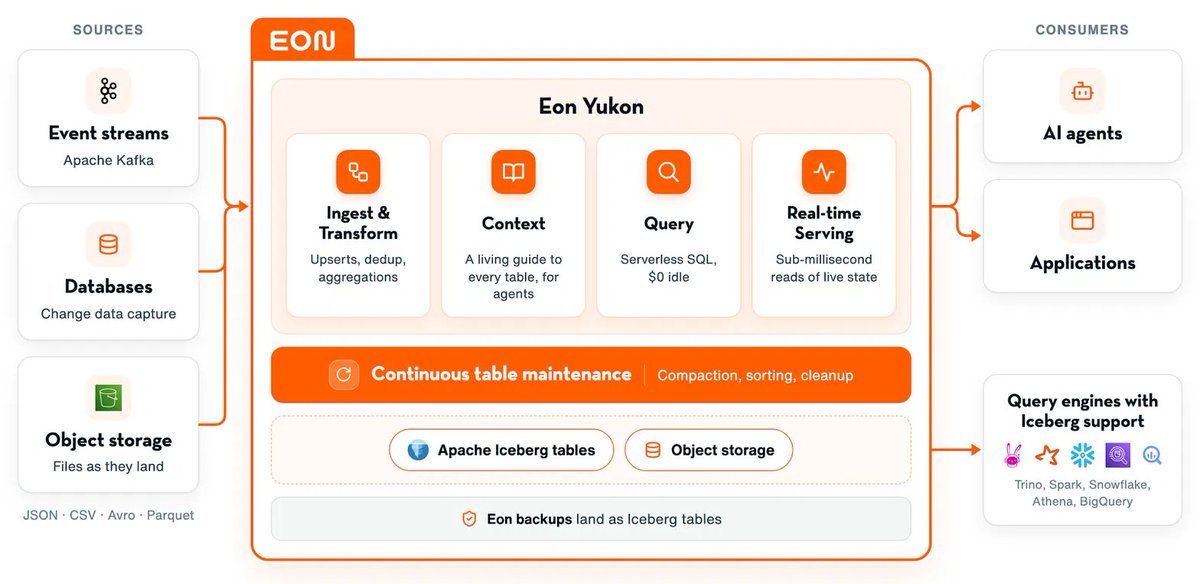
It's called Eon Yukon and this image sums it up.
In a single engine:
→ Ingest and transform
→ Context for agents
→ Serverless SQL queries
→ Sub-millisecond reads
Tables maintain themselves in open Iceberg, ready for agents, apps or any compatible engine.
Per its public benchmark: 4x less compute than Spark and 7x less than Flink.
AI agents are pushing traditional data infrastructure to its limits as they demand fresher data and more frequent queries.
Eon Yukon is built to handle this growing demand with less computing power and greater efficiency.
@OfirEhrlich@Eon_io_
Data stacks were built for humans running a few queries a day. Agents hit your data nonstop and want the newest row plus the full history every time.
Eon Yukon is the engine built for that. It ingests, cleans and maintains data as it arrives, in open Iceberg tables in your own bucket.
It uses 4x less compute than Spark and 7x less than Flink and the benchmark is public.
Your company's data systems were built for people who run a few reports a day and go home at six. The AI agent it shipped last week is still hammering that data right now, and it wants the newest row plus every row before it, every single time.
PMs rolling out agents keep telling me the same thing: every new agent needed its own pipeline, so the infrastructure bill climbed with each launch and the engineers who were supposed to build features spent their weeks keeping plumbing alive. Spark and Flink, the two workhorses under most of that plumbing, came out of university labs around 2010, long before anyone pointed an agent at them.
Eon just published a number on how badly that fit is breaking. At 1 million events per second, its new engine, Eon Yukon, ran on roughly a quarter of Spark's compute and a seventh of Flink's at the same freshness, in a benchmark it put on a public repo so anyone can rerun it.
Two details under the headline matter more than the ratio. The data ends up as open Iceberg tables in your own storage, so the engine has to keep earning the workload on cost and freshness every month. And it builds a description and stats for each table while ingesting, which is what lets an agent ask what changed last week without reading the whole table.
Data infrastructure is about to get graded on freshness per dollar. Any stack that needs a new pipeline per agent is going to have a rough time on that report card.
AI agents are about to DDoS your own data infrastructure. And YOU get to pay the cloud bill.
Think about it. Thousands of nonstop queries, fresh data, full history, and pipelines that were never built for this kind of abuse.
Eon just launched Yukon to tackle exactly that.
It ingests, transforms, and maintains data continuously in open Iceberg tables, with fresh context available to agents through MCP.
The crazy part?
At 1M events/sec, Eon's public benchmark shows:
→ ~4x less compute than Spark
→ ~7x less compute than Flink
→ Same data freshness
And the benchmark is reproducible. AI agents are getting faster. The infrastructure feeding them better keep up.
@heysatya_@Eon_io_ Agent outputs are only as strong as the inputs. Put 🗑️ in, get 🗑️ out. Eon Yukon give your agents that fresh, context-rich good good ✨🧑🍳💋