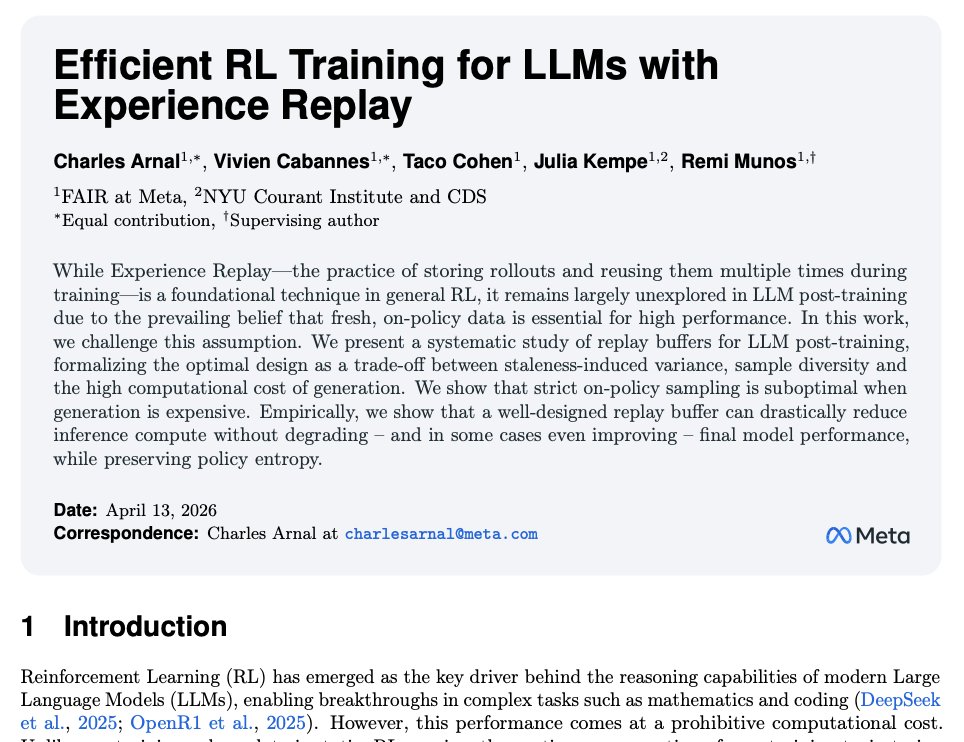
(1/9) Experience replay can cut LLM RL training compute by up to ~40% (without hurting final accuracy—and sometimes improving it).
Paper: https://t.co/6YcAd6EBSy
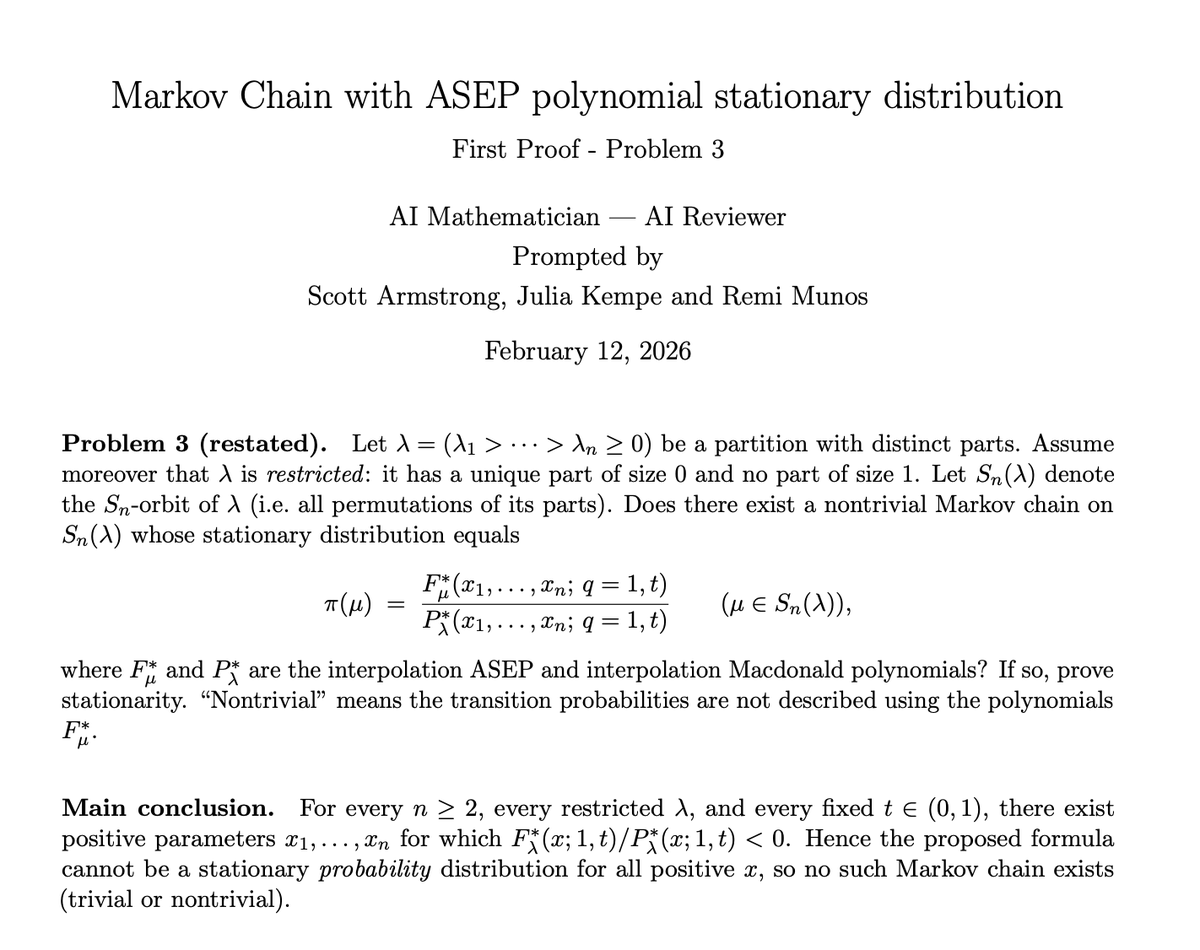
1/ #1stProof. Our second installment — this time tackling Problem 3, with @scottnarmstrong and @MunosRemi
Also check out our takeaways ��� and a short “Humor from your bot” interlude — below.