A streaming event bus whose routing, subscription and consumption are decided by a probabilistic judge. The reference judge is TypeSafe AI's Jev (System One) model: send it a payload and a set of typed questions, get back calibrated probabilities instead of prose.
https://t.co/t6j0H95nEL
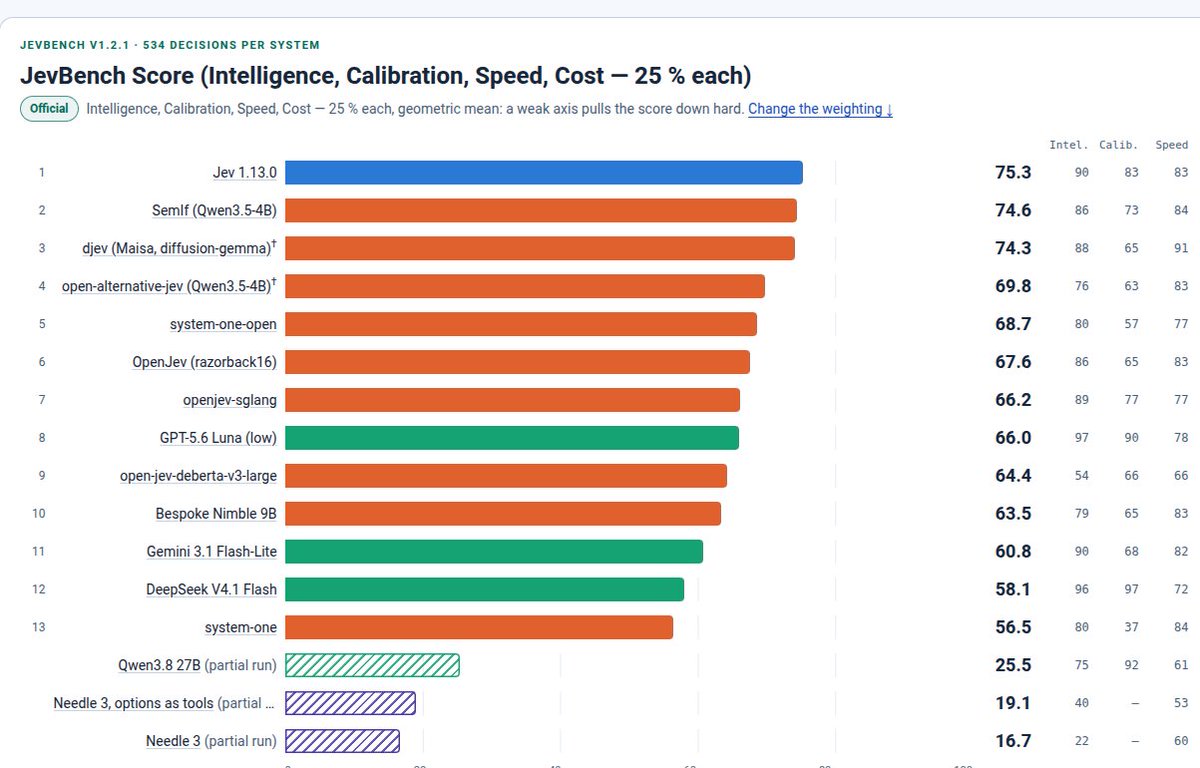
A new benchmark called JevBench just dropped.
for models whose output is a bounded software decision rather than open-ended prose and follows TypeSafe’s 15 Sept release of Jev, which takes application state plus fixed choices and returns a typed answer with probabilities instead of prose.
This benchmark's score deliberately combines Intelligence, Calibration, Speed and Cost because deployment can fail even when raw accuracy is high.
e.g. GPT-5.6 Luna records substantially higher hard-case accuracy than Jev 1.13.0, yet Jev leads the composite because the benchmark also prices latency, calibration and cost.
The geometric mean prevents exceptional performance on 1 axis from fully compensating for a weak one.
The result is evidence about a narrow typed-decision workload, not evidence that Jev is generally more capable than GPT-5.6 Luna.