First place in The Search goes to “Sambal!” by Brillian Fairiandi, taking home $50,000. Congratulations!
Thank you to everyone who entered, and a big congrats to all eleven who placed.
See the full list here: https://t.co/oMMv1CsWfr
BREAKING 🔥: A hidden Claude Mythos 5.5 mention has been spotted on the official Anthropic website.
> "Claude Mythos 5.5 - Our most capable model class for cybersecurity and biology research."
Should we expect Mythos 5.5 for cyber defense next week? Fable 5.5 may come along as well (speculation).
Soon? 👀
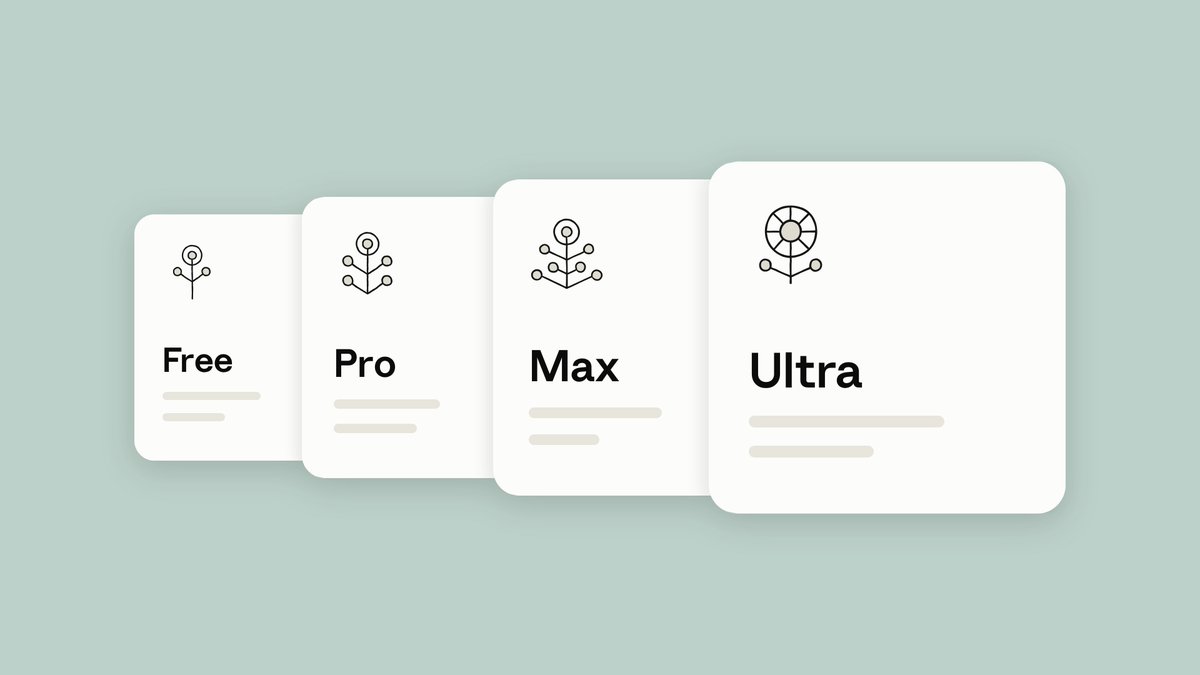
We’re renaming our Max plans:
Max 5x → Max
Max 20x → Ultra
Max is still $100/month, and Ultra is still $200. If you’re a subscriber, there’s nothing you need to do.
We’re also removing the 5-hour limit for verified Ultra accounts, starting today with most existing subscribers. Newer accounts keep a temporary limit until they’re verified, which helps us prevent fraud and abuse. You'll get an email when it's removed.
Weekly limits remain unchanged. View our plans here: https://t.co/niRpyGF5Me
GPT-6.1 Terra: delivering fast and capable computer use at a lower price.
GPT-6.1 Terra understands what’s on screen, takes action across apps, writes naturally, and is a more capable model for your whole workday with the efficiency to take on more of it.
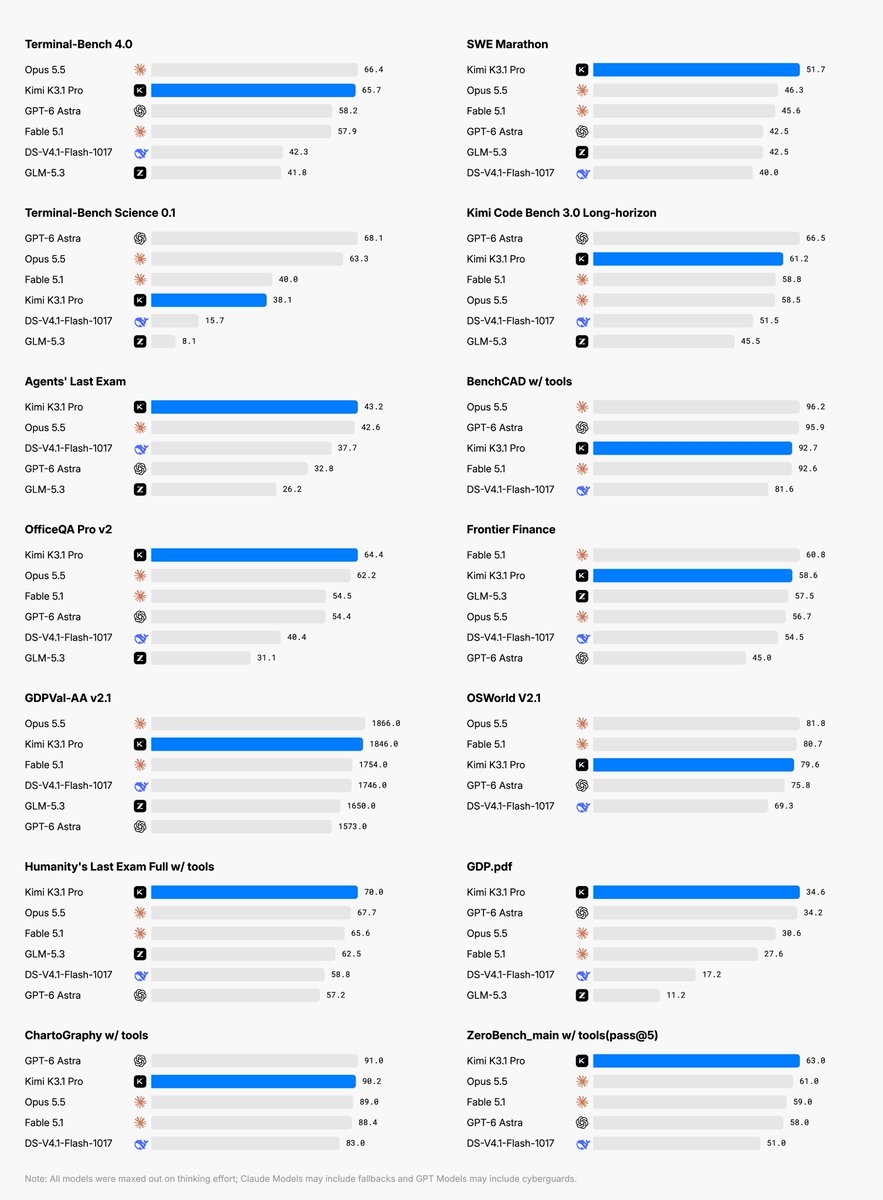
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
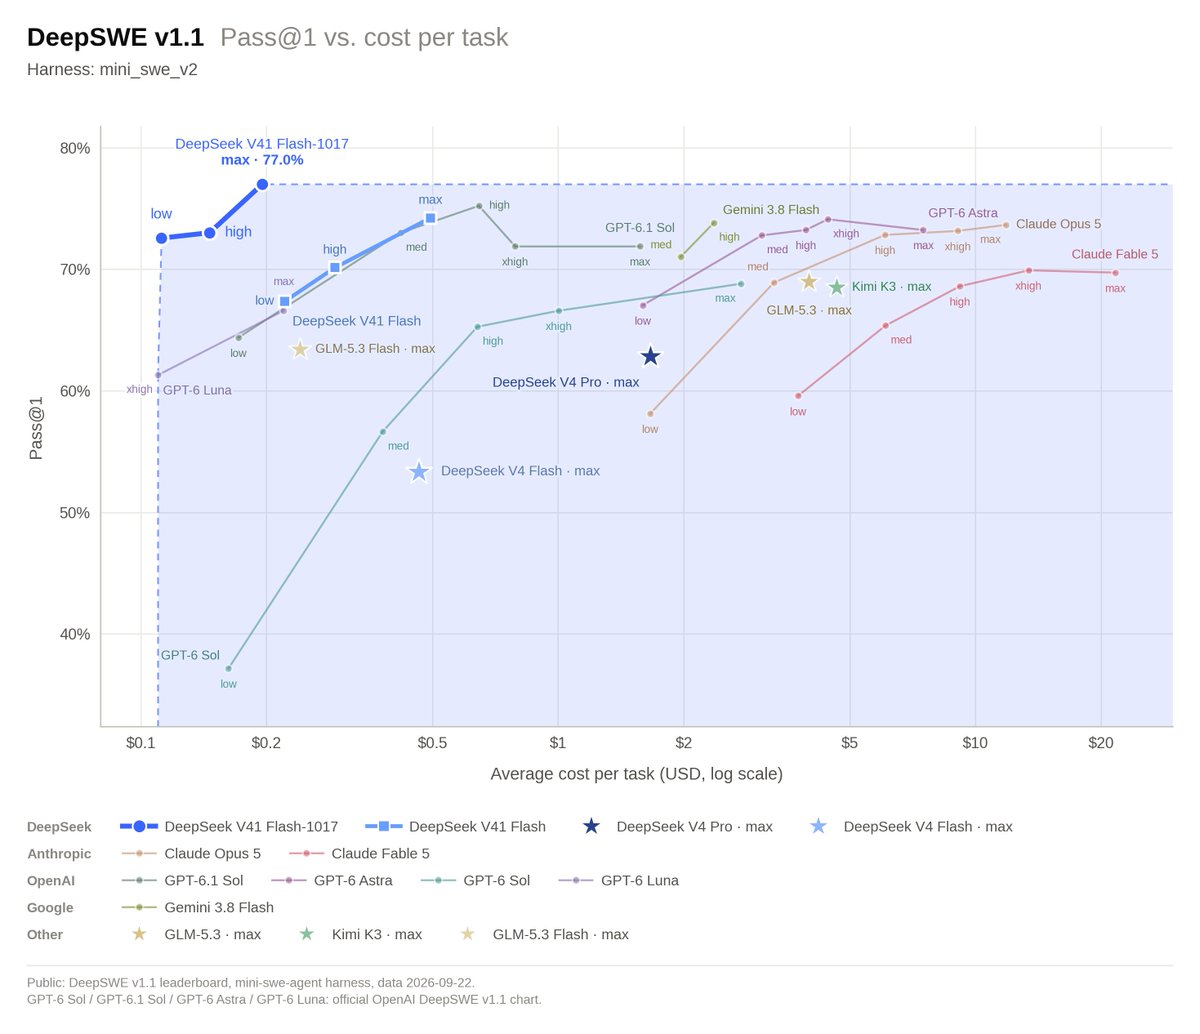
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
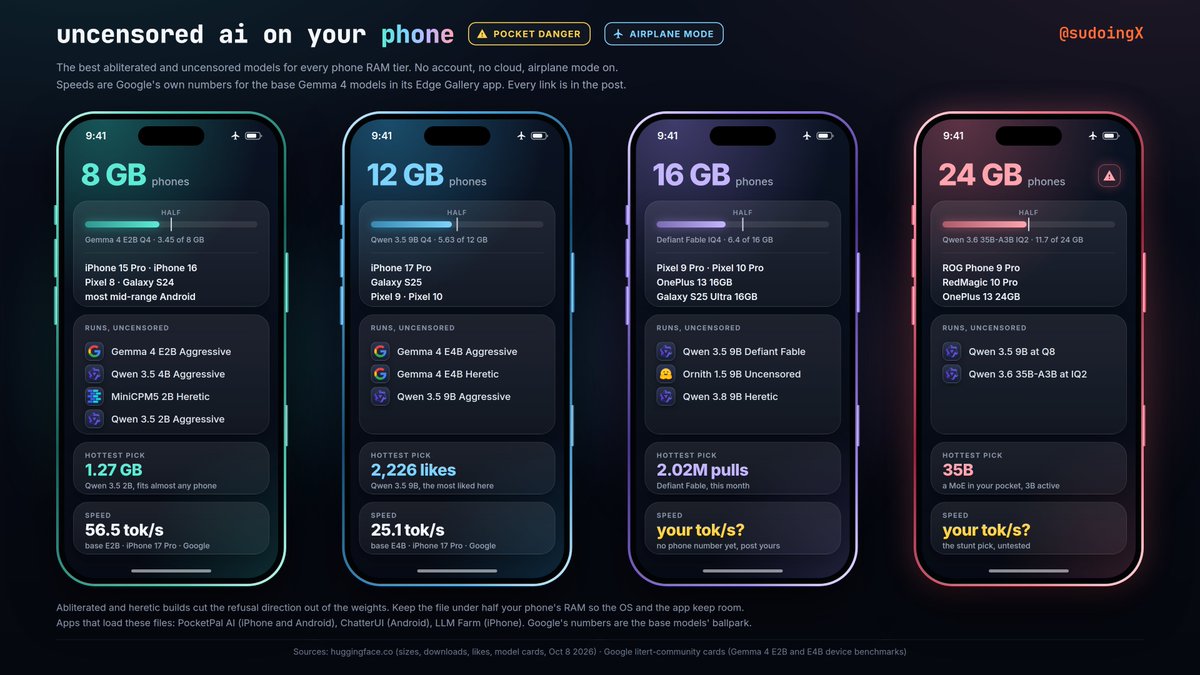
here are the best uncensored ai models that run on a phone locally 🚨
i went through every uncensored and abliterated model small enough for a phone and picked the best for each ram tier.
━━━━━━━━━━━━━━━━━━━━
8gb phones · iphone 15 pro, iphone 16, pixel 8, galaxy s24 and most mid-range android · google's own numbers put the base gemma 4 e2b at 56.5 tok/s on an iphone 17 pro and 52.1 tok/s on a galaxy s26 ultra
> 1. gemma 4 e2b aggressive, q4 3.45gb, 0 refusals out of 465, 1.08m downloads all time
https://t.co/5wAcZ13u6A
> 2. qwen 3.5 4b aggressive, q4 2.71gb, 0 refusals out of 465, 602 likes
https://t.co/EKIBcAlqF5
> 3. minicpm5 2b heretic, openbmb's phone model, q4 1.56gb, refusals 99 to 5 out of 100
https://t.co/5TmRyUG20a
> 4. qwen 3.5 2b aggressive, q4 1.27gb, fits almost any phone
https://t.co/uXwjNV4qHi
���━━━━━━━━━━━━━━━━━━━
12gb phones · iphone 17 pro, galaxy s25, pixel 9, pixel 10 · google's numbers put the base gemma 4 e4b at 25.1 tok/s on an iphone 17 pro and 22.1 tok/s on a galaxy s26 ultra
> 1. gemma 4 e4b aggressive, q4 5.34gb, 0 refusals out of 465, 1.44m downloads this month, 1,330 likes
https://t.co/FEoMLYI8pK
> 2. gemma 4 e4b heretic, q4 5.34gb, refusals 99 to 3 out of 100
https://t.co/zRMRq9Twhr
> 3. qwen 3.5 9b aggressive, q4 5.63gb, 0 refusals out of 465, 2,226 likes, the most liked on this list
https://t.co/I5BgPS5MG4
━━━━━━━━━━━━━━━━━━━━
16gb phones · pixel 9 pro, pixel 10 pro, oneplus 13 16gb, galaxy s25 ultra 16gb
> 1. qwen 3.5 9b defiant fable heretic, iq4 6.4gb, refusals 100 to 6 out of 100, 2.02m downloads this month, the most pulled small uncensored model on hugging face
https://t.co/vniKRGHpvo
> 2. ornith 1.5 9b uncensored, q4 5.63gb, 1.34m downloads this month
https://t.co/F0QJjGLw85
> 3. qwen 3.8 9b heretic, q4 5.63gb, 104k downloads this month
https://t.co/8nxFsI8V9B
━━━━━━━━━━━━━━━━━━━━
24gb phones, pocket red alert 🚨 · rog phone 9 pro, red magic 10 pro, oneplus 13 24gb
> 1. qwen 3.5 9b aggressive at q8, 9.53gb, near lossless
https://t.co/I5BgPS5MG4
> 2. qwen 3.6 35b a3b aggressive at iq2_m, 11.7gb, a 35b moe with 3b active per token in your pocket, the stunt pick, i haven't run it on a phone
https://t.co/uf8PViAIy6
━━━━━━━━━━━━━━━━━━━━
apps that load these: pocketpal ai on iphone and android, chatterui on android, llm farm on iphone. speeds are google's own for the base models in its edge gallery app, the uncensored files run in llama.cpp apps like pocketpal, so treat them as the ballpark, and refusal numbers are each releaser's own test
pull it with pocketpal on iphone or android straight from hugging face, pick the file that sits under half your phone's ram so the os and the app keep room, then flip airplane mode on and ask it anything, every answer comes from the chip in your hand and stays there.
bookmark this so it's here when you upgrade your phone, and drop your phone and tok/s in the replies, i have no phone numbers yet for the 16gb and 24gb picks and i want to see what yours does 📱
Our SynthID technology lets you easily verify if an image, video, or audio file is AI-generated, and today we’re expanding access.
Now anyone can go to https://t.co/qyCNRb6dOv to check files for a SynthID watermark — whether they were generated by us or industry partners like @OpenAI, @nvidia, Kakao, and, coming soon, @Apple.
To date, we’ve watermarked 180 billion images and videos and more than 240,000 years of audio content, regularly handling 1 million verification requests daily.
This new portal joins our built-in verification features already live in Search, @GeminiApp, and @googlechrome.
SynthID Detector is now available to everyone. 🌐
Check whether online content was generated using @GoogleAI, or with tools from our industry partners – including @OpenAI, @NVIDIA, Kakao and coming soon, @Apple.
Try it out → https://t.co/cPW2aNnqr6
Cloud sessions are officially available and out of research preview! They let you keep Claude Code working, even when your laptop is closed.
Existing subscribers get a one-time credit to try them: $100 on Pro, $250 on Max.
Colab is now part of Google AI plans! Subscribers get priority access to faster accelerators and more powerful machines, Ultra users also get access to longer running background execution and Premium GPU access.
Learn more here:
https://t.co/zeUeqjVOVg
Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.
It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.