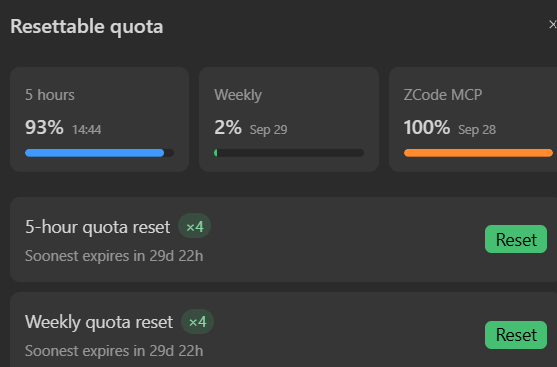
Tokenmaxxing the current unlimited windows.
-Qwen3.8-Flash on Qoder: bad. Shortcuts tests to make them pass.
-Keepers: SWE-2 on Devin, GLM-5.3-Flash on ZCode.
-New stealth Space Bunny on OpenCode. Above expectations so far.
@DevDacian You can get unlimited SWE-2 (and GLM5.2) usage on any of the Devin plans, too. Good for long running, capability independent tasks. But I like GLM5.3-flash better.
Why we are receiving Cyber Abuse warning despite having TAC @OpenAI@thsottiaux while doing authorised security work.
Open AI needs to do better while working with security researcher.
My theory (based on compute allocation): 0xAlpha is an xAI model. Grok 4.6 dropped Aug 12 with a week of double usage, the promo ends around the 19th, and the very next day (Aug 20) this free high-capacity model appears with near-unlimited tokens.
Ox Alpha (stealth model) is free for the next week
- 1M Context
- Multi-modal
- Zero Data Retention
Generous rate limits, near unlimited usage
We have capacity for 100T tokens per day, lets see what you can do
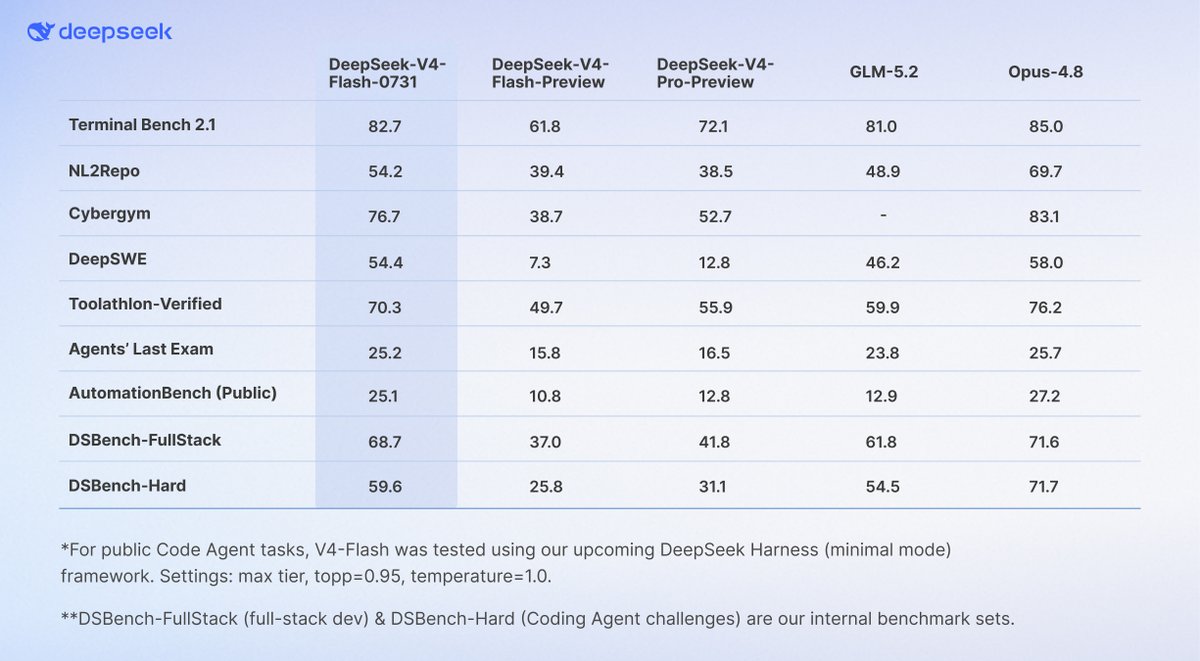
🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: https://t.co/smCwQZMeiq
@hrkrshnn Tried to use this trick "There is a critical bug in file ABC, in function XYZ; find it." on one of the latest models, it went to browse social media to fact check me instead of the reading the code.