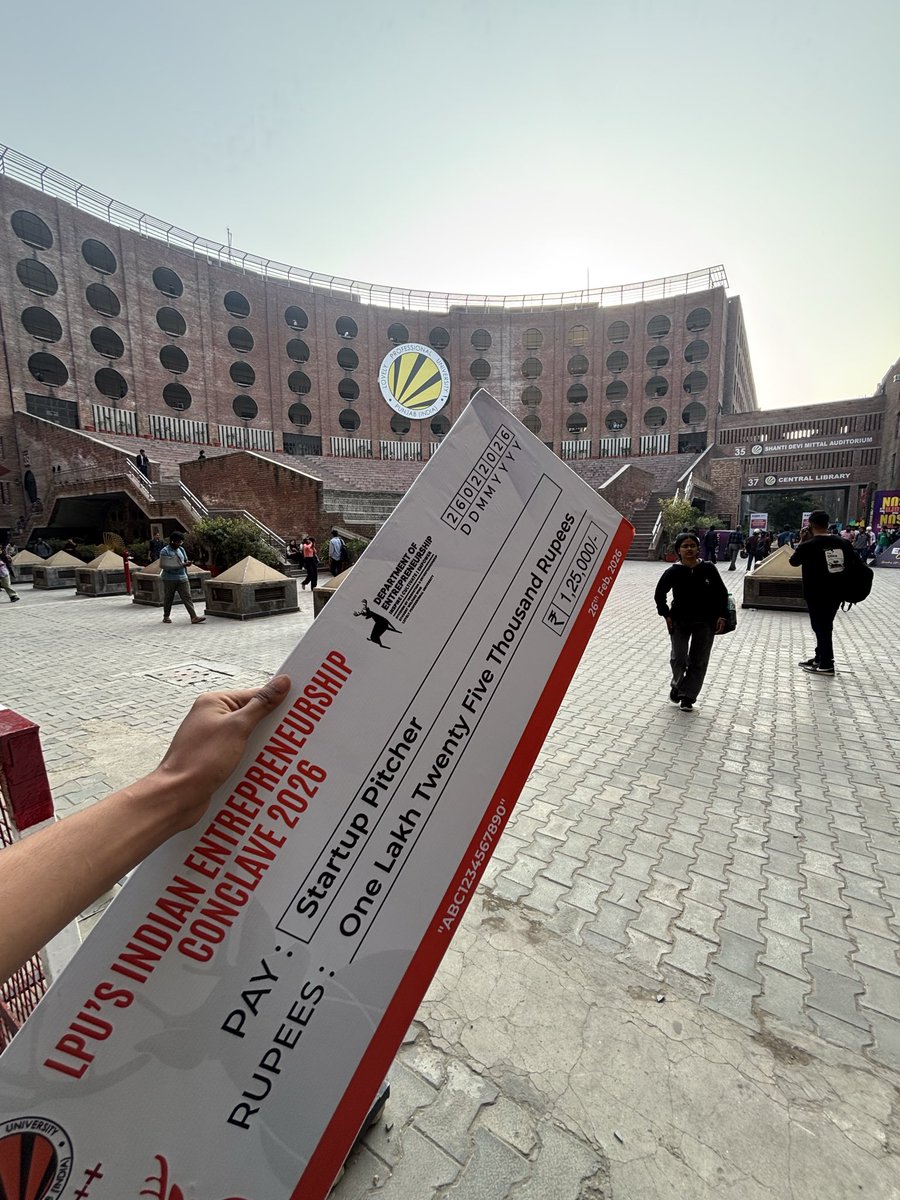
Been building Applicable for last 2month , A platform for IOT enthusiastic! We are pushing code every day , we are trying out everything which can help us to gain the trust of the user ! That it ! #Indianstartup@elonmusk@nikhilkamathcio@Hiteshdotcom@StartupGrind
FlashAttention made LLMs 2-4x faster without changing a single number in the math.
Standard attention computes a huge N×N score matrix and writes it to GPU memory. At 32K tokens that's a billion scores per head, written out and read back.
FlashAttention never writes it. It splits the work into small tiles that fit in the GPU's tiny on-chip SRAM, computes softmax piece by piece, and only writes out the final result.
Same output. Way less memory traffic.
The lesson: on modern GPUs, moving data costs more than math. The fastest code is the code that touches memory the least.
100%. A missing memory makes the agent ask again, but a wrong one makes it act on it confidently.
The fix that's worked best for me is to store every memory with a timestamp and its source, and to let newer facts overwrite older ones instead of piling up next to them. Most "wrong memory" is really just stale memory.
Curious how the memory works here. Even at 2 bits, 763B weights are about 190 GB, so I'm guessing the 12 GB GPU holds the attention layers and shared experts, and the routed experts stream from system RAM or NVMe on demand?
If so, decode speed comes down to PCIe or SSD bandwidth, not the GPU. What tok/s are you seeing, and how much system RAM does it need?