Kyanite Labs builds open tools that make AI agents usable in real workflows.
MCP servers. Media pipelines. Localization. Local AI. Design craft.
Public proof on GitHub. Setup help when you want the short path.
https://t.co/cideypCI1g
https://t.co/ozHZGjfUgw
GPT-6 routing guide, corrected and live: Sol codes, Luna does volume, Astra is the frontier lane — verification contracts per lane, where local 27B still wins. Our GPT-5.6 naming correction is inside.
https://t.co/DVu1bO1byy
Limits, stated: our instrument logs echo cache-type nowhere — believed, never evidenced; treat it as open. Full verification receipt (table, method, held list): http://100.97.231.117:4690/research/floor-optimization/window4/W4-VERIFICATION-RECEIPT-20260925.md 5/5
Speculative decoding inverted: our drafter hit 72.2% acceptance where the control arm got 22.7% — same box, same workload. Throughput went 17.5 → 28.5 tok/s across the sweep. Every number below is receipt-backed. 🧵 1/5
Method: every figure recomputed from raw run counters (accepted/draft_n), dual-verified — hostile audit 09-14 + independent recount 09-25. One older memo figure (21.7 @ nmax2) is HELD: it does not reconcile with this window. Verification means some numbers don't survive. 4/5
Engine verdict (v0.4.1): HIP 20.8 tok/s vs Vulkan 9.2 on the same workload. Engine choice alone more than doubled throughput before any stack tuning. 3/5
@realSamHu@realSamHu that was the design rule: every op returns evidence or fails loudly — no trust-me step anywhere. if a receipt can't prove it, it doesn't ship.
After months of AI agents hallucinating video edits, I built the guardrail.
kinocut — video editing as an MCP server. Local FFmpeg, no API keys, free.
pip install kinocut
6,906 PyPI installs in 30 days. 170 stars. Zero launch noise until now — this thread is day one. 🧵
Hardening the vibe-coded era: prose to code + ML.
LLM paths code can do → production code. Classical-ML questions (beats, cuts, timing) → traditional ML/DSP. The LLM keeps only prose→intent, a closed set.
3B: 0/12 raw, 4/12 typed. Target 9/12 — by asking for LESS.
We benchmarked it: a raw 3B model writes ZERO working ffmpeg commands (0/12). The same 3B on kinocut's typed surface: 4/12 — at lower latency than a 35B writing raw commands.
The deterministic layer does the heavy lifting so small local models can actually edit video.
5 chars)
Our publishing scheduler was dead for three days. Its program lived in a directory a cleanup deleted. An alarm fired every hour the whole time - every notice expired unread. Detection was never the problem. Ownership was.
We ran a 35B reasoning model next to our daily 27B on the same $1,400 mini-PC. At best configs they tie. On grade-school math, thinking is a dial, not a model gap.
Full table, failures included:
https://t.co/rGgbs0J5PK
CookiePilot — open-source cockpit for Cookie Chain. The hero number is the live block time from validator samples (~450–500 ms tonight). Watch every tx go processed → confirmed → finalized, usually under a second. No wallet needed.
https://t.co/BYCtbRJtVk
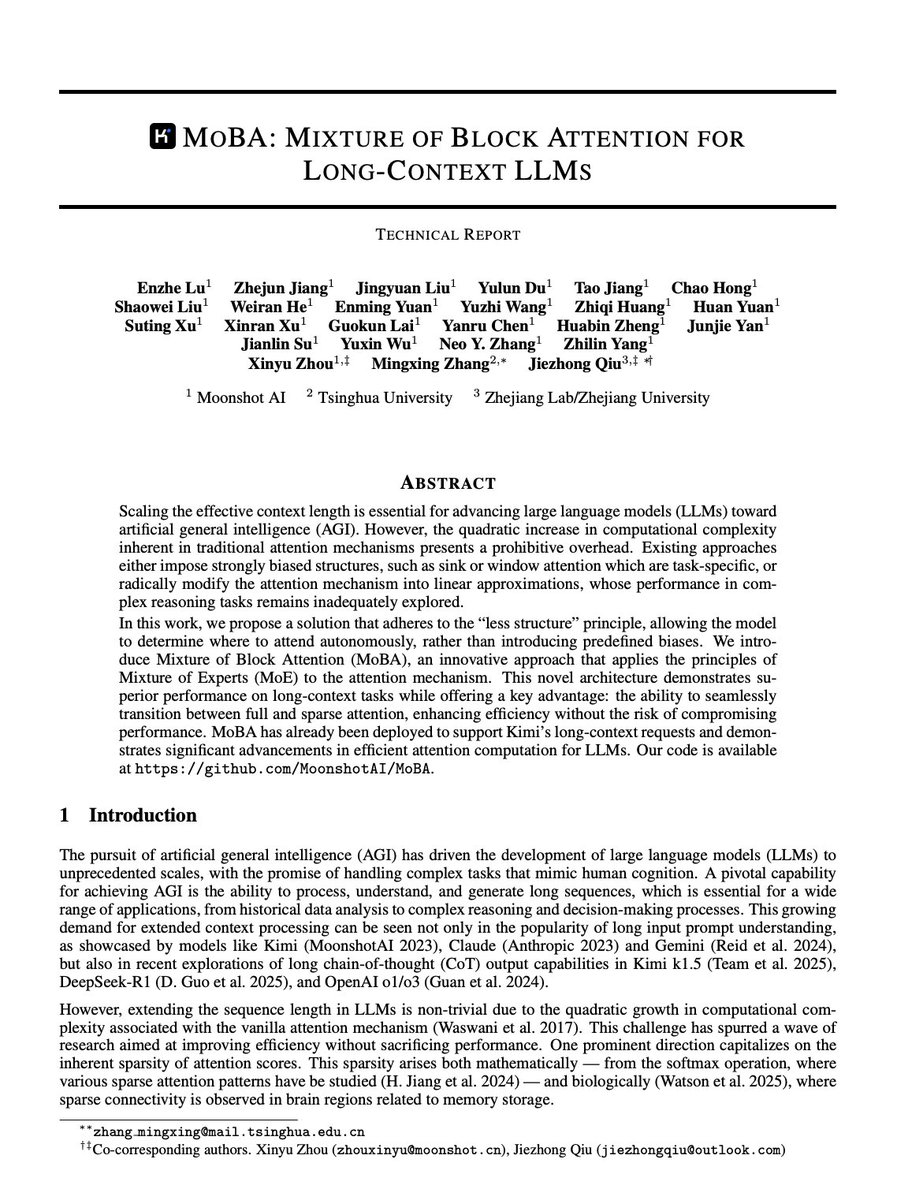
Chinese researchers did it again!
Moonshot AI proved that 95% of attention computation is completely wasted..
They’ve open-sourced the exact attention mechanism powering Kimi's long context.. and it's 16x faster.
It’s called MoBA (Mixture of Block Attention).
Every time you feed an AI a massive prompt, every token desperately tries to look at every single token that came before it.
The math scales quadratically ($O(N^2)$).
It’s like reading a 500-page book and re-reading the entire thing from word one every single time you want to understand a new sentence.
Moonshot looked at this waste and said: No.
Instead of forcing full, brute-force attention across everything, MoBA applies the principles of Mixture of Experts (MoE) directly to the attention layer.
How it works:
• It chops the context history into discrete blocks.
• A lightweight dynamic gating mechanism lets each query token instantly "vote" and route only to the specific blocks that actually matter.
• It achieves up to 95% sparsity on long contexts without sacrificing performance.
The results are staggering:
It maintains full-attention accuracy on 1-million-token contexts while slashing massive compute overhead.
We are watching the structural efficiency barrier of long-context AI get smashed in real-time.
While Western labs argue about how to afford million-token context windows, Moonshot open-sourced the blueprint to make them radically cheap.
27B GSM8K: 96.7 with thinking off and on. 35B: 90.0 → 98.3 when it thinks. Best-vs-best is a one-problem tie. Spec decoding was dead here (~33% acceptance, ~9% slower; measured twice).
5/ The point: a $1,400 box, a free model, open tooling — and a full measured story with raw logs for every claim. That is the product. What runs next on this rig is the next chapter. Repo in reply.
https://t.co/a8y4ciHEQK
We set out to see if a 1,400 mini-PC could serve a 27B model like a big rig. Today we closed the book: every dial measured, retrieval exact at the 262k ceiling, vision fixed and validated upstream, final config frozen. Every number public. Thread.
config: speculation measured four ways (the shipped setup is fastest: 15.1s per 200-word answer vs 17.8s without). Memory trade measured: the heavy setting buys up to ~3 seconds on follow-ups (sub-second to 2.8s measured) for 8 GB. We kept the light one. Frozen, serving, done.