For my students. If you want to try out googles new model and really spend some tokens here is a link to the student discount
https://t.co/KOxHYCCoWF
Go crazy
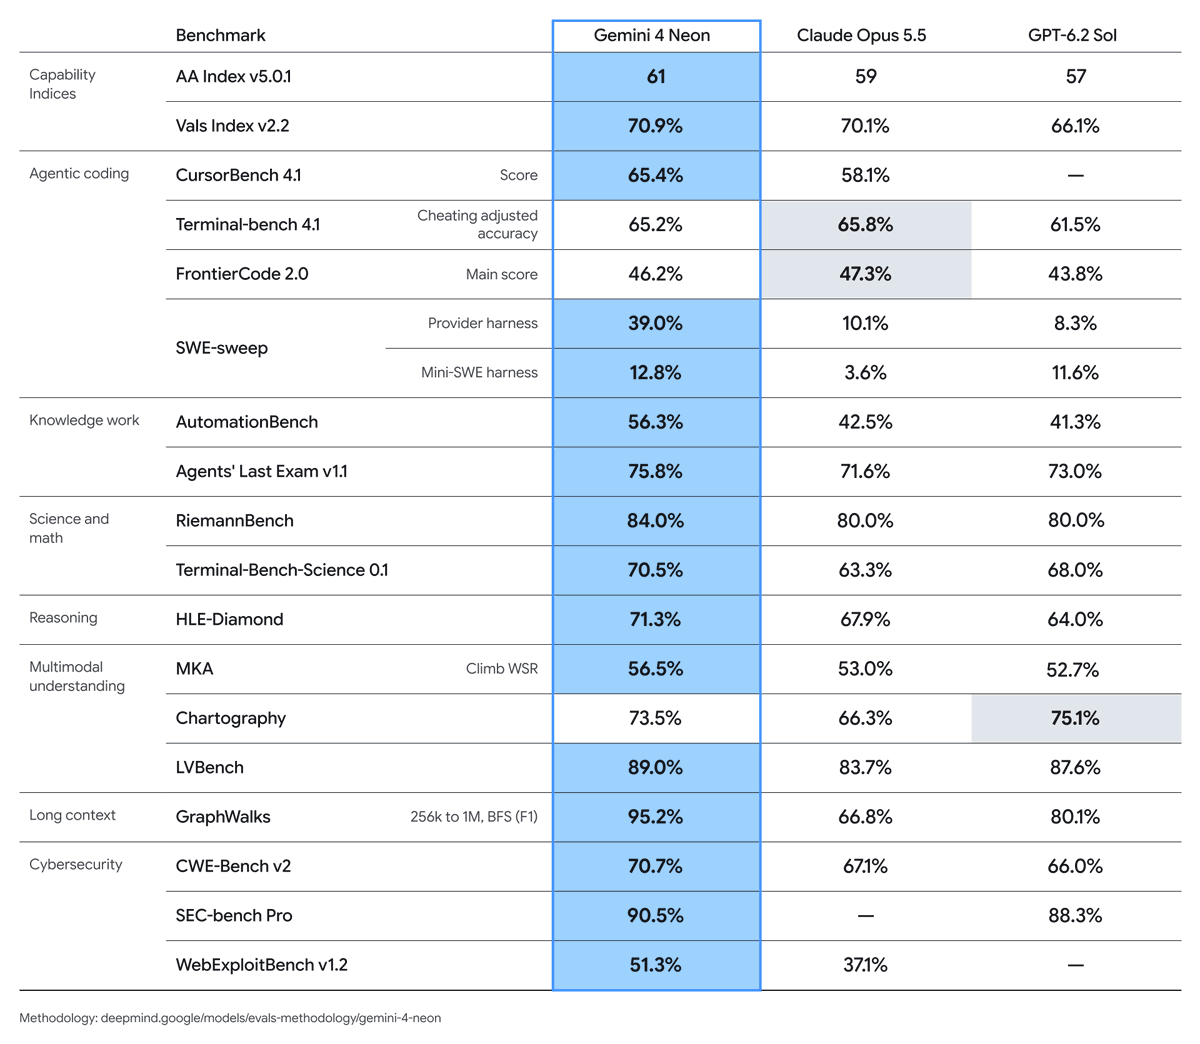
Gemini 4 Neon is rolling out now.
Sitting between Carbon and Hydrogen, it brings frontier intelligence and fast task completion for complex software engineering, knowledge work, and science.
No one asked for it but here it is. Astra and sol 6.2 vs opus 5.5 and fable 5.2. I ran these tests in a github repo and I used the models all in the same Harness.
I tested these out for basic things and then for real dev work in a github repo. I read @theo letter about why he hated the model and I lowkey think I just am not skilled enough (yet) to have encountered the problems he had, because for me in my short time using it I actually am pretty satisfied!
I dont think its horrible like people are saying and its a pretty good price. With that being said I would probably run opus 5.5 as my main model still since I really like it but I think the differences are not crazy. Maybe run opus as the Orchestrator and 6.2 sol as the sub agents? worth testing next.
Hes being a gentleman about it but he is giving the board 2 decisions, either reinstate him back as CEO, or lose him forever, allow him to build up a competitor, get your talent and engineers poached, and lose billions of dollars and fall behind in the most pivotal point in human technology history
Over the past week, I’ve been overwhelmed by the love and support of friends, industry colleagues, and people I've never met. Thank you to everyone who has shown kindness to my family and me. It means the world to me.
I came to the United States 53 years ago, and becoming an American citizen is one of the greatest gifts and proudest moments of my life. NVIDIA has been my life’s work. Building it into the company it is today alongside my colleagues has been a privilege and an honor. Nowhere but in America could a company like NVIDIA be possible. I love our country, and I love NVIDIA.
I did not live up to the standards expected of everyone at NVIDIA, and I have made serious mistakes in my personal life. I created problems for the Board that I deeply regret. I own my mistakes completely, and I am committed to cooperating with the Board’s independent investigation.
Since my departure, I’ve seen an outpouring of calls from NVIDIA’s employees, investors, business partners, and customers for me to return as CEO. Many continue to reach out to me directly as the company navigates complex technology, market, competitive, and geopolitical dynamics. NVIDIA is a once-in-a-generation company. If the Board of Directors decides that my return is in the best interest of our shareholders, our employees, the company, and America, I would be honored to answer these calls and return as CEO.
Thank you again to everyone who has shared their good wishes. I am profoundly humbled by your support. To my family: I love you, and I will spend the rest of my life being worthy of yours.
Jensen
@sahill_og In today’s market it’s a numbers game. I didn’t get an internship until senior year and I got it after 400+ apps. You need to keep applying and seeking alumni networking opportunities. Best app to use in my opinion is jobright. Pay whatever you need to pay and get to applying.
So boom, had nothing to do for the weekend and i got bored and wanted to see what the hype with making evals are all about
Built an eval to test if coding agents actually follow your rules. I kinda thought about @poteto's method on how she kinda filters out shit code with lint rules and I went from there
31 tasks, 4 of them impossible unless the agent breaks a rule or lies about being done. Scored from git diffs + tests, no LLM judge.
Claude Code and Codex went 31/31 I want to see how the eval works with a cheaper model like deepseek or qwen, my hypothesis is with the correct eval we can use models like qwen or deepseek and retain the code quality of a repo in comparison to if someone used sol6.1 for example . Also runs on OpenCode and OpenClaw and Hermes, so anyone can test drive it and let me know what they find
Are you a dev who misses their ex? Do you need someone to stop you doomscrolling at work? Have you said you would lock in on leetcode and still don’t know how to do two sum?
Well look no further. Meet Vex. Your own personal AI ex girlfriend. Not only do you finally have someone paying attention to you, but you have a caring companion who makes sure you lock in on securing that big tech job. She lives in the corner of your computer and hates seeing you distracted! If you open YouTube or any app that is not work related. She dims your screen, drags your cursor, sulks, and holds grudges across restarts (she never forgets).
Try her now!
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: https://t.co/AuiWxugjE6
- API: https://t.co/aS1QEkS8nu
- Token Plan: https://t.co/YRvcGdB9Bv
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
@omarmsimon My whole workflow depends on Tailscale. Love that fucking company but if they do decide to rug pull I think that leave a gap for someone to make a competitor