Product Update:
LangRouter and Langcli already support DeepSeek V4.1 Flash model.
The DeepSeek V4.1 Flash offers good performance, while the price has also dropped significantly.
Note: DeepSeek V4.1 Flash now supports image input.
Enjoy.
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6
We sincerely apologize for the inconvenience caused by our negligence. We will immediately strengthen our delivery quality management. Thank you for your continued support and companionship.
We regret to inform you that due to our oversight, a LangRouter upgrade incident on September 7, 2026, caused some models to become unavailable in Langcli. The affected models at the time included: deepseek-v4-flash, deepseek-v4-pro, gpt-5.6-sol, gpt-5.4, and ring-2.6-1t.
The issue has now been resolved, and all affected models are back to normal operation.
Please remember to upgrade Langcli to the latest version using the command:
npm i -g langcli-com
If you are using any of the following models, you must upgrade Langcli to the latest version (0.1.49); otherwise, errors will occur:
langrouter/auto
kimi-k2.7-code
glm-5.2
glm-5.3-flash
minimax-m3
kimi-k2.5
mimo-v2.5-pro
mimo-v2.5
kimi-k2.6
Friendly reminder:
Due to requirements from the upstream LLM provider, please upgrade your local Langcli to the latest version; otherwise, you may encounter errors during use.
You can upgrade by running the following command in your terminal:
npm i -g langcli-com
Product Update:
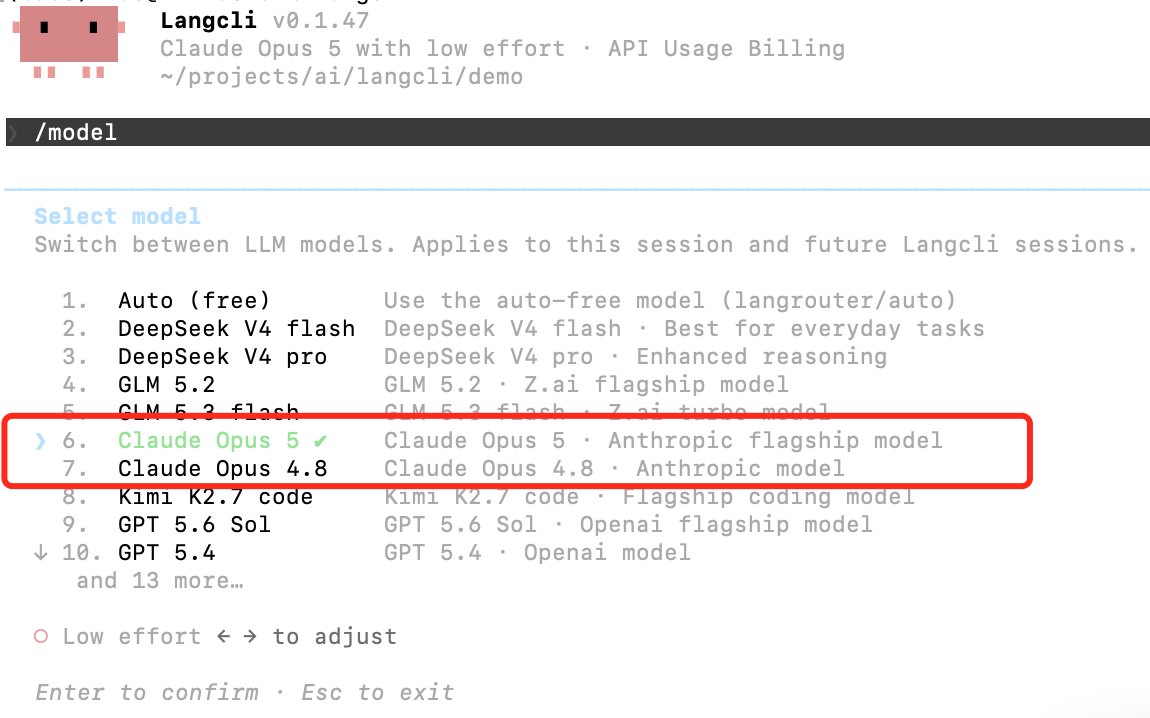
LangRouter and Langcli already support Claude opus 5 model.
The Opus 5 offers stronger performance, while the price remains the same as that of the Opus 4.8.
Enjoy.
Introducing GLM-5.3-Flash
- Leading capabilities at a highly competitive price
- Natively multimodal with a 1M-token context window
- A 320B-A18B model released under the MIT License
- Previously previewed as Ox Alpha, running entirely on Chinese AI chips
Blog: https://t.co/tzOmB7gdZP
Available now across all official platforms:
Weights: https://t.co/9LRMahY9Wa
API: https://t.co/VcaQnzYmS9
Coding Plan: https://t.co/Nk8Y98HNhU
ZCode: https://t.co/Peepqv4XSx
Chat: https://t.co/WCqWT0qCQb
AutoClaw: https://t.co/aGEG5HqTTb
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: https://t.co/M5hYypFLgJ
- Technical Report: https://t.co/IF0gObIkQO
- Hugging Face: https://t.co/6ow8QVAABt
- ModelScope: https://t.co/tDOn2jNuFG
Since announcing Jalapeño, our first custom inference chip, we’ve been testing it and the system around it.
The results show a major advance: more intelligence from every watt and faster responses, delivering both higher throughput and lower latency in one architecture without sacrificing efficiency.
Overall, a very tasteful chip launch by OpenAI. It takes the best of both GPUs and TPUs. I wish they were for sale, but we'll all get the Chinese knockoffs in 3 years. I can't wait until China starts spamming fab capacity.
🚨 DeepSeek Flash Vision Is The New King of Open Source
- DS Flash Vision is 10x cheaper than Kimi K3
- It beats GLM 5.3 on performance
- very good at agentic coding
- works with images
This is the first open source model we have it in production 🚀
OpenWorker -- an open source agent that doesn't just chat but completes tasks on your laptop -- just released a new version with many features for security workflows.
After our initial release, many users found it especially useful for cybersecurity. Attackers are already using AI; OpenWorker is committed to giving defenders the same leverage. Running an agent requires both (i) A model and (ii) A harness (the software around the model). Because the OpenWorker harness is fully open source, security teams can audit it to make sure we haven't built any backdoors that exfiltrate your code and data to some company or even a foreign adversary.
OpenWorker now comes with built-in cybersecurity agents for (i) Scanning your code for vulnerabilities. (ii) Scanning dependencies for supply chain injections. (iii) Checking your cloud security configuration for attack surfaces. This enables developers to do much more security work before deployment (part of what's called the "shift left" movement).
You choose the model: you can run open weight models fully locally so sensitive code never leaves your machine. This helps with legitimate security work (like reproducing a known exploit to defend against it) that can trigger refusals in leading closed models. Or use your ChatGPT subscription, or stealth preview models like Ox Alpha, or any model via API key.
Thanks also to all the open source contributors!
Join work with @rohitcprasad so please follow him too to get more frequent updates.
Try it out: https://t.co/QPZLudn7ug
Code: https://t.co/NYCiTD6hSq
DeepSeek-V4-Flash-Vision-Exp is now live on the DeepSeek API Platform! 🚀
🔹 This experimental multimodal model matches DeepSeek-V4-Flash on text capabilities—including agents, reasoning, and world knowledge.
🔹 On multimodal agent benchmarks, V4-Flash-Vision-Exp makes a major leap over V4-Flash, bringing multimodal agent performance close to Opus-4.8.
Try it with model='deepseek-v4-flash-vision-exp'. DeepSeek Harness 0.1.1 was released today with out-of-the-box support for the new model.
1/n
We’re launching DeepSeek-V4-Pro today! 🚀
🔷 Major Agent upgrades with strong production gains!
🔷 Flexible reasoning effort for V4-Pro & V4-Flash: low for simple tasks, high for daily Agent workflows, max for complex tasks.
🔷 Native OpenAI Responses API support, optimized for Codex with one-click setup.
V4 Pro is now available on app/web. Try it via “Expert Mode”.
V4 Pro is also available via API. Model names remain unchanged—please refer to the API docs for setup details.