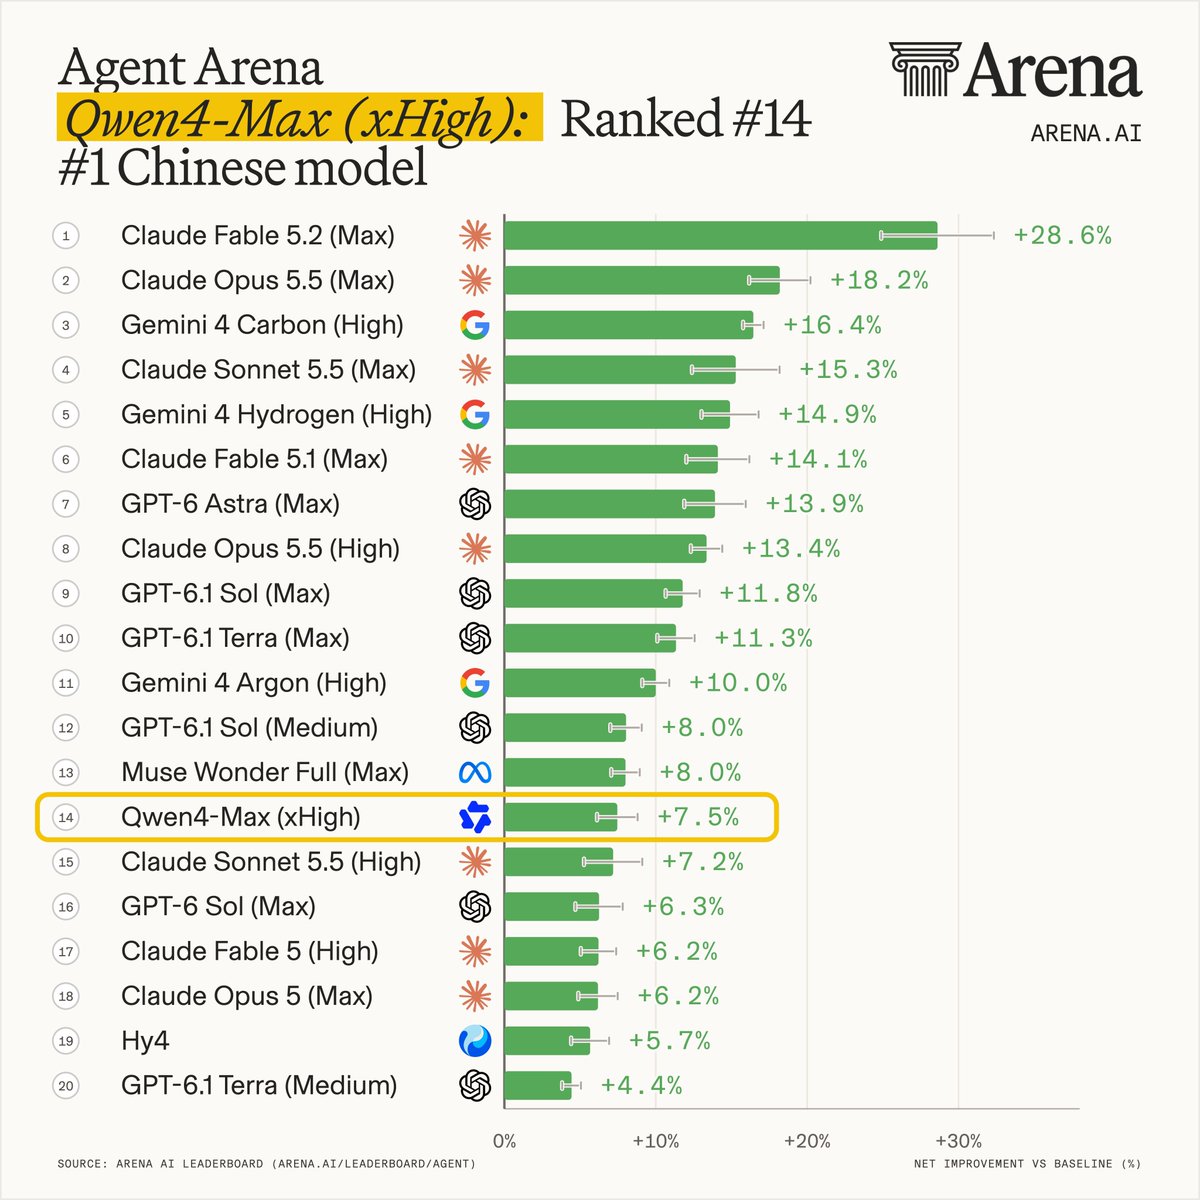
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: https://t.co/AuiWxugjE6
- API: https://t.co/aS1QEkS8nu
- Token Plan: https://t.co/YRvcGdB9Bv
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
GPT-6.2 Astra /sol won't drop.
Yes, I think they will rename the model to 6.5 Astra/sol with a bit more training.
Reasons Are simple:
-Fable 5.2 dropped and it's significantly good
-Gemini dropping argon, carbon, hydrogen and krypton.
-Chinese models cost efficiency is top. Notch for the intelligence
So They need a beast Astra/sol not another mid tier model
BLG ARE WORLD CHAMPIONS. 🏆
Our first Summoner’s Cup. It’s finally coming home.
To everyone who’s ever worn the jersey, worked behind the scenes, or cheered us on: we did it!
#BLGWIN#Worlds2026