The Last Developer
If there are 1,000,000 developers,
I'm one of them
If there are 1,000 developers,
I'm one of them
If there are 100 developers,
I'm one of them
If there is only 1 developer,
that is me
If there are no developers,
AI won and took my job
HODL $LASTDEV.
This guy built a two-sided trading bot on Polymarket and made $233,695
His algorithm trades short-term crypto Up/Down markets using asynchronous complete-set accumulation and dynamic inventory management:
1. Starts building inventory almost as soon as the market opens
Its first purchase occurs a median of 33 seconds after the market opens
It keeps buying through most of the trading window. In 5 minute markets, its last purchase occurs a median of 223 seconds after opening
2. Adds the opposite outcome to its position
It bought both Up and Down in 88.76% of markets
It starts buying the opposite side a median of 35 seconds after its first purchase. It then keeps switching between outcomes as the market reprices
3. Turns most of its inventory into complete sets
89.82% of the shares it buys can be matched into Up + Down pairs
The average combined cost of a pair is 96.35c, giving it an edge of 3.65c
But this is not pure arbitrage
Only 58.66% of two-sided markets ended up with an average combined Up + Down cost below $1. The remaining 10.18% of shares are unpaired, leaving a directional residual
Its Polymarket account: norm1e69
You can build your own trading bot here:
https://t.co/JVofcJa07i
(A trial is available after signing up)
The algorithm’s main edge comes from asynchronous pairing: it keeps switching between Up and Down, matches most of its inventory into complete sets, and retains directional exposure through the unpaired remainder
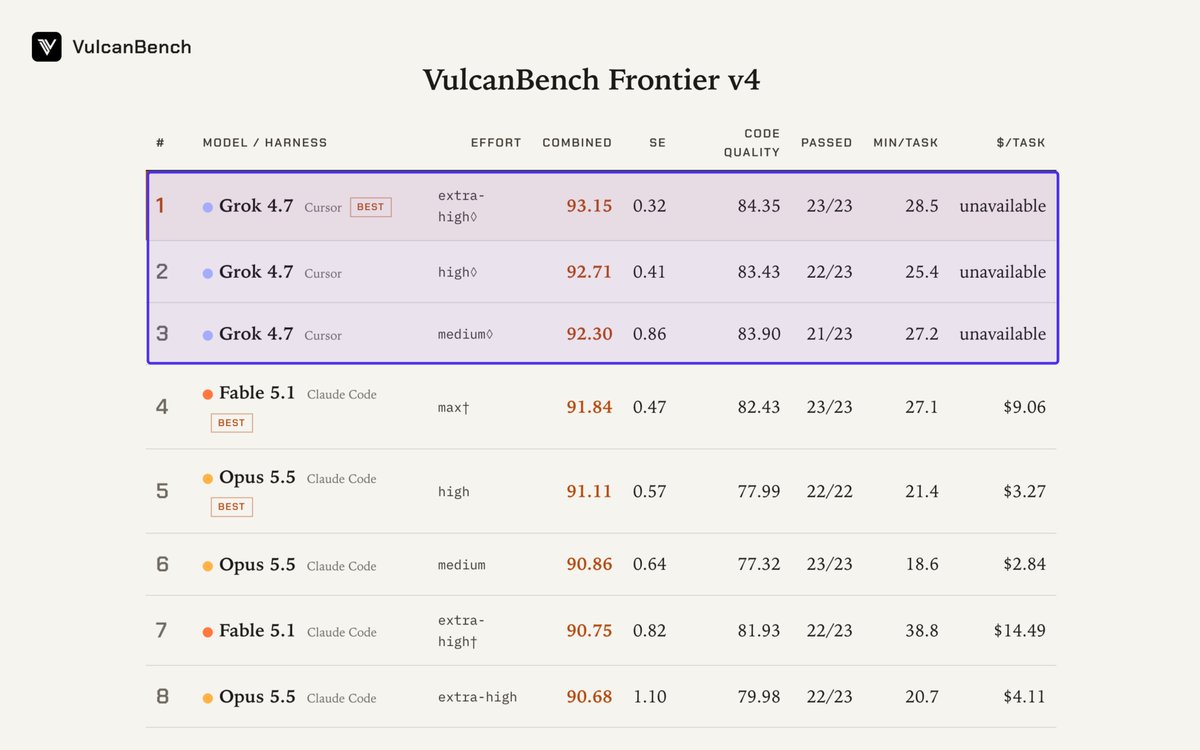
Grok 4.7 takes the TOP 3 spots on VulcanBench Frontier v4, outperforming Fable 5.1, Opus 5.5, GPT-6 Astra, GPT-6.1 Sol and other leading frontier models
• Grok 4.7 xHigh - 93.15
• Grok 4.7 High - 92.71
• Grok 4.7 Medium - 92.30
VulcanBench Frontier v4 tests whether AI models can handle difficult repository-level software engineering work rather than simply generate isolated code snippets
The benchmark contains 23 behavioural-reconstruction tasks where models have to rebuild legacy software to match its actual behaviour, with functional correctness tested through hidden tests alongside security, lint/complexity and code quality
And the task results are just as impressive:
• Grok 4.7 xHigh - 23/23 passed
• Grok 4.7 High - 22/23 passed
• Grok 4.7 Medium - 21/23 passed
Grok 4.7 took all #1, #2 and #3 spots