Another major @arena leaderboard check 🚀
ERNIE-5.0-Preview-1203 hit 1451 in the Text Arena, up 23 points from the previous version.
That puts it #1 among Chinese models, with solid gains in creative writing and complex prompt handling.
🚨Text Leaderboard Update: ERNIE-5.0-Preview-1203 by Baidu @ernieforDevs has landed on the leaderboard with a score of 1451. A few highlights:
🔹Top Text model from Chinese labs (next best Qwen3-max-preview ranked #22)
🔹This is a 23 pt increase since ERNIE-5.0-Preview-1103
🔹Shows strength in Creative Writing and Hard Prompts
The scores are still preliminary, and we’ll see how it converges.
Congrats to the Ernie team on this incredible milestone 👏
@baidu is back!!!
Two models and a new global web portal has been released today. Finally the phone verification is no longer needed!!! They do listen to the voice of developers.
This model release includes both enhanced lightweighted thinking model ERNIE-4.5-21B-A3B-Thinking already available on @huggingface now.
It also includes a new stealth Ernie X 1.1 model that is hidden in the UI and claims to smarter and think deeper.
I tried generating a simple Snake game. When did coding a Snake game become the ultimate vibe-coding 101 test? The result actually looks great. I’m really into the clean design and smooth style it delivered.
We've just unveiled ERNIE 4.5 & X1! 🚀
As a deep-thinking reasoning model with multimodal capabilities, ERNIE X1 delivers performance on par with DeepSeek R1 at only half the price. Meanwhile, ERNIE 4.5 is our latest foundation model and new-generation native multimodal model.
Plus, our AI chatbot ERNIE Bot has now been made free to individual users ahead of schedule. Both models are now freely accessible to all ERNIE Bot users via its official website: https://t.co/hJjfLaKsEN.
IR needs new hills to climb.
TREC yielded BM25 almost right away (year 3), MS MARCO yielded BERT cross-encoders, doc2query, ColBERT, DeepImpact/SPLADE, and MarginMSE/RocketQA almost immediately (years 1-2), and BEIR yielded a few such things in year 1.
So, what's next?
Dense Text Retrieval based on Pretrained Language Models: A Survey
Surveys recent advances in employing PLMs for dense text retrieval, including architecture design, training strategies, indexing, and pipeline optimization.
📝https://t.co/gP6f49Rygg
👨🏽💻https://t.co/ghiY5oOE08
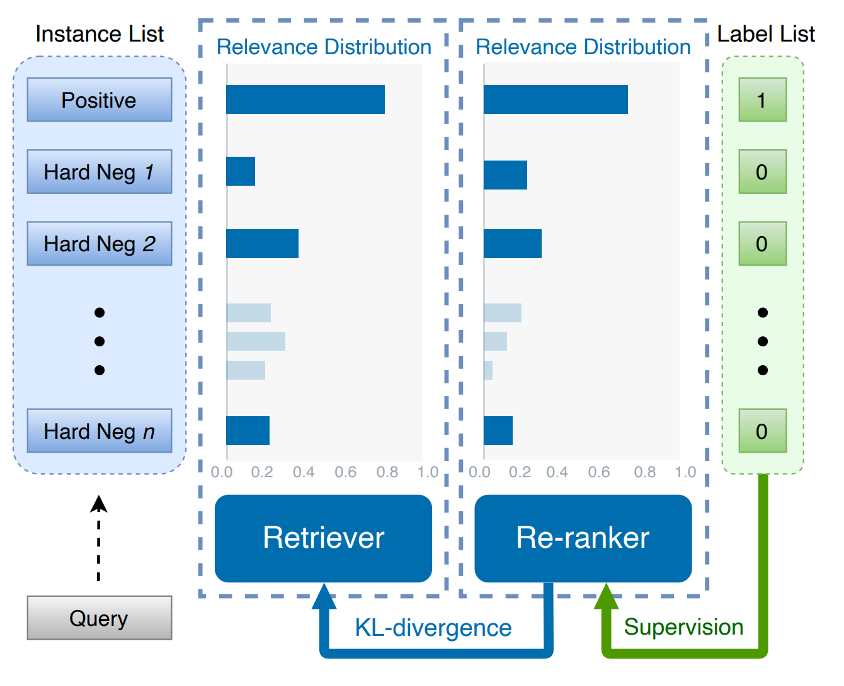
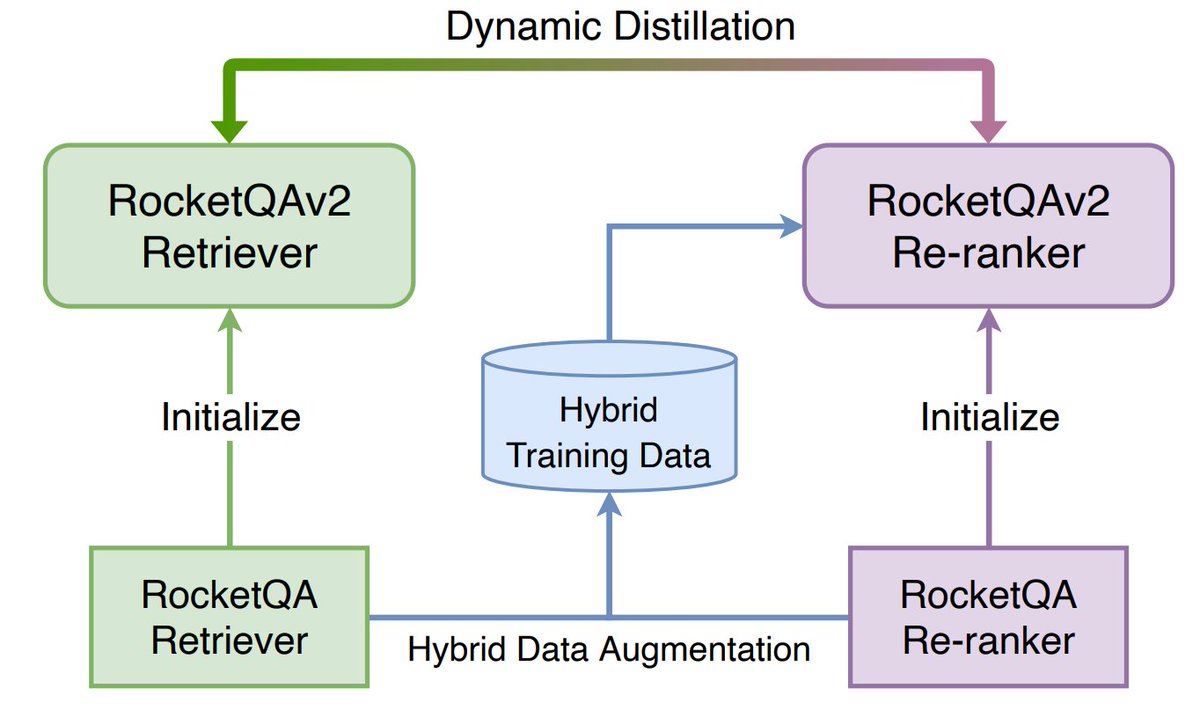
@ak92501@jayleicn We published RocketQAv2 at EMNLP'21 with a similar idea: jointly optimizing dual-encoder (i.e. retriever) and cross-encoder (i.e. re-ranker) on the text-to-text task.
https://t.co/xgi9b20CTz
We provide an easy-to-use toolkit for running and fine-tuning dense retrievers, namely RocketQA.
🚀Pre-trained SOTA models
🚀1st open-source Chinese model
🚀Integration with @JinaAI_ to help build an e2e question answering system
GitHub: https://t.co/OfxbpDyFj3
🚀 The #RocketQA pre-trained models can now be used directly from Jina Hub thanks to our partnership with RocketQA!
Read our latest #blog to build a state-of-the-art QA application with Jina and RocketQA in just a few lines of code!
👉 https://t.co/w31ba19sKG
Our work latest work on dense retrieval - 🚀RocketQAv2 will be presented at #EMNLP2021! We propose a joint training approach for dense passage retrieval and passage re-ranking.
Paper📄:https://t.co/Q5U7o7ptp5
Code💾: https://t.co/o9CFcaVlr0
Video🎥: https://t.co/iZ5ddFFFFR
Two "must read" papers in 2020 for those interested in Search.
Embedding-based Retrieval in Facebook Search https://t.co/2JZrwxqDuJ
RocketQA: An Optimized Training Approach to Dense Passage Retrieval for Open-Domain Question Answering
https://t.co/BCX3GTHhC2
#NAACL2021 We'll present our work on 🚀 RocketQA: An Optimized Training Approach to Dense Passage Retrieval for Open-Domain Question Answering at Session 16D (Wed, 7:40PM PDT). Come say hi & ask questions.
The paper📄, code💾, model📂, and etc. are at: https://t.co/GQUKDtXVgK
Our RocketQA introduced the techniques of cross-batch negative sampling, denoised hard negative sampling and data augmentation to improve dense passage retrieval for open-domain QA. Looking forward to seeing more revolution in this area. 🚀🚀🚀
Registration for the 2021 Language & Intelligence Challenge is now open! This year's competition is based on LUGE, an open-source project of Chinese NLP benchmarks. Winners will share an RMB 300,000 prize pool, register by May 12th to enter! Learn more: https://t.co/BPOzuM1ksy
We often cite papers using arXiv info w/o noting that they are already PUBLISHED in confs like @aclmeeting and @iclr_conf. These incorrect bib entries are so annoying!😠 We introduce Rebiber, a tool to fix them using @aclanthology and @dblp_org. 😆
Code: https://t.co/Nmy6OZaaUQ