Convex analysis meets model checking🧐
Probabilistic model checking can be seen as set inclusion test between a safe region and the achievability set to failure states in MDP. Using convex analysis, we propose a computationally efficient query.
https://t.co/1n3fQev8kn
Convex analysis meets model checking🧐
Probabilistic model checking can be seen as set inclusion test between a safe region and the achievability set to failure states in MDP. Using convex analysis, we propose a computationally efficient query.
https://t.co/1n3fQev8kn
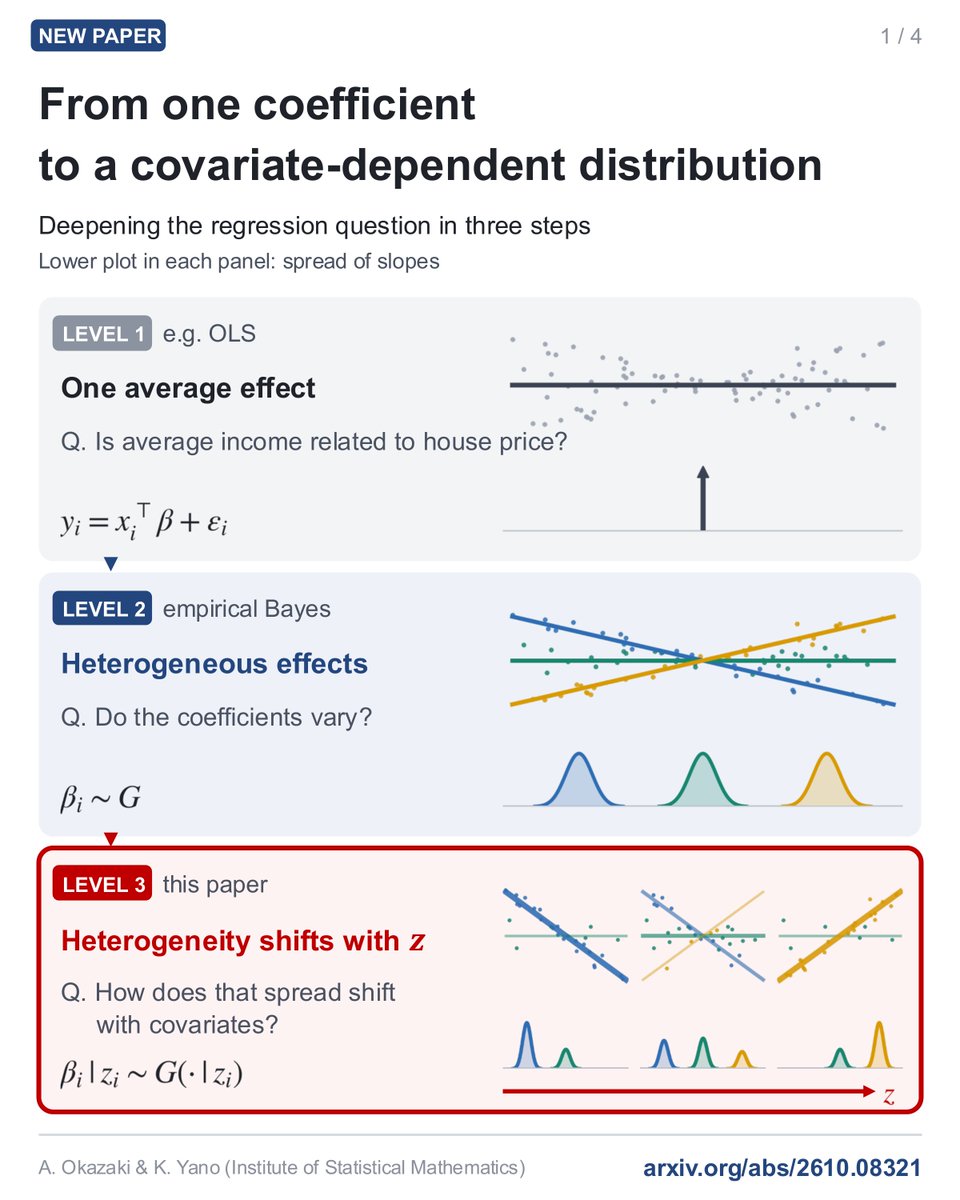
New paper with my ISM colleague A. Okazaki.
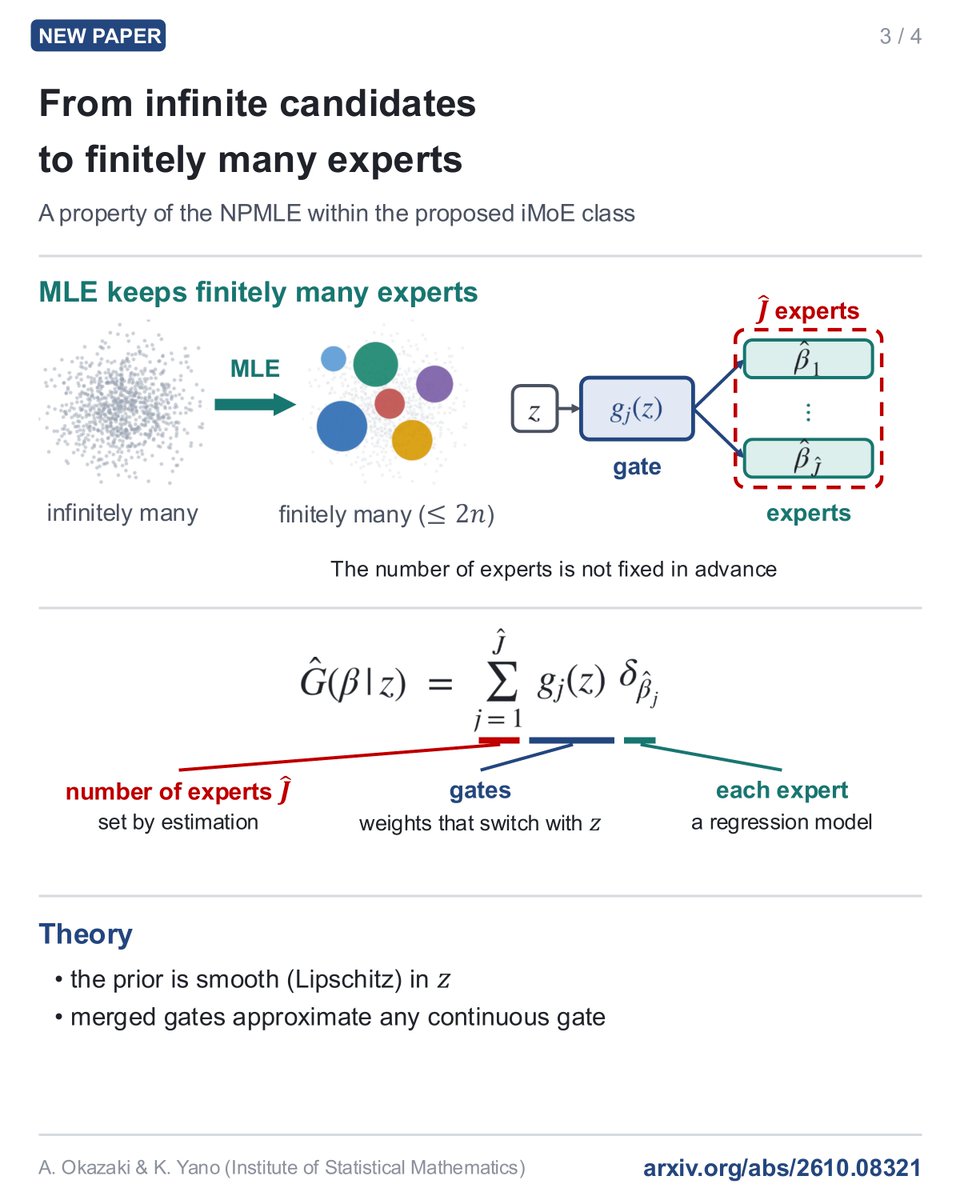
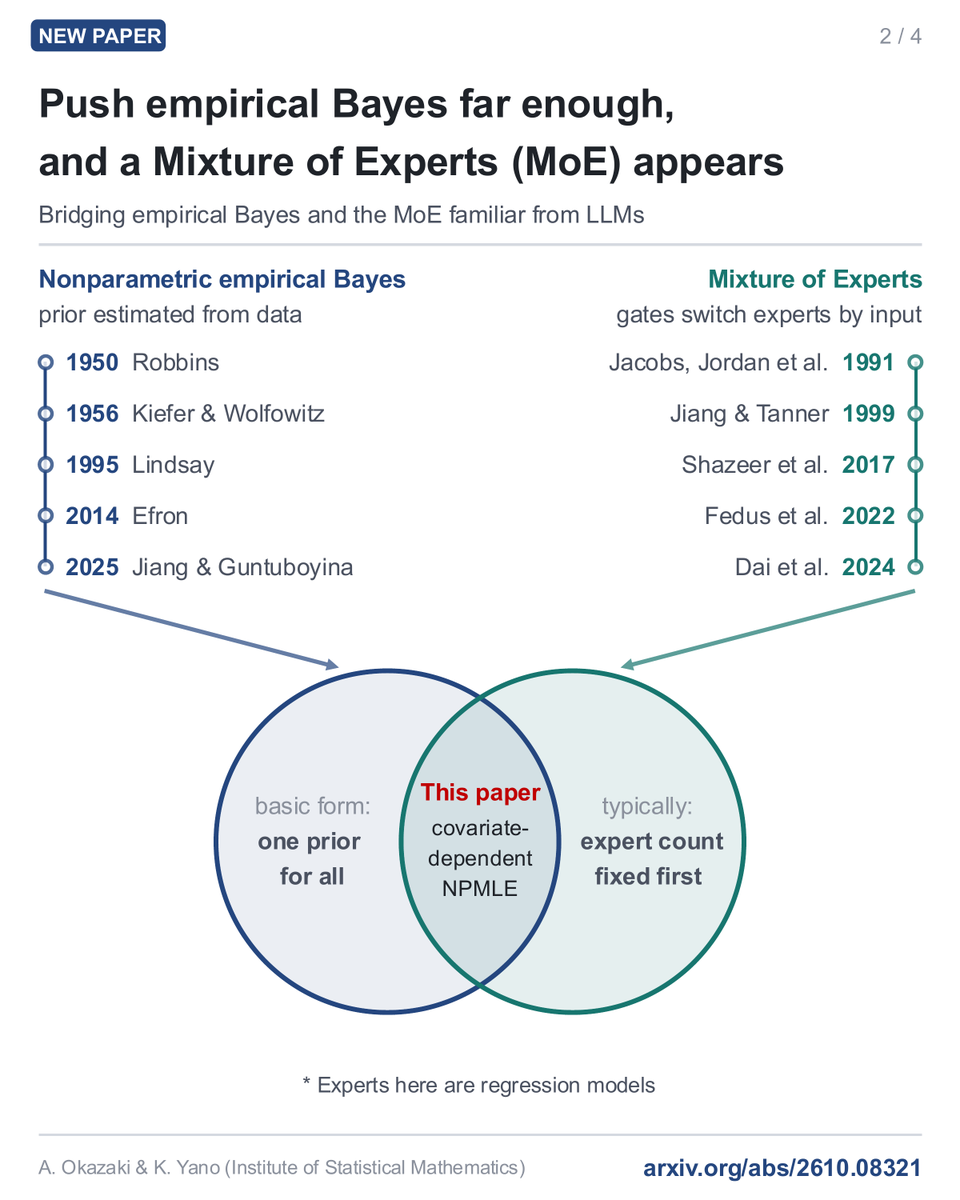
Empirical Bayes, with roots in the 1950s, and the Mixture of Experts familiar from LLMs meet in a single estimation problem.
https://t.co/UVc12tJftS
I got to know this work recently, which is based on a very cool formulation of layer-wise + learning dynamics of Transformer as an optimal control problem!
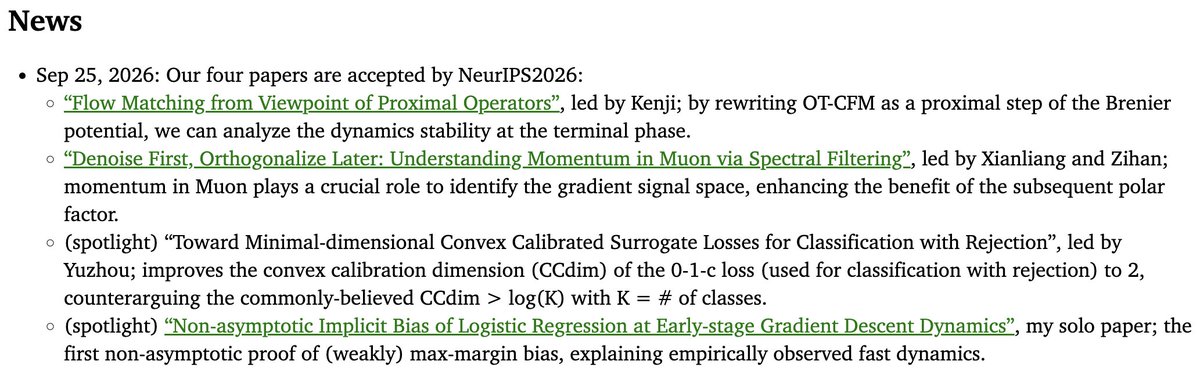
"We are delighted to inform you that your submission, "Training-Induced Escape from Token Clustering in a Mean-Field Formulation of Transformers"(https://t.co/thG7dShSNc), has been accepted at NeurIPS 2026 Main Track as poster. Congratulations!"
We are excited to have following papers at #NeurIPS2026! I'm proud of all of them, but in particular, it's fantastic to have the first collaboration with my first PhD student @XianliangLi910 on momentum analysis of Muon. Come to see his work 👉 https://t.co/EjMBTe3vRs
🧠Why does Muon do momentum before orthogonalization?
✨Our key insight: momentum acts as a spectral filter for the matrix-valued gradient, yielding a more reliable update for the orthogonalization step.
📝Paper: https://t.co/mqjxCrcSIV
🌐Project: https://t.co/Cep6HK0oAA
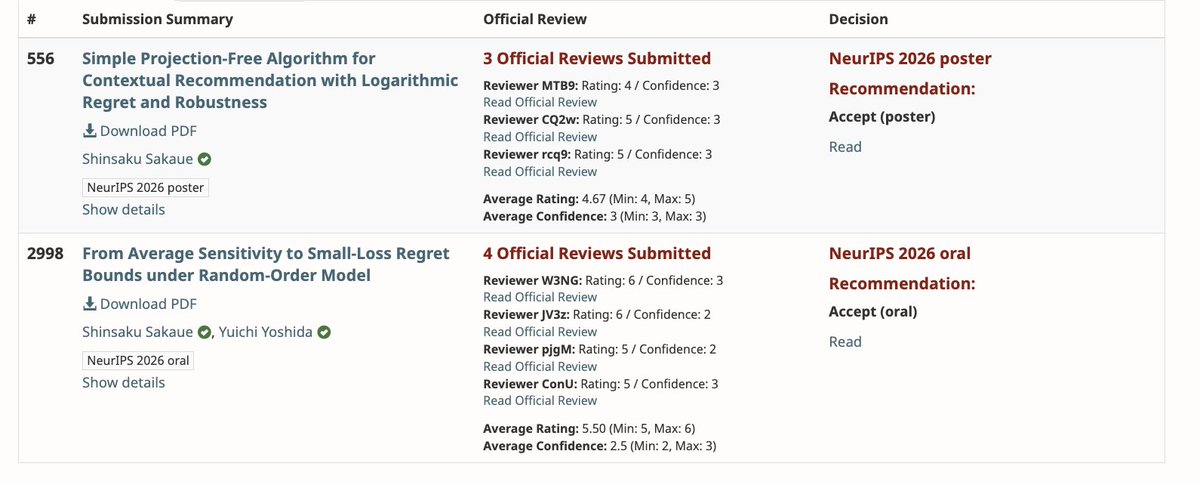
Very excited to share that both of my submissions have been accepted to #NeurIPS2026!! 🎉🎉
And one of them was selected for an oral presentation! 🥳✨
Huge thanks to Yuichi @oxytan for the wonderful collaboration! 🙏
Looking forward to NeurIPS! 🚀
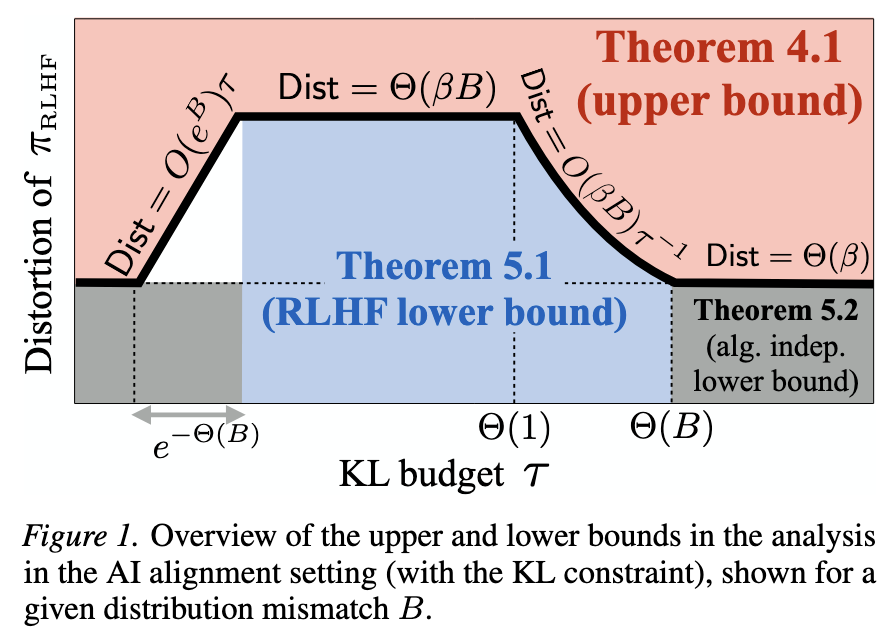
Recent distortion theory argues RLHF is exponentially suboptimal to align with heterogeneous user utilities, but why do people remain to rely RLHF?
We showed RLHF's exponential deterioration can be mitigated by taking distribution mismatch (B) into account.
Finally uploaded our ICML paper analyzing RLHF through the lens of social choice theory.
When users have heterogeneous preferences, RLHF may fail to maximize average user utility. We revisit prior worst-case results and identify conditions under which RLHF works well.
I'm highly thrilled to host Mohit as a new postdoc in my team! He has a solid series of work on the foundation of fairness in ML.
Mohit Sharma さんが研究員としてジョインしました。機械学習の公平性をはじめ、博士時代に良い仕事をされているので、これからの共同研究が楽しみです。
I have now joined as a Postdoc at Tohoku University and the Institute of Statistical Mathematics Tokyo, where I will work with Prof. Han Bao (@levelfour_ ). (2/2)