To clarify things: I may have been unfair to the model.
Usually, when a new model drops, everyone tests it to its full potential. My previous prompt was also weak, so I improved it and tested Muse Wonder Max again.
I know I might get some hate for admitting this, but I was unfair to the model. It’s still not on Opus’s level, in my opinion, but I didn’t test it properly the first time.
Latest @SemiAnalysis_ article comparing coding agent subscription plans show that @Muse Code's $50 plan delivers 51.3x the value per dollar, topping the API value leaderboard.
The $50 plan gives a comparable amount of token value as both the Codex $200 and Claude $200 plans. For good coding performance (give max reasoning effort a spin!) + affordable and fast inference, it's hard to argue anything beats Muse Code right now.
To users hitting limits on this tier, we hear you on wanting a higher subscription option and will be sharing more on this soon!
Download Muse Code at https://t.co/0gA0vrHMFF
Full SemiAnalysis post: https://t.co/KYYYOc0fRh
1/ we just publicly released Muse Spark 1.3 max!
we see significantly stronger coding and agentic performance on muse spark 1.3 max, so would strongly recommend trying it out even if you've already tried muse spark 1.3 high or muse spark 1.3 xhigh.
Muse Spark 1.3 is rolling out today with frontier performance almost too cheap to meter. This is the biggest jump we've made so far on coding and agentic work. Try it in Muse Code and our API.
Next up 🍉 and Muse Spark open weights releases coming soon.
muse code in beta is live. first coding agent from msl, built on muse spark 1.2.
install: curl -fsS https://t.co/TFXsXfJKW8 | bash
here's what you should know:
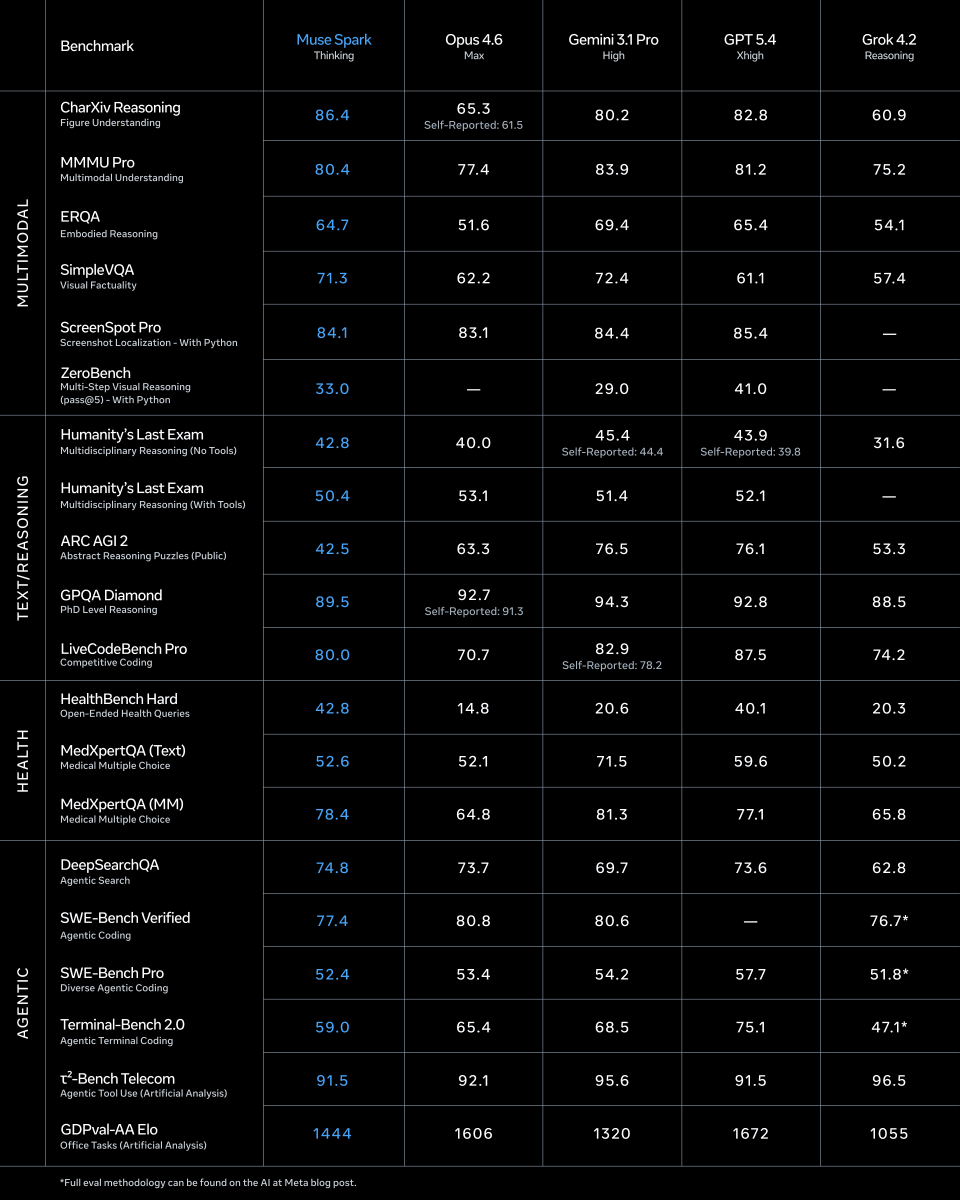
1/ today we're releasing muse spark, the first model from MSL. nine months ago we rebuilt our ai stack from scratch. new infrastructure, new architecture, new data pipelines. muse spark is the result of that work, and now it powers meta ai. 🧵
Mixture-of-Experts (MoE) is a popular #LLM architecture that reduces computation by activating fewer parameters per token. But it brings memory, communication, and control challenges.
💡We introduce MetaShuffling, enabling efficient Llama 4 model inference in production.🔗 Read our latest blog to learn more: https://t.co/bxp2kPE5n1
#PyTorch #OpenSourceAI
what happened yesterday in Atlanta was brutal, tragic & is certainly not an isolated incident by any means. AAPI hate has been rampantly perpetuated & it’s disgusting! I’m heartbroken for the Asian community & my heart is with the loved ones of those we lost. The hate must stop.
A man followed a Chinese-American doctor “spewing a profanity-laced racist tirade as she walked to the subway. ‘Why are you Chinese people killing everyone?’”
There is no place for hatred in our country and these racist attacks must be condemned.
https://t.co/ymyKH6JgR6
Watch this. It shows why we should all do the right thing and stay home to the fullest extent possible. All of us can help slow the spread of the virus, protecting the elderly, the vulnerable, and each other. https://t.co/FgffQrMVB7
“We are fully aligned and continue to work with the US Government to contain the spread of COVID-19, inform citizens, and protect the health of our communities. (1/6)