AI agents are becoming GPU kernel engineers. We're rethinking the compiler stack around them.
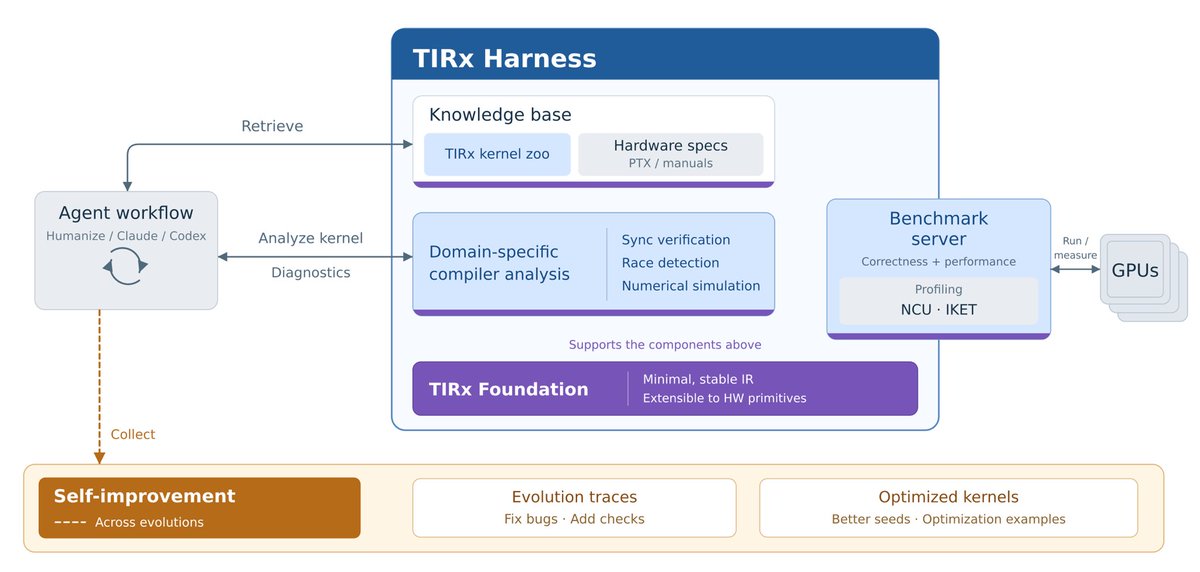
Meet TIRx Harness: an open compiler harness that gives agents an environment to explore, debug, and optimize GPU kernels.
🧱 Minimal stable low-level compiler foundation for predictable GPU programming 🔍 Domain-specific compiler analysis to guide debugging and optimization 📚 Kernel zoo of 60+ kernels and hardware specs to reuse strategies and discover new ones 📊 Remote GPU evaluation for reliable benchmarks and profiling
Agent-built Kimi Delta Attention kernels achieved geometric-mean speedups of 2.94x over FlashKDA (forward) and 6.84x over FLA (backward).
Our bet: the next leap in agentic GPU programming will come from engineering the environment agents optimize in.
Check out our blog: https://t.co/aZo91bGTgz
Great work from the @TileRT_AI and @AIatAMD teams, who got GLM-5.3 to 469 tok/s single-user decode with vLLM on 8× MI355X on @SemiAnalysis_ AgentX.
The run uses a disaggregated setup where vLLM handles prefill and TileRT handles latency-critical decode through vLLM's V1 connector interface.
1/2