After CoRL, I've been stuck at the airport the whole afternoon…
and then something crazy happened 😱
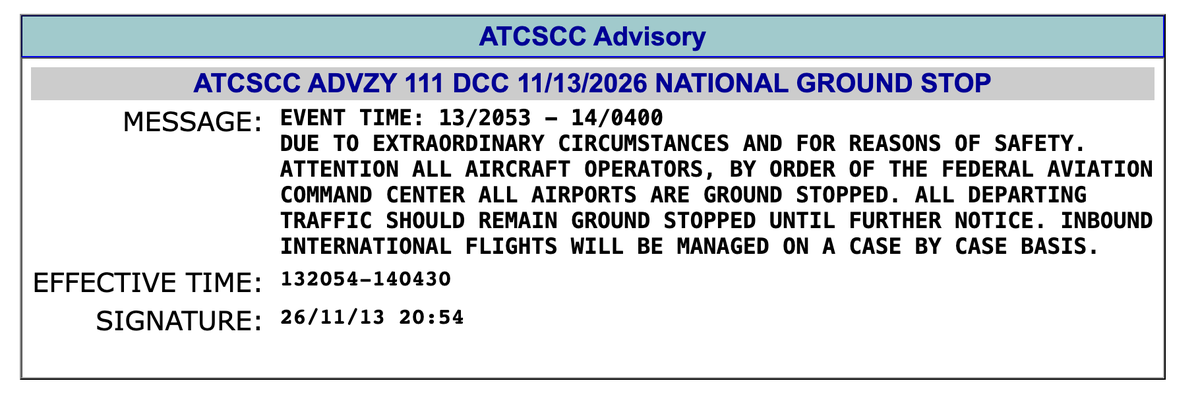
The FAA just issued a nationwide ground stop: every departing flight at every US airport, frozen.
Scary 😱😱😱😱
Issued by the FAA just moments ago, ALL US airports are currently ground stopped. This means NO flights may depart for US airports. Flights already in the air will be allowed to land. This is related to an FAA equipment outage.
So what dies may not be academia itself, but the paradigm of "single labs building static benchmarks." Maybe academia needs to do what LMSYS did with Chatbot Arena: pool resources into shared, live, real-world eval infrastructure.
There's another layer: as models get more capable, real-world evaluation itself gets much harder. Testing long-horizon, complex-scenario capabilities requires expensive hardware and full system integration. Most academic labs can't afford the hardware or build that system in-house.
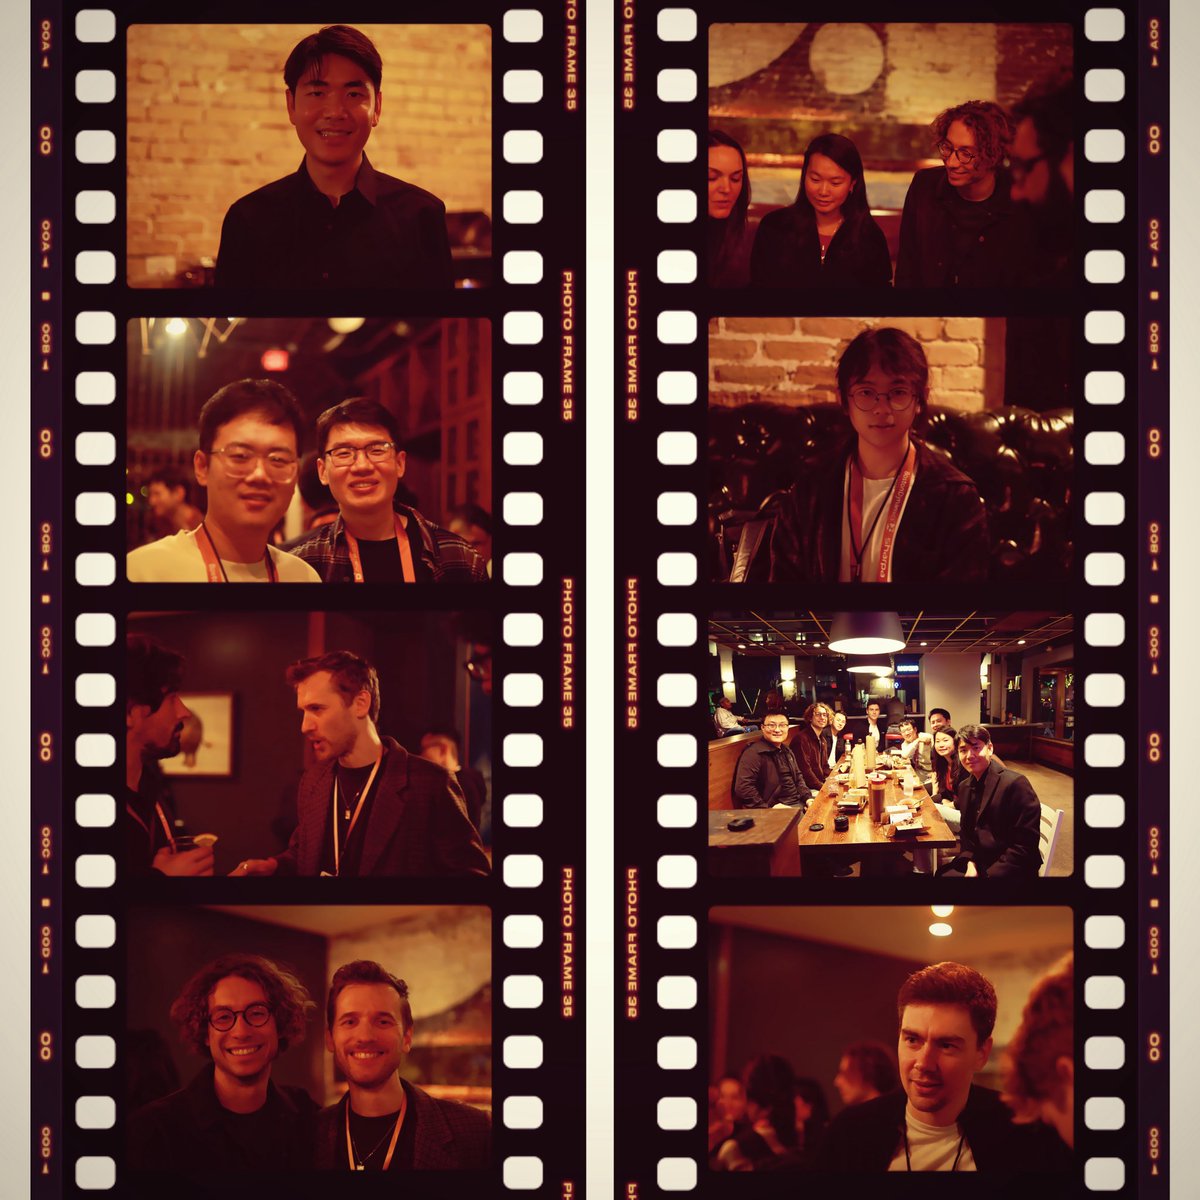
What a night at CoRL 2026 🍸
At Rhoda, I’m a researcher—and occasionally the photographer. 📸
Had so much fun capturing the people and conversations that made this evening special.
200+ guests at Swift’s Attic, and a crowd still talking on the sidewalk after we closed. Thank you to everyone who came out to our Video Models Meet Robotics reception, and to the Rhoda team who pulled it together.
A few favorite shots below. If you spot yourself, say hi! 👋
Want to keep the conversation going? We’re hiring:
https://t.co/CGYUhKj1Kp
#CoRL2026 #RobotLearning #WorldModels #EmbodiedAI
Thank you to everyone who joined our Video Models Meet Robotics reception at #CoRL2026 last night 🍸
200+ came through Swift’s Attic, and the conversations kept going on the sidewalk well after we closed!
Great meeting so many of you in Austin 🤖
Robotaxi’s final boss: someone parked in the middle of the road.
Mine has been inching forward and backward for almost 10 minutes. Called support; they said they can’t remotely drive it.
I’m now a passenger in an infinite loop 😭
Rhoda will be at CoRL 2026 in Austin, and we'd love to see you there.
��� Reception: Rhoda AI @ CoRL, Video Models Meet Robotics
Tuesday, Nov 10, 6:30–8:30 PM
Swift's Attic, 315 Congress Ave. (a short walk from the JW Marriott and Hilton Austin)
Join us for cocktails, food and conversation with fellow researchers and the Rhoda team. It's invite-only and seats are limited, so request your spot here:
https://t.co/PGnUtVfhfN
🎤 Talk: Vincent Sitzmann at the "Do Robots Need World Models?" workshop
Thursday, Nov 12, 11:25 AM
Vincent will share his perspective on one of the field's biggest open questions: what role world models should play in how robots learn to understand and act in the physical world.
See you in Austin!
#CoRL2026 #RobotLearning #WorldModels #VideoModels #EmbodiedAI
1) Most of ICLR papers are AI generated
2) Most of ICLR reviews are AI generated
3) Median score is reject (2). Acceptance ratio is 25%, meaning the SR for this task for the base model is always kept at this ratio, very noisy reward
4) AI conference is too slow as an engine for RSI, 4-6 months to get a reward feedback. At the time when it is accepted, it become trash
1/
A potato chip is thinner than a whisper.
Grip too loose, it slips. Grip too tight, it breaks.
Video models have seen the whole world, but can they learn to feel it?
My friend @Jensen_Yuan has an answer. Meet VTAM 🧵
2/
VTAM is a visuo-tactile world-action model. It plugs tactile streams into a pretrained video transformer with lightweight finetuning: no tactile-language pairs, no separate tactile pretraining.
A model that has watched everything, reaching out to touch for the first time.
3/
~100 demos per task. No tactile or action pretraining. Yet comparable to models pretrained on 30K+ hours of visuo-tactile data, and 6× faster at inference.
Chip pick-and-place, cucumber peeling, whiteboard wiping: 90%, 85%, 95% success.
4/
Touch shouldn't be a passive reading. It's another stream of video.
When a model can foresee what its fingertips will feel next, it starts to understand physics.
(Not an author, just a proud friend who watched this grow 🙌)
5/
📄 https://t.co/ij2pk0NrHR
🌐 https://t.co/Kqo2I3VtBd
💻 https://t.co/4RqlFmHeQ0
Can a world-action model learn to predict touch without any tactile pretraining?
We introduce VTAM, an efficient visuo-tactile world-action model. With ~100 demos per task and no tactile or action pretraining, it is comparable to tactile models pretrained on 30K+ hours of visuo-tactile robot data, and is 6× faster at inference. 🧵
📄Paper: https://t.co/99DkVVGBJD
🌐Web: https://t.co/6drcq3y0oI
Code and data are open source!
💻 Code: https://t.co/McHqMi4DAc
🤗 Data (xArm + GelSight, 3 tasks): https://t.co/kuPR4BeQQ8
When pretraining is so good, the only thing you need is post-train!
So how good it is?
From the log-linear curve for the scaling law, Inking was so accurate! Pretraining is so well designed!
@aliteracy LMAOO I can image this guy would raise $20 million to build an AI-powered smart toilet before realizing he could literally just buy a plunger 😭 And somehow the startup would be valued at $500 million.