Added an icon toggle to shadcn animated 💫
Use it as a toggle (e.g. light/dark) or for auto-reset feedback (copy → success → copy, etc.).
Shoutout to @lonikdev for fixing the deployment bug 🙏
And to @yunique720 for suggesting the blur effect 🙏
🔗GitHub: https://t.co/nkMciB4zcU
added animated fab menu component to shadcn animated💫
✦ grab it for free 👇
✦ fully customizable menu items, FAB, and menu alignment
✦ star on GitHub to support
💡Wanna spend fewer tokens when using AI? Always start fresh for each new task! ⚡Here’s why:
LLMs have no memory: each time you send a new message, the whole conversation history is sent with it and analyzed again.
The longer the conversation gets, the more context the model may need to process.
So, instead of continuing one giant chat for everything, start a new conversation when you switch to a completely different task.
Shorter context means less unnecessary processing and potentially fewer tokens.
LLMs (AI) don't speak our language. We can't just tell them words like "Attention" or "Work." What they need is a one-level-deeper representation of words, which are substrings. For example, the word "Attention" might be split into three different substrings: "At", "tent", and "tion". These substrings are what we call tokens. When you send words, you can generally assume each word will be 2–4 tokens. Every LLM provider, such as Claude or ChatGPT, uses a different tokenizer, but the numbers are more or less the same.
What we pass to the LLM are called "input tokens," and every token is counted and priced. There are also "output tokens"—these are tokens that are generated by the LLM itself. For example, if we send the word "Attention", the LLM might output the following tokens: "is", "all", "y", "ou", "ne", "ed". These are counted and priced as well, meaning you pay for both input and output tokens.
When we talk to an LLM, we see that its response is printed as it is generated rather than appearing as a whole sentence right away. That's because an LLM outputs one token (one subword) per turn, not the entire text at once. This process of sending data from the LLM to the user as each token is generated is called streaming. ⚡
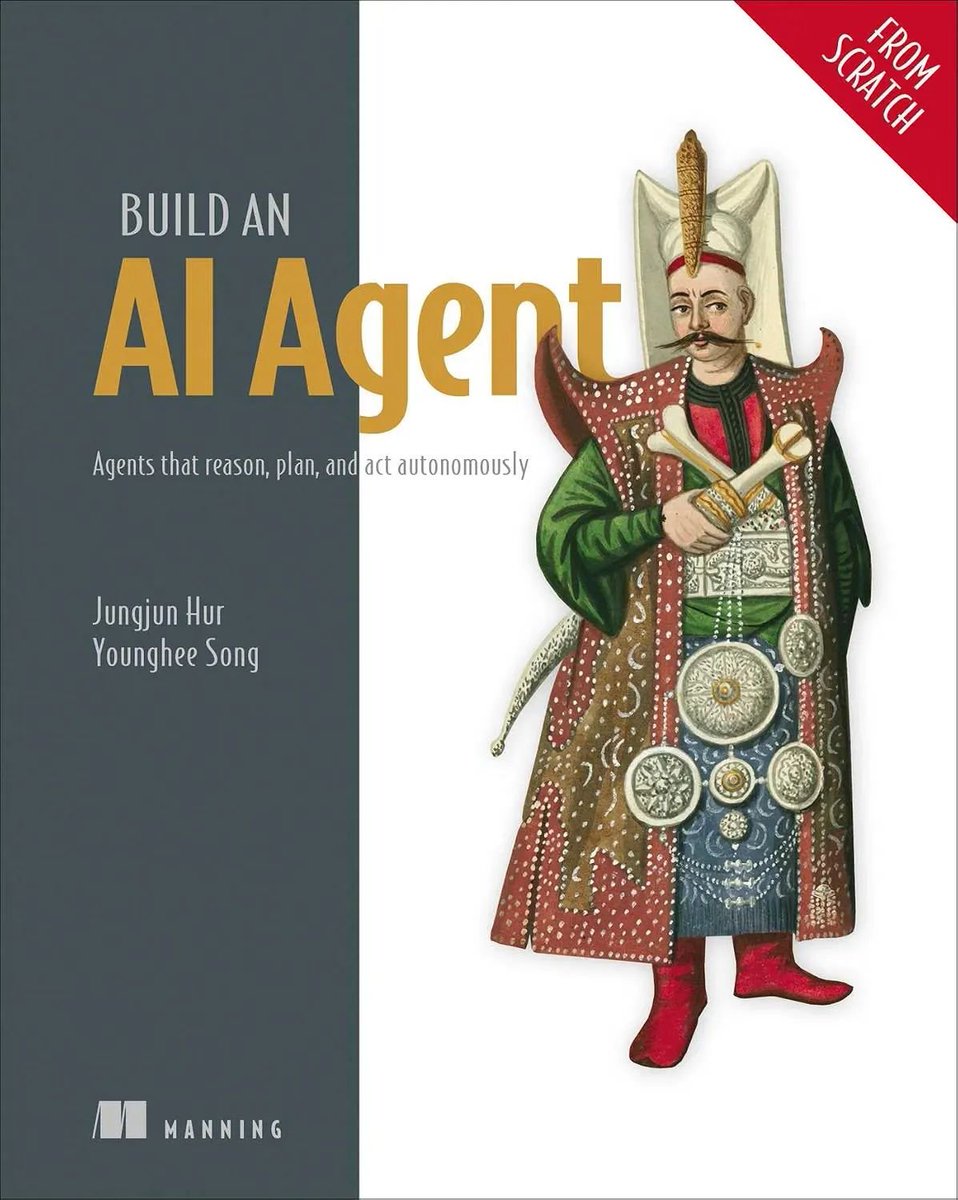
The book "Build an AI Agent (From Scratch)" is so good. It teaches you about the agentic era we are living in. Instead of treating AI agents like a black box, it distills every concept and teaches you how to build one from the ground up. AI agents function similarly to the human body: the LLM is the brain that makes decisions, while tools are the muscles and organs that execute the brain's demands. If you use AI agents on a daily basis and want to understand their inner workings, I strongly recommend this book. A basic knowledge of Python and a general understanding of LLMs are sufficient to get through it. ⚡
Themer library adds theming to your app — same idea as next-themes on Next.js, built specifically for TanStack Router / Start 🌴.
Check it out https://t.co/OFlkFKzjYC
@tan_stack
Prestige update:
.md files are now parsed and rendered as HTML pages with a proper TanStack route. 🌴
Click star ⭐️ if you like it — very appreciated. (link below 👇)