I came back in time to witness the progress the #Gemini team has made in such a short period of time. 3.8 feels like a solid step up in day to day agentic coding workflows. Looking forward to hearing the community’s feedback, developers, enterprise, and consumers!
I mentioned that my garage door was making a sound.
An American immediately said, "I got a guy."
He did not ask what the sound was. He did not ask what kind of door. He produced a guy on the basis of the word garage.
I asked who the guy was.
He said, "Just a guy."
He did not have a company name. He had a first name and a phone number in his phone saved as "Mike Garage."
That is the contact name. Mike Garage. As though Garage is his surname. As though there is a family.
I asked how he found this guy.
"My brother-in-law used him."
I asked if the brother-in-law was satisfied.
He thought about it. Then he said, "He's still standing."
The house is still standing. That is the entire review.
Inside I said: THEY DO NOT KEEP RECORDS. THEY KEEP LOYALTIES.
I called Mike Garage. He answered from inside a vehicle. There was wind. He said he could come Tuesday between eleven and four.
Between eleven and four. A window of five hours. In my country this would be a scandal. Here it is generous. He gave me a window at all. Some guys do not give you a window. Some guys say "Tuesday" and that is the whole appointment.
He came at 1:40.
He fixed it in twenty minutes. He charged me less than I expected and he did not take a card, only cash or an app I had never heard of.
Before leaving he looked at my water heater, which I had not mentioned, and said, "That's gonna go."
I asked when.
"Couple years."
I asked what I should do.
He said, "I'll give you a guy."
He gave me a guy. Mike Garage has a guy. The guy has a guy. There is a network beneath this country made entirely of men named after their function, and none of them advertise, and all of them are busy.
Inside I said: THERE IS A SECOND NATION HERE. IT HAS NO SIGNS. IT IS ENTERED ONLY BY INTRODUCTION.
I have been given four guys since.
I have a guy for trees.
I did not know I needed a guy for trees.
I have trees now, apparently. They are my responsibility. A man named Rick told me so and then left.
may 2026: prompting is over. it's all about loops
june 2026: loops are over. it's actually all about graphs - figuring out the sequence of actions that claude takes to loop itself
july 2026: we've created a formalized "language" system for creating these graphs - it first goes through a special program called a "compiler" and then it -
hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final
((1+xy)^3 z + y^2 (1+xy) (4+3xy), y + 3 x (1+xy)^2 z + 3 x y^2 (4+3xy), 2 x - 3 x^2 y - x^3 z): \C^3\to \C^3, has jacobian determinant -2, and sends (0, 0, -1/4), (1, -3/2, 13/2), and (-1, 3/2, 13/2) to (-1/4, 0, 0)
"When art critics get together they talk about Form and Structure and Meaning. When artists get together they talk about where you can buy cheap turpentine."
Numerics is turpentine for LLM researchers/engineers.
DeepSeek [1] uses elements of the 2015 reinforcement learning prompt engineer [2] and its 2018 refinement [3] which collapses the RL machine and world model of [2] into a single net through the neural net distillation procedure of 1991 [4]: a distilled chain of thought system.
REFERENCES (easy to find on the web):
[1] #DeepSeekR1 (2025): Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. arXiv 2501.12948
[2] J. Schmidhuber (JS, 2015). On Learning to Think: Algorithmic Information Theory for Novel Combinations of Reinforcement Learning Controllers and Recurrent Neural World Models. arXiv 1210.0118. Sec. 5.3 describes the reinforcement learning (RL) prompt engineer which learns to actively and iteratively query its model for abstract reasoning and planning and decision making.
[3] JS (2018). One Big Net For Everything. arXiv 1802.08864. See also US11853886B2. This paper collapses the reinforcement learner and the world model of [2] (e.g., a foundation model) into a single network, using the neural network distillation procedure of 1991 [4]. Essentially what's now called an RL "Chain of Thought" system, where subsequent improvements are continually distilled into a single net. See also [5].
[4] JS (1991). Learning complex, extended sequences using the principle of history compression. Neural Computation, 4(2):234-242, 1992. Based on TR FKI-148-91, TUM, 1991. First working deep learner based on a deep recurrent neural net hierarchy (with different self-organising time scales), overcoming the vanishing gradient problem through unsupervised pre-training (the P in CHatGPT) and predictive coding. Also: compressing or distilling a teacher net (the chunker) into a student net (the automatizer) that does not forget its old skills - such approaches are now widely used. See also [6].
[5] JS (AI Blog, 2020). 30-year anniversary of planning & reinforcement learning with recurrent world models and artificial curiosity (1990, introducing high-dimensional reward signals and the GAN principle). Contains summaries of [2][3] above.
[6] JS (AI Blog, 2021). 30-year anniversary: First very deep learning with unsupervised pre-training (1991) [4]. Unsupervised hierarchical predictive coding finds compact internal representations of sequential data to facilitate downstream learning. The hierarchy can be distilled [4] into a single deep neural network. 1993: solving problems of depth >1000.
one reason it’s fun to talk to Claude is because it starts conversations by repeating conventional platitudes but as soon as you press with “is that real” it’ll go “haha, no, you caught me” and then ruthlessly mock entire disciplines for being built on foundations of sand
@_xjdr "Hmm, our results table looks a bit off because we've only hit sota on 1/11 benchmarks. Shall we spend another 6 months on post-training?"
"Or we could..."
...and Harbout Seal "Chunky" enjoying an extended lunch break nearby Albert Bridge on the Battersea Park side. #sealwatch#inthethames#seal#Batterseapark
Image credit: photo 1 by @lukede0, photo 2 by Olivia
We're not done with Llama 1B & 3B! So excited to see what the community will build on the quantised variants of the 1B and 3B!
We're releasing LoRA adapter-based & SpinQuant based variants of the 1B and 3B which will enable 70% TTFT reduction, 2x boosts in TTIT on device. Go go!
We want to make it easier for more people to build with Llama — so today we’re releasing new quantized versions of Llama 3.2 1B & 3B that deliver up to 2-4x increases in inference speed and, on average, 56% reduction in model size, and 41% reduction in memory footprint.
Details on our new quantized Llama 3.2 on-device models ➡️
https://t.co/ea32Takvjh
While quantized models have existed in the community before, these approaches often came at a tradeoff between performance and accuracy. To solve this, we Quantization-Aware Training with LoRA adaptors as opposed to only post-processing. As a result, our new models offer a reduced memory footprint, faster on-device inference, accuracy and portability — while maintaining quality and safety for developers to deploy on resource-constrained devices.
The new models can be downloaded now from Meta and on @huggingface.
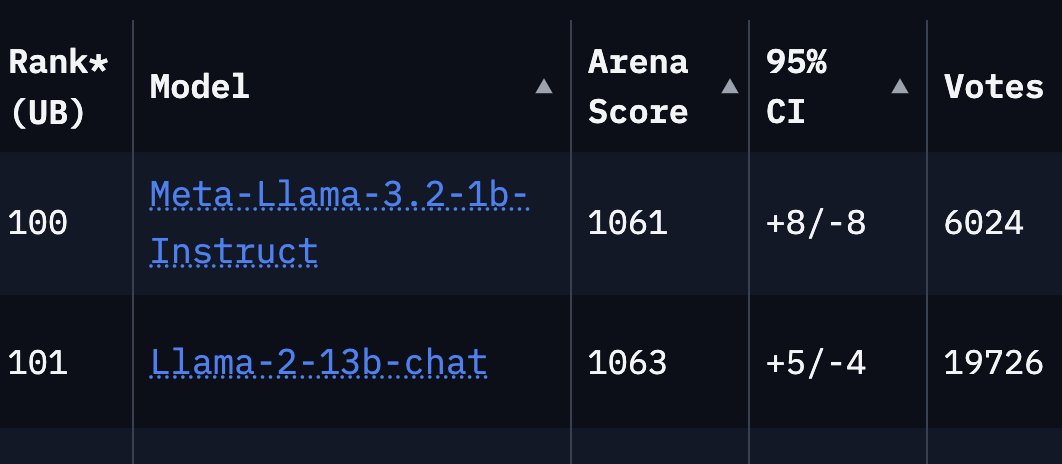
It’s great to see the 1B performing well head to head against previous Llamas! It’s hard from the eye of the storm to appreciate sometimes, but the year over year progress (in this case 13B -> 1B iso lmsys perf) can be astounding. Onward!
the new 1 billion parameters Llama model (version 3.2) is head-to-head with the 13 times larger version of one years ago (llama 13B version 2) on lmsys chatbot arena
exciting to see such 10x improvements on challenging benchmark
it's an amazing sign for small/local/open models
With Llama 3.2 we released our first-ever lightweight Llama models: 1B & 3B. These models empower developers to build personalized, on-device agentic applications with capabilities like summarization, tool use and RAG where data never leaves the device.